
Month: November 2025
Blog
Dedicated Servers: Slashing iGaming Hosting Costs
iGaming platforms run hot, late, and global, so the infrastructure choices you make can materially affect gross margin. The question is simple: where does the iGaming dedicated server model beat utility cloud on total cost of ownership without compromising performance and efficiency?
Choose Melbicom— 1000+ server configurations — 21 Tier III & IV data centers — 40 CDN PoPs across 6 continents |
 |
How Can Dedicated Servers Lower TCO?
An iGaming dedicated server can lower total cost of ownership when steady utilization makes fixed capacity economical after bandwidth, licenses, support, and operations are included. Compare that total with cloud commitments and autoscaling under the same workload; dedicated hosting is not always cheaper for variable demand.
Usage-based cloud bills can include compute time, storage I/O, inter‑AZ and regional traffic, and egress. A fixed dedicated rental covers the contracted resources, not every associated expense: traffic allowances, overages, managed services, and software licenses still matter. Cloud commitment discounts can also change the comparison, while unused committed capacity can erode savings.
Grand View Research’s current market estimates value online gambling at $88.0 billion in 2025 and forecast 11.0% annual growth from 2026 to 2033, with sports betting the largest sub‑segment in 2025. That market context does not establish steady utilization for an individual platform; size infrastructure from measured workload demand rather than industry growth.
The second half of the equation is predictability. IDC’s October 2024 analysis, citing its Cloud Pulse 4Q 2023 survey, says about half of surveyed cloud buyers spent more than expected in 2023 and 59% anticipated overruns in 2024. Those are historical results and expectations, not a current overspending rate. Fixed rental charges simplify one part of forecasting, not the entire operating budget.
An illustrative iGaming hosting comparison
| Illustrative hosting charges (USD) | Dedicated server | Cloud instance |
|---|---|---|
| Assumed monthly hosting charge | $250 (assumed constant) | $400 (assumed constant) |
| Hosting charges – 1 year | $3,000 | $4,800 |
| Hosting charges – 3 years | $9,000 | $14,400 |
| Modeled monthly variation | None assumed | None assumed |
Both monthly charges are hypothetical assumptions held constant for 36 months, not Melbicom offers, comparable supplier quotes, or a full TCO calculation. The totals exclude traffic and overage charges, CDN delivery, licenses, administration, staff time, migration, and redundancy. Equivalent capacity and performance have not been established; the lower assumed input—not the billing model alone—produces the difference.
Predictable Costs vs. Surprise Bills: How Flat‑Rate Pricing Improves Budget Control
Storage, egress, and cross‑region traffic need separate budget checks. A Backblaze-commissioned Dimensional Research survey conducted in May–June 2025 found that 95% of its 403 respondents reported unexpected cloud storage costs. Participants managed cloud storage strategy and budgets at companies storing over 250 TB in public cloud. This vendor-sponsored, storage-specific sample does not establish the incidence of surprise bills across all cloud computing or iGaming workloads.
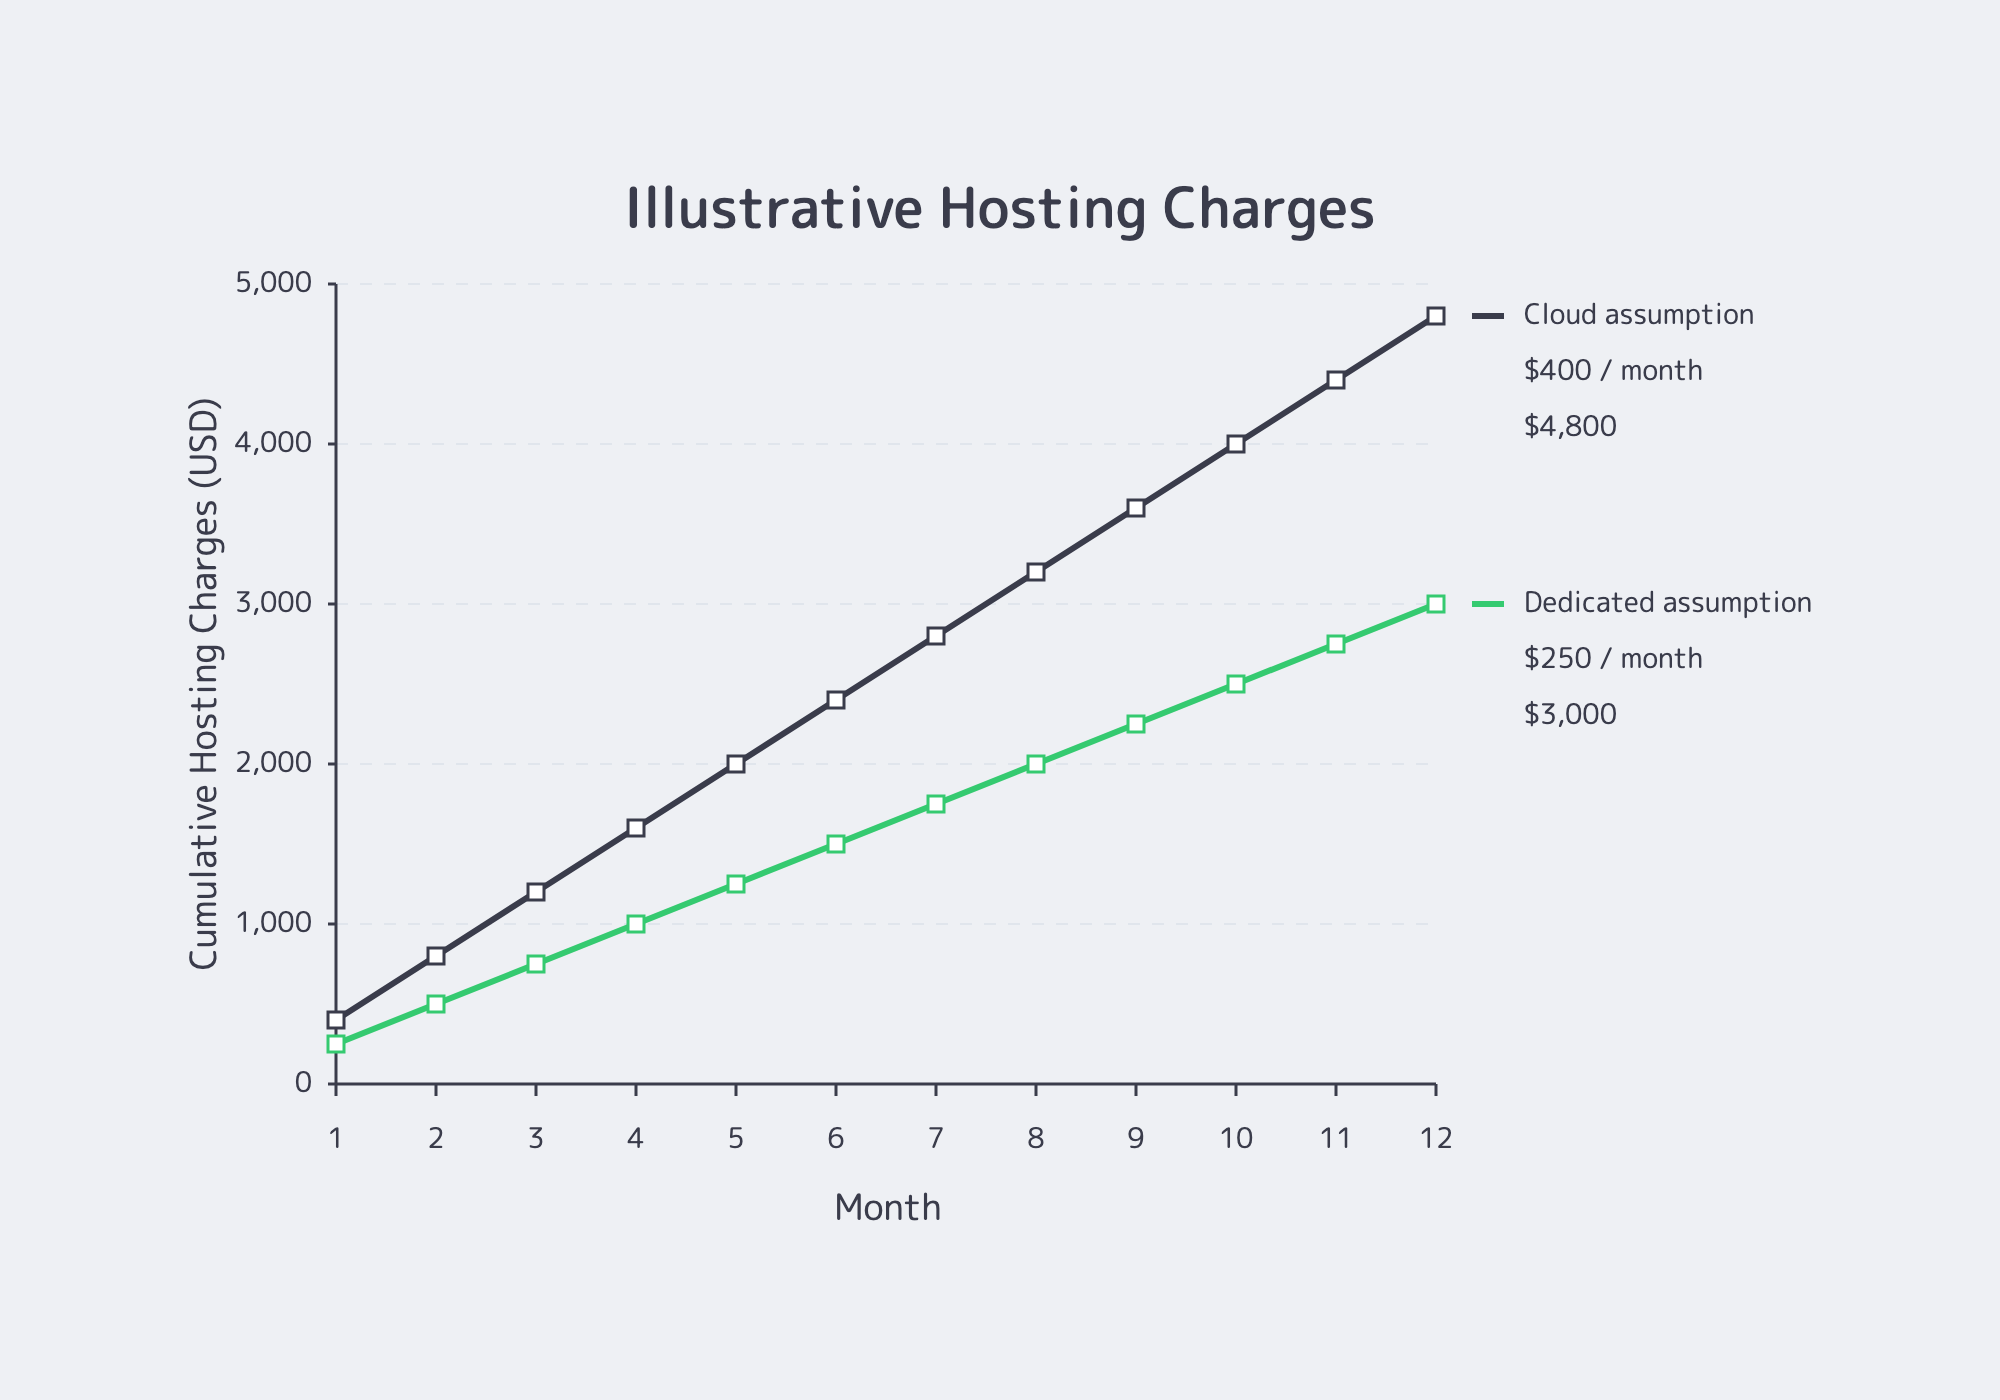
Under these assumptions, cumulative hosting charges differ by $1,800 after 12 months. It models neither demand variability nor an inherent platform cost advantage.
A fixed rental makes the contracted server charge predictable, but extra capacity and usage-based services still need budgets. To offload eligible content, put a CDN in front of your origins. Melbicom’s CDN operates in 40 PoPs across 35 countries. Cache hits can reduce origin traffic; cache misses and non-cacheable requests still reach the origin, and CDN delivery has its own charges. Compare combined origin and CDN costs rather than assuming offload is free.
Bandwidth headroom is also important: Melbicom offers up to 200 Gbps per server for workloads such as live‑dealer video and logs/telemetry replication. Port speed is not a traffic allowance: check the selected plan’s included transfer, unmetered terms, and any usage charges when budgeting.
Balancing Hosting Costs and Performance
Hybrid scaling for peak events (baseline on dedicated, burst tactically)
The working solution is frequently a combination: run a stable base load on dedicated machines and scale suitable stateless front ends or microservices in the cloud during peak events. That can provide elastic headroom for the Champions League final or the Super Bowl, but include inter-platform traffic and operational complexity in the calculation. Uptime Institute’s February 2025 analysis, based on its 2024 survey, describes public clouds alongside on-premises facilities, rather than a wholesale cloud exit.
Place origins in well‑peered metros, measure paths to critical markets, front eligible content with a global CDN, and keep backend services private where possible. Melbicom’s footprint comprises 21 Tier III/IV data centers, including São Paulo and Marseille coming soon. Its 1000+ ready‑to‑go server configurations can be activated within 2 hours at available locations; plan extra lead time for custom capacity.
Automation can reduce management overhead
Configuration management and infrastructure as code (IaC) can automate software setup on dedicated servers after provisioning. Keep that separate from ordering or canceling physical capacity:
- After a server is provisioned, use configuration management and CI/CD workflows to install software and join it to a cluster.
- Scale physical capacity in planned steps, accounting for deployment time, billing periods, and cancellation terms; use provider APIs only for documented operations.
- Use CPU saturation, tail latency, and queue depth to trigger capacity reviews, and schedule additions ahead of sports seasons and promotions.
FinOps usage optimization connects rightsizing and automation with cost and performance goals; the tooling and operational responsibilities still differ between platforms. Melbicom provides 24/7 technical support and server administration services. Confirm administration scope and pricing; full application management is not necessarily included.
Capacity planning: enough headroom, not waste
iGaming capacity planning should be fact-based:
- Right‑size by region: measure peak concurrency by region and event schedule rather than over‑building a single mega‑cluster; compare paths from Melbicom’s server locations to players and payment services rather than assuming geographic proximity guarantees low latency.
- Incremental scale‑out: add servers as measured concurrency and resource demand grow, with headroom for failures. Melbicom offers monthly billing with a one-month minimum payment period; check billing and cancellation terms before planning seasonal reductions.
- Move bulk bytes to the CDN where content is cacheable, so origin capacity can focus on dynamic interactions while retaining enough headroom for cache misses.
Performance can affect ROI
Single‑tenant servers isolate host resources from other customers. Running directly on the hardware also avoids a provider-managed hypervisor, but applications, storage, operating systems, and network paths still affect latency. Dedicated hosting alone does not guarantee a particular end-to-end response time.
Measure tail latency, timeouts, and completed transactions under comparable load before and after a change. Check business outcomes separately; reduced jitter does not establish a proportional increase in session length, betting revenue, or hold rate.
Why Revisit Cloud Repatriation?
Selective repatriation can suit measured workload economics, operational control, or data‑residency requirements, while other services benefit from cloud elasticity. IDC’s 2024 analysis describes movement of selected workloads rather than wholesale cloud exits. Location alone does not establish compliance.
In an October 2024 update, 37signals reported reducing its annual cloud bill from a $3.2 million run rate to $1.3 million and forecast more than $10 million in five-year savings from its combined compute and planned storage exit. It reused existing data-center racks and power capacity without enlarging its operations team. This was a SaaS deployment on owned hardware in colocation, not an achieved five-year result or proof that rented dedicated capacity will reproduce those savings.
iGaming Hosting Solutions Checklist
- Lock in a predictable base. Size fixed-price dedicated nodes for measured baseline demand from durable workloads such as accounts, RNG/odds, and payments, with tested peak and failure headroom.
- Burst only the edge. Use cloud autoscaling for suitable stateless API and presentation tiers during major events, then scale them down afterward; account for backend limits and inter-platform traffic.
- Reduce avoidable egress. Serve eligible content from the CDN, measure cache-hit rates, and budget for origin transfer, cross-region traffic, and CDN delivery.
- Automate capacity turns. Automate server configuration and schedule physical capacity changes around sports seasons and promotions, allowing for provisioning and billing terms.
- Check bandwidth terms. Match port capacity to peak demand and verify included transfer, unmetered conditions, and overage charges for replication and video.
- Measure ROI in user terms. Measure bet latency, timeouts, and completed transactions alongside operating costs; test business effects rather than attributing session length or hold-rate changes to hosting alone.
- Keep options open. Allocate workloads by measured economics, while accounting for hybrid networking and management overhead.
Where Does Melbicom Fit When You Make “Dedicated Server vs Cloud” Trade‑Offs?
An iGaming dedicated server from Melbicom is worth evaluating when steady demand supports fixed-capacity economics. Melbicom offers 1000+ ready‑to‑go server configurations with activation within 2 hours at available locations and bandwidth of up to 200 Gbps per server. Compare server, transfer, and support costs against an equivalent cloud deployment.
Melbicom’s Tier III/IV data centers comprise 21 facilities across 19 cities and 17 countries, including the coming-soon São Paulo and Marseille facilities. Use the CDN across 40 PoPs to offload eligible content, and include CDN delivery in the combined cost calculation.
What’s the Bottom Line?
When your platform runs continuously, a flat‑rate dedicated model can be a strong financial option if measured utilization justifies the capacity and the full operating cost is competitive. The cloud remains valuable for experimentation and short bursts, while commitments and autoscaling can improve its economics. Compare equivalent performance, resilience, traffic, and operational responsibilities rather than assuming either billing model always wins.
A forward‑looking plan doesn’t pick a single winner; it allocates workloads—dedicated for the stable spine, cloud for elasticity, CDN for eligible content, and S3‑compatible object storage for media, logs, and backups, ideally with clear pricing and data residency. Evaluate this combination against actual demand and operating costs, and assess providers on time‑to‑deploy, per‑server bandwidth, PoP coverage, and support depth rather than just GHz or core counts.
Build predictable iGaming infrastructure
Deploy dedicated servers with global CDN and 24/7 support to cut bill shock and keep latency low across peak events.
Get expert support with your services
Blog

Lightning-Fast iGaming: Dedicated Hosting for Low-Latency Performance
In live sportsbooks and interactive casino tables, the systems that update odds, deal cards, or close spins first determine who wins the session—and who earns repeat business. Any failure to refresh odds or process live bets promptly can undermine user confidence and expose operators to financial risk. Consistency across regions is just as critical: bettors in Frankfurt and Los Angeles must see the same game state at the same time.
Why Low Latency Is Non‑Negotiable in the iGaming Space
Latency is the time it takes for a packet to travel between a client and a server. Distance is the first constraint: a request over about 100 miles could take roughly 5–10 ms, while a request over about 2,200 miles can take 40–50 ms before handshakes, TLS, rendering, or application code add more delay. For iGaming hosting, the practical architecture goal is simple: place compute near players and remove avoidable jitter everywhere else.
Choose Melbicom— 1000+ ready-to-go server configs — 21 global Tier IV & III data centers — 40 CDN locations in 35 countries |
|
Melbicom iGaming hosting uses single-tenant dedicated servers in 21 Tier III/IV locations, supplemented by a CDN in 40 locations across 35 countries, 1000+ ready-to-go server configurations, and up to 200 Gbps per-server bandwidth. This footprint keeps the critical path short and deterministic while pushing heavy content to the edge.
How Does iGaming Hosting on Dedicated Servers Cut Latency?
Single‑tenant dedicated servers eliminate both resource contention and hypervisor overhead, whereas virtual machines add both. With no noisy neighbors, there are no surprises from stolen CPU cycles, shared NIC interrupts, or jitter caused by an overselling host. This is why operators keep key paths—odds engines, RNG, wallet, settlement—on core servers, while bursty or experimental web front ends are pushed to the cloud.
Hardware matters:
- NVMe over PCIe provides deep queue parallelism and microsecond-class latency for hot writes. Odds recalculation, wallet writes, and session-state updates can complete before a human player notices a delay.
- High‑clock Xeon and EPYC SKUs keep single‑threaded bet placement snappy while parallelizing event ingestion, pricing, and streaming workloads.
- Keep hot odds, session state, and leaderboards off disk, reserving HDDs only for cold reads and cold data changes.
- Size NICs to 10/40/100/200 Gbps based on concurrency and streaming requirements and keep network paths short through local peering.
iGaming Infrastructure: Dedicated Servers vs. Cloud vs. VPS

Concise answer: choose dedicated servers for the latency-critical path. Use cloud elasticity at the edge for marketing landers, stateless APIs, or temporary web capacity. VPS inherits noisy-neighbor risk from shared virtualized infrastructure and is more likely to cap I/O or throughput under contention.
| Significant factor | Cloud hosting (virtualized) | Dedicated Computing (single‑tenant) |
|---|---|---|
| Latency & jitter | Variable: tail latency can spike under load due to hypervisor overhead and noisy neighbors. | Deterministic: no hypervisors or neighbors; ideal for bets and streams. |
| Throughput under load | Frequently capped; egress fees promote off-platform delivery. | High sustained throughput of up to 200 Gbps per server at Melbicom for price feeds, streams, and settlement. |
| Control & locality | Hardware is less transparent; placement may vary by region. | Complete control (root/IPMI) and fine-grained placement for performance and compliance. |
Table. Dedicated servers vs cloud for latency-constrained iGaming workloads.
Where Does iGaming Latency Come From and How Can You Reduce It?
iGaming latency comes mainly from physical distance, congested or undersized network links, storage stalls, and application tail latencies. Reduce it by placing dedicated server clusters near player regions, keeping transactional paths on single-tenant hardware, sizing NICs with headroom, offloading media to CDN edge locations, and decoupling analytics or blockchain work from bet placement.
Distance: deploy at the edge & route by proximity
Every handshake is amplified by distance. Use regional hubs (for example, EU, US, and APAC) with global load balancing or anycast so a bet from Frankfurt lands in Europe and a bet from Atlanta lands in North America; then keep regulated data resident where audits require it. Melbicom’s 21 data center locations and CDN in 40 CDN PoPs across 35 countries build proximity into the design and help interactions stay below the point where users begin to perceive delay.
Bandwidth & queuing: remove choke points
Saturated links buffer packets and stretch tail delays. Even 1–10 Gbps links can queue packets when traffic spikes, so headroom on interfaces is essential. Size NICs to concurrency requirements, expand to 40/100/200 Gbps where needed, and use peering to reduce hop count. To keep the game origin lean, offload large media or update delivery through Melbicom’s CDN.
Storage stalls: keep hot paths in memory and NVMe
Cache session state and odds in RAM, then write behind to NVMe; NVMe’s microsecond‑class latency makes on‑commit durability realistic without stalling user paths.
Application tail latencies: isolate and decouple
For live analytics, personalization, or fraud models, decouple compute from the betting path: write the transaction and immediately acknowledge it on the core service, then mirror events to separate analytics clusters (GPU‑enabled if needed). If you integrate blockchain components (wallets or provably‑fair attestations), buffer transactions behind queues so on‑chain latency never blocks gameplay.
Optimizations That Move the Needle Today
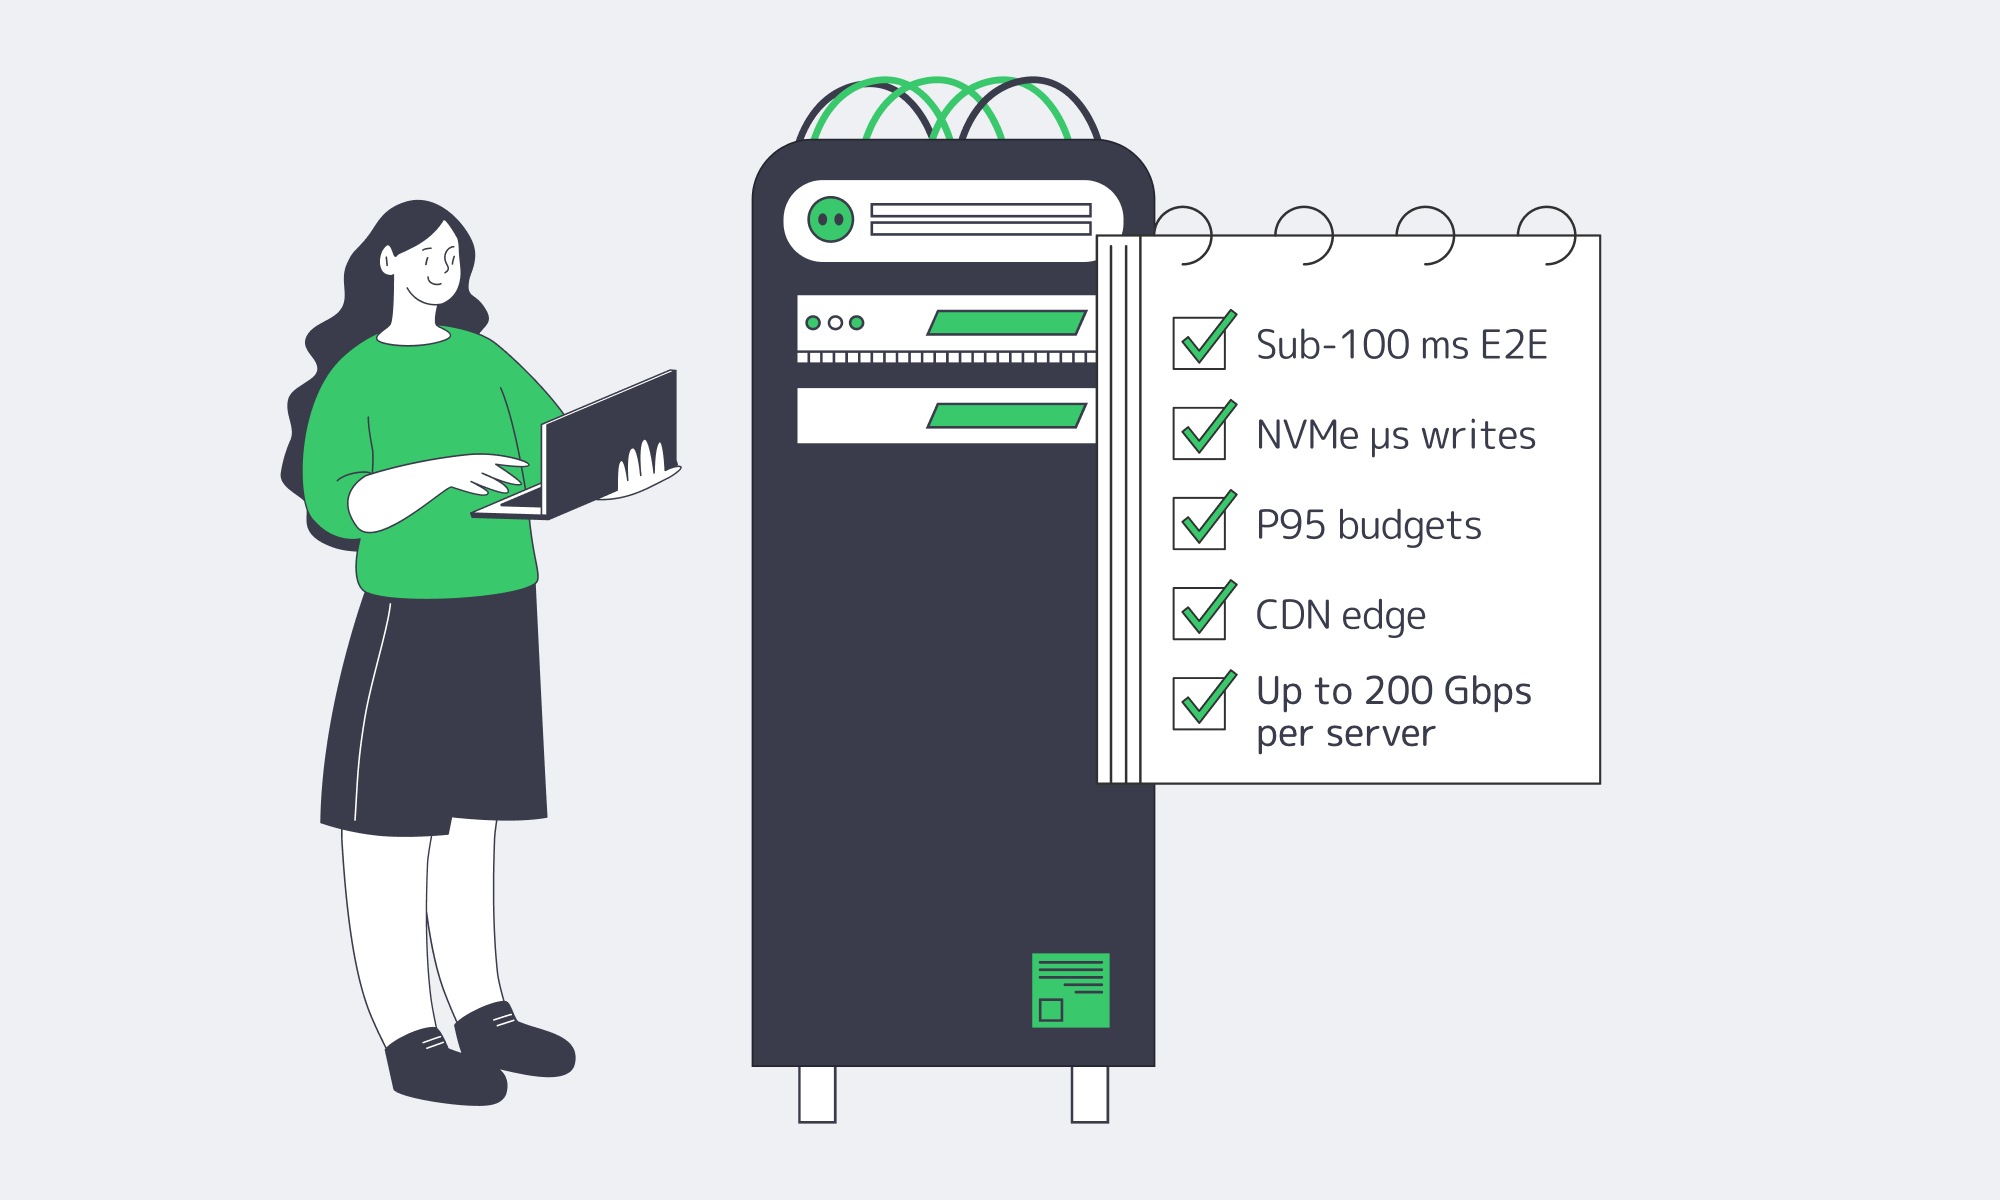
Set realistic latency targets for each region. Traffic within a region should feel instantaneous to players; globally, keep interactions below the threshold where delay is perceptible. A practical north star is sub‑100 ms end‑to‑end latency for the vast majority of interactive actions, with P95/P99 budgets enforced per region.
Optimize for determinism, not averages. Track and budget tail latencies explicitly, focusing on the worst‑case response times for bets, odds updates, table actions, and withdrawals. When P95 latency drifts out of bounds, scale horizontally or add capacity before users feel the impact. We recommend keeping core clusters at roughly 60–70% CPU and memory utilization during peak windows and using thresholds to trigger automatic provisioning of additional nodes.
Exploit the edge for everything that isn’t transactional. Offload everything non‑transactional to the edge by serving static assets through Melbicom’s CDN and storing media in S3‑compatible object storage (NVMe‑accelerated, up to 500 TB). Let the CDN fetch those objects instead of your game servers so the critical path stays lean and avoids extra origin round trips.
Design for failover and proximity. Launch in your two most important regions first, then expand, keeping warm standbys where needed so traffic can be drained and rerouted cleanly when a region is under pressure or being tested.
iGaming Hosting Solutions vs. Unpredictable Cloud Spikes
Sports calendars and promotions create step-function demand. You don’t need infinite servers; you need predictable activation and automation. Melbicom has 1000+ ready-to-go server configurations, 2-hour activation, and API-driven provisioning so operators can pre-stage capacity in the right location and scale based on telemetry (queue depth, P95 latency, cache hit rate). Combine this with container orchestration and images optimized to warm up quickly to keep tail latencies steady as traffic doubles in minutes.
For interactive add-ons such as real-time chat, watch betting social features, and micro-competitions, latency budgets should stay tight even as features expand. Because delays in real-time features can hurt engagement and trust, design these services as independent, horizontally scalable microservices whose load never interferes with bet placement.
Key Recommendations for Low‑Latency iGaming Hosting
- Distribution: Stand up clusters in several regions, steer users by latency, and keep regulated data local by default.
- Single‑tenant core placement: run odds, RNG, payments, and stateful databases on dedicated single‑tenant servers.
- Ultra fast hardware stack: Use NVMe SSDs with microsecond-class latency, current multi-core CPUs, large RAM, and concurrency-sized NICs.
- High‑bandwidth networks & CDN offload: avoid queueing by giving links headroom, reducing hops, and serving assets as close to users as possible.
- Scale under contention: use automation with tail-aware SLOs, scale on P95/P99, and pre-stage capacity for fixtures and promotions.
Conclusion: Build for Speed You Can Prove

Low latency in iGaming is not a trick; it is a system property built from proximity, single‑tenancy, fast storage, and generously provisioned network capacity. The strongest platforms keep bet processing and state on dedicated hardware, move nonessential workloads to the edge, and expand regionally. The result is measurable: fewer high‑percentile outliers during peak periods, fewer suspended markets, and more settled bets per minute, all contributing to a smoother user experience.
This foundation becomes more valuable as new interaction models—live micro‑markets, watch‑bet chat, AR tables—continue to raise expectations. Global proximity and consistent single‑tenant performance let you keep adding features without introducing additional latency. When money is measured in milliseconds, the right hosting posture becomes a competitive advantage.
Launch low‑latency iGaming hosting
Provision dedicated iGaming servers in 21 global data center locations with up to 200 Gbps per-server bandwidth and CDN delivery in 40 CDN PoPs across 35 countries for fast activation and responsive gameplay worldwide.
Get expert support with your services
Blog
Deploying Bare Metal in Brazil for AI/ML
The IX.br exchange in São Paulo is a major interconnection hub for Brazilian networks. The dense networks and fiber concentrated in the area provide an advantage for AI/ML teams considering modern bare metal in Brazil. Shorter paths can reduce network delay, but response time also depends on routing, congestion, and model execution. Local hosting supports data-location control; it does not, by itself, establish LGPD compliance. Melbicom’s São Paulo server location remains available for preorder, so confirm the configuration and launch timing before planning production traffic.
Host in LATAM— Reserve servers in São Paulo — 6 CDN PoPs · 5 LATAM countries — 21 Tier III & IV DCs globally |
 |
Why Deploy AI/ML on São Paulo Bare Metal?
Arizton’s April 2026 investment analysis estimates Brazil’s data center market at US$6.7 billion in 2025 and projects US$8.12 billion by 2031. These are market estimates and forecasts, not a sizing rule for an individual AI deployment.
The advantages of placing AI on bare metal in Brazil:
- Exclusive hardware for AI workloads: Bare metal provides sole access to CPU cores, RAM, and installed GPUs. Running the OS directly avoids a shared host hypervisor, but training and inference performance still depends on the model and configuration.
- Proximity to IX.br São Paulo: Direct interconnection can shorten paths to Brazilian ISPs. Measure round-trip latency, packet loss, and jitter from the networks your users actually use rather than assuming a fixed improvement.
- Data-residency control: Keeping selected processing and storage in Brazil can simplify residency records, but LGPD compliance requires lawful processing, security measures, data-subject rights, and appropriate handling of international transfers.
- Predictability and customization: With full control over the OS, compatible drivers, frameworks, and network layout, you can tune specific model stacks and data pipelines. Costs still depend on the selected hardware, traffic, and operations.
Brazil Deploy Guide— Avoid costly mistakes — Real RTT & backbone insights — Architecture playbook for LATAM |
 |
Which CPUs and GPUs Suit AI/ML?
For a dedicated server in São Paulo, choose CPUs and GPUs using benchmarks of the target model, batch size, and concurrency. Match CPU cores, RAM, and accelerator memory to the workload. Melbicom’s São Paulo capacity is preorder-based; confirm the exact hardware and launch timing before committing.
AMD EPYC, AMD Ryzen, and Intel Xeon are custom configuration options, with optional GPUs. CPU family alone does not establish model throughput or latency. Confirm the GPU model, VRAM, driver compatibility, power and cooling, and the allocated port speed in the quotation. Plan headroom from measured utilization and expected demand rather than an industry-wide training-compute doubling rate.
How Local Peering Can Reduce AI Latency
Long-distance paths can increase RTT for requests and real-time data feeds. Deploying in São Paulo and arranging appropriate peering through the IX.br exchange can place inference closer to participating ISPs and content networks. In a March 20, 2026 release, NIC.br reported 50 Tbps of aggregate IX.br traffic, including 32 Tbps at São Paulo. These are exchange traffic peaks, not RTT measurements or per-server capacity guarantees.
Public, cacheable assets such as front-end bundles and video tiles can be delivered through Melbicom’s CDN, which spans 40 PoPs across 35 countries, including Fortaleza and Rio de Janeiro in Brazil. Keep model execution on the origin and sensitive embeddings or personalized responses out of shared caches. Review cache rules and edge locations against the workload’s data-residency requirements; CDN delivery does not run the model.
Where a Brazilian Dedicated Server Helps
Hosting in Brazil can avoid unnecessary international paths when users and data sources are local. Benchmark routes and end-to-end latency for recommendation engines, fintech risk scoring, live-ops analytics, and speech systems; local placement alone does not guarantee stable bandwidth or deterministic RTT.
Bare Metal in Brazil: Privacy and Sovereignty
Keeping selected processing and storage in Brazil on dedicated hardware gives you control over that deployment’s location and tenancy. It does not establish where every backup, log, CDN copy, or external service stores data. LGPD does not impose a blanket requirement to host all personal data in Brazil, and local hosting does not by itself establish compliance. Document lawful processing, security measures, retention and deletion, access controls, and each data flow. Where personal data is transferred abroad, use an applicable mechanism under ANPD’s international-transfer rules, such as a relevant adequacy decision or ANPD standard contractual clauses.
For private-sector legal entities, LGPD fines can reach 2% of the revenue in Brazil of the entity, group, or conglomerate in the preceding fiscal year, excluding taxes, capped at BRL 50 million per infraction. Other sanctions can include suspending affected data processing.
Monitoring and Capacity Planning for Instrumentation and Scaling

A performant node must also be healthy and right-sized. The dashboard is illustrative; its displayed percentages are not scaling thresholds. Monitor the following:
- Instrumenting from day one: High‑frequency metrics for CPU, installed GPUs, memory, NVMe I/O, and NICs should be collected, and you need to ingest application traces and logs into a searchable store. That way, you can identify GPU throttling, data‑loader stalls, and queue build‑ups before they hit SLOs.
- Applying AIOps: Employ anomaly detection on latency, throughput, GPU memory, and temperature to surface subtle degradations such as sustained latency increases or a slow memory leak.
- Forecasting capacity on leading indicators: Track sustained utilization, p95/p99 latency, request queue depths, and feature-store I/O. Set resource-specific thresholds from load tests and leave headroom for bursts and failures. Plan scale-up or scale-out before demand exceeds tested capacity, accounting for hardware lead times. Add GPUs only where the chassis, power, cooling, and software stack support them; otherwise add appropriately sized nodes behind a model router.
- Operational discipline: Schedule kernel/driver updates, monitor SMART/NVMe health, and pre-stage replacements when error rates rise.
Sizing for Training, Inference, and Pipelines
- Training nodes advice: Size CPU cores, RAM, and NVMe scratch for data loading and preprocessing. Budget GPU memory for model weights, gradients, optimizer state, activations, and working buffers at the intended precision and batch size. For São Paulo, plan within the quoted 1–40 Gbps port options; verify checkpoint and multi-node synchronization performance instead of assuming a 100 Gbps training interconnect.
- Latency-critical inference: Benchmark the actual CPU and, where needed, GPU against target concurrency, batch size, and p95/p99 latency. Allow accelerator memory for model weights and runtime state. Adding a second GPU does not automatically reduce tail latency. Keep latency-critical dependencies close to the São Paulo inference node.
- Real-time data pipelines: Handle Kafka/Fluentd ingestion with NVMe and network capacity sized to measured ingress and replication traffic. Co-locate feature stores with inference when the data is sensitive or high-velocity.
- Hybrid edge caching operation: Keep model execution on the São Paulo node while public static assets and non-sensitive, cacheable artifacts are delivered through a CDN such as Melbicom’s, with PoPs in South America.
Scale with Melbicom’s Global Footprint
A locally based AI platform may later expand globally. Melbicom’s footprint comprises 21 global Tier III/IV DCs, including the coming-soon São Paulo location, and a CDN with 40 PoPs across 35 countries. You can replicate approved model artifacts to Europe or Asia while keeping selected training data in Brazil; assess personal data in artifacts and supporting services before cross-border transfers. Globally, we provide up to 200 Gbps per server. This is not the São Paulo port specification. We have large in-stock server pools at active locations and offer 24/7 support.
Bare Metal in Brazil for AI Workloads
| AI/ML challenge | How São Paulo’s bare metal helps |
|---|---|
| High compute demand, such as deep nets and large optimizers | A custom preorder can allocate exclusive CPU, RAM, and optional GPU resources; confirm the accelerator and benchmark the intended model. |
| Massive I/O, such as feature streams and checkpoints | NVMe and planned 1–40 Gbps port options in São Paulo can support local pipelines; size storage and networking against measured workloads. |
| Low latency/user proximity | Appropriate IX.br peering can shorten network paths; validate RTT, jitter, and end-to-end inference latency from target ISPs. |
| Data privacy/LGPD | In-country processing and storage on dedicated hardware support residency controls, but do not replace lawful processing, security, or transfer compliance. |
| Rapid demand growth | Workload-specific monitoring, load testing, and modular scale-up/out help identify bottlenecks; industry-wide training-compute growth is not a demand forecast. |
Deploying Bare Metal in Brazil: Next Steps
Melbicom is preparing its São Paulo server location and accepts preorders for custom hardware configurations. We operate our own network, provide high-bandwidth options globally, and tailor hardware and networking to the agreed deployment. Share your traffic volumes, latency SLOs, data-residency needs, GPU/CPU requirements, and peering preferences so we can confirm the configuration, network options, and launch timing in a reservation-backed plan.
Be the first to host in Brazil on special terms
We at Melbicom will help you plan a custom São Paulo deployment with AMD EPYC/Ryzen or Intel Xeon CPUs, optional GPUs, and 1–40 Gbps port options, subject to quotation and allocation. Our CDN already covers 40 PoPs across 35 countries, including 6 LATAM PoPs across 5 countries. Tell us your volumes, targets, and exact specs so we can shape a tailored early offer and reserve capacity for your launch.
Get expert support with your services
Blog

Faster Apps and LGPD Compliance with Brazil Dedicated Servers
Why Rent Dedicated Servers in Brazil Instead of Serving from Abroad?
Hosting application origins on a Brazil dedicated server can shorten network paths to Brazilian users and avoid unnecessary international round trips. The improvement depends on peering, user location, and congestion, so compare RTT, packet loss, and application response times from your main audience regions rather than assuming uniformly low latency nationwide.
DataReportal’s Digital 2026: Brazil estimates 185 million internet users and 86.9% internet penetration using October 2025 data, making origin placement relevant at national scale.
Two structural factors matter when comparing local and overseas compute:
- Brazil’s internet exchanges are world‑class. In March 2026, IX.br reported a 50 Tbps aggregate traffic peak across its exchanges, including 32 Tbps in São Paulo. More than 2,500 networks connected directly to the São Paulo exchange, creating opportunities to shorten paths to the last mile through local peering.
- Modern subsea routes reduce overseas detours. EllaLink lists round-trip delay below 60 ms for Sines–Fortaleza and below 105 ms for Sines–São Paulo. These are route-specific operator figures, not nationwide internet latency guarantees; they support cross-regional services and BCP but do not replace tests on Brazilian networks.
Host in LATAM— Reserve servers in São Paulo — CDN PoPs across 5 LATAM countries — 21 Tier III & IV DCs, including Brazil |
|
How Do São Paulo Proximity, IX.br Peering, and Multi‑Homed Transit Cut Latency?
Put your origin where Brazil’s networks meet. In São Paulo, IX.br peering can shorten paths to participating ISPs and content networks and reduce detours through distant transit hubs. Multi‑homed upstreams provide alternative paths, but not deterministic latency. BGP selects routes according to routing policy, not automatic latency or packet-loss measurements; failover depends on failure detection and routing convergence. This combination—São Paulo adjacency + IX.br peering + multi‑homed transit—can improve the reachability and resilience of a Brazil dedicated server, but nationwide response times still depend on user location, access networks, congestion, and application behavior.
Which Regulatory “Rules of the Road” Are Easier to Meet with In‑Country Hosting?
Brazil’s LGPD does not impose a blanket requirement to host personal data in Brazil. ANPD resolutions regulate cross‑border transfers of personal data, including standard contractual clauses (SCCs) and adequacy decisions. Keeping data on a Brazil‑based dedicated server can reduce international transfers, but does not by itself establish compliance: lawful processing, security, and data-subject rights still apply. Review backups, logs, CDN caching, and overseas access as part of the same data-flow assessment.
ANPD’s Resolution No. 32 of January 26, 2026 recognizes the EU, Iceland, Liechtenstein, and Norway as adequate destinations within the decision’s scope, so covered transfers do not need SCCs as their transfer mechanism.
Under Resolution No. 15/2024, controllers generally must notify ANPD and affected individuals within three business days of learning that an incident affected personal data when it may cause relevant risk or harm. Eligible small-scale processing agents receive double the period; specific statutory deadlines may also apply.
What Does the Market Signal Say About Repatriating Steady Workloads?
In its April 16, 2024 report, Barclays data showed that 83% of 100 CIO respondents planned to repatriate some public‑cloud workloads to private cloud or on-premises infrastructure over the following 12 months, with storage and databases leading the planned moves. These were intentions recorded in spring 2024, not completed migrations or a current Brazil-specific adoption rate. The same survey found strong public-cloud spending expectations, supporting a pragmatic hybrid approach rather than a single‑stack dogma.
How Does TCO Look When You Shift Origin Compute to a Dedicated Server in Brazil?

Three cost levers dominate: always‑on compute, egress, and control overhead. Dedicated hosts exchange variable instance pricing for fixed monthly economics and large, predictable bandwidth allocations—attractive when origin traffic and job queues run 24/7. You also reclaim hardware‑level tuning (I/O, NUMA, storage layout) and avoid sharing compute hardware with other tenants, which can help stabilize tail latency; shared network paths can still introduce contention. For global platforms with Brazilian user concentrations, lower RTTs and predictable bandwidth charges can improve responsiveness and cost planning. Compare the full TCO, including operations, redundancy, backups, migration, and bandwidth overages, rather than assuming dedicated hosting is always cheaper.
Local vs. remote origin for Brazil (at a glance)
| Hosting Location | Latency Considerations for Brazilian Users | Data Sovereignty & Compliance |
|---|---|---|
| Remote Cloud (US/EU) | International paths add distance; RTT varies by route and user network | Use an applicable LGPD transfer mechanism, such as adequacy or SCCs |
| Local Dedicated Server (BR) | Can shorten domestic paths; measure from the regions and ISPs you serve | Local hosting alone does not establish compliance; assess backups and overseas access |
These are placement considerations, not latency benchmarks. Cross-border requirements depend on the actual data flows and the applicable ANPD transfer mechanisms.
The Pragmatic Migration Path from Hyperscale Cloud to Dedicated Servers
You don’t need a “big bang.” Migrate with deliberate, low‑risk steps that preserve uptime and auditability:
- Stand up a parallel origin in São Paulo. Choose a dedicated server in Brazil sized for your peak request/second and storage IOPS profiles. Establish site‑to‑site VPN or private interconnect to your cloud VPC to sync data and logs.
- Replicate state methodically. Bulk‑load historic datasets over high‑bandwidth links (or offline media if needed); then switch to near‑real‑time streaming for deltas. Measure replication lag and jitter over the chosen paths; multi‑homed transit and IX.br peering do not guarantee either.
- Cut over with your CDN. If you already run CDN edges in Brazil, point them to the new São Paulo origin and ramp traffic with weighted DNS or header‑based routing where the CDN supports it. Cache hits remain at the edge; validate cache misses and uncached dynamic requests before increasing origin-bound traffic.
- Retain a thin cloud footprint. Keep object storage (Melbicom S3 is hosted in Amsterdam), backups, or DR replicas in the cloud while the production origin sits on a Brazil-based dedicated server. Confirm where these copies and any overseas administrative access are located, and assess the applicable transfer mechanism before moving personal data.
The Operating Model: MSAs, Remote Management, and a 24/7 NOC
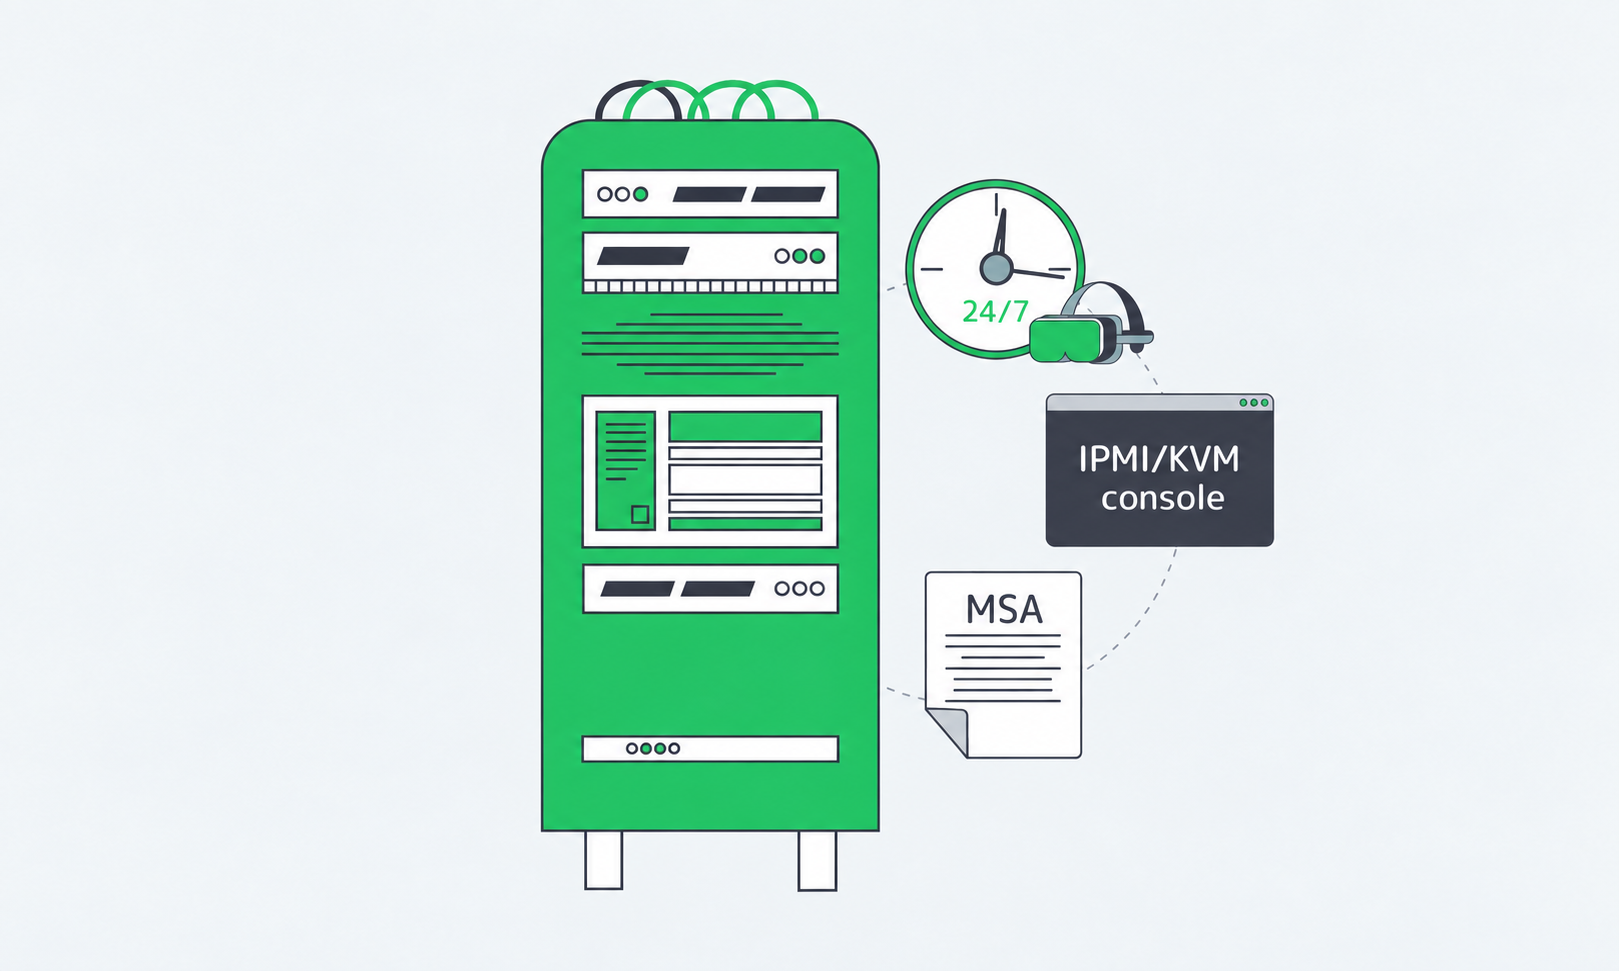
MSAs. With dedicated hosting in Brazil, you contract directly for the outcomes that matter—data location, support scope, hardware replacement windows, access controls, log retention, and peering policy. A well‑drafted MSA clarifies who can access what (and from where) and how incidents are handled under LGPD.
Remote management. Dedicated servers in Brazil shouldn’t mean hands‑on‑keyboards in a cage. Expect IPMI/KVM for full out‑of‑band control so your SREs can reinstall operating systems, manage firmware, or capture consoles without a truck roll.
24/7 NOC. Network‑aware ops is non‑negotiable for low‑latency applications. Look for round‑the‑clock support with hardware replacement windows documented in the MSA and engineers who understand BGP, peering, and routing health—because a fast origin is only as reliable as the path to it.
Brazil Deploy Guide— Avoid costly mistakes — Real RTT & backbone insights — Architecture playbook for LATAM |
|
Latency and Compliance in Brazil
Placing origins on a dedicated server in Brazil—ideally in São Paulo with IX.br peering and multi‑homed transit—can shorten paths to Brazilian users and reduce reliance on international routes. Validate latency, packet loss, and application performance from the networks your users actually use. Keeping personal data within Brazil can reduce cross‑border flows, but LGPD compliance still depends on lawful processing, security, rights handling, and any remaining international transfers. Evaluate steady workloads for dedicated or private infrastructure using measured performance and full TCO, not a blanket assumption that local hosting is always faster, cheaper, or compliant.
Fast, Compliant Server Launches in Brazil
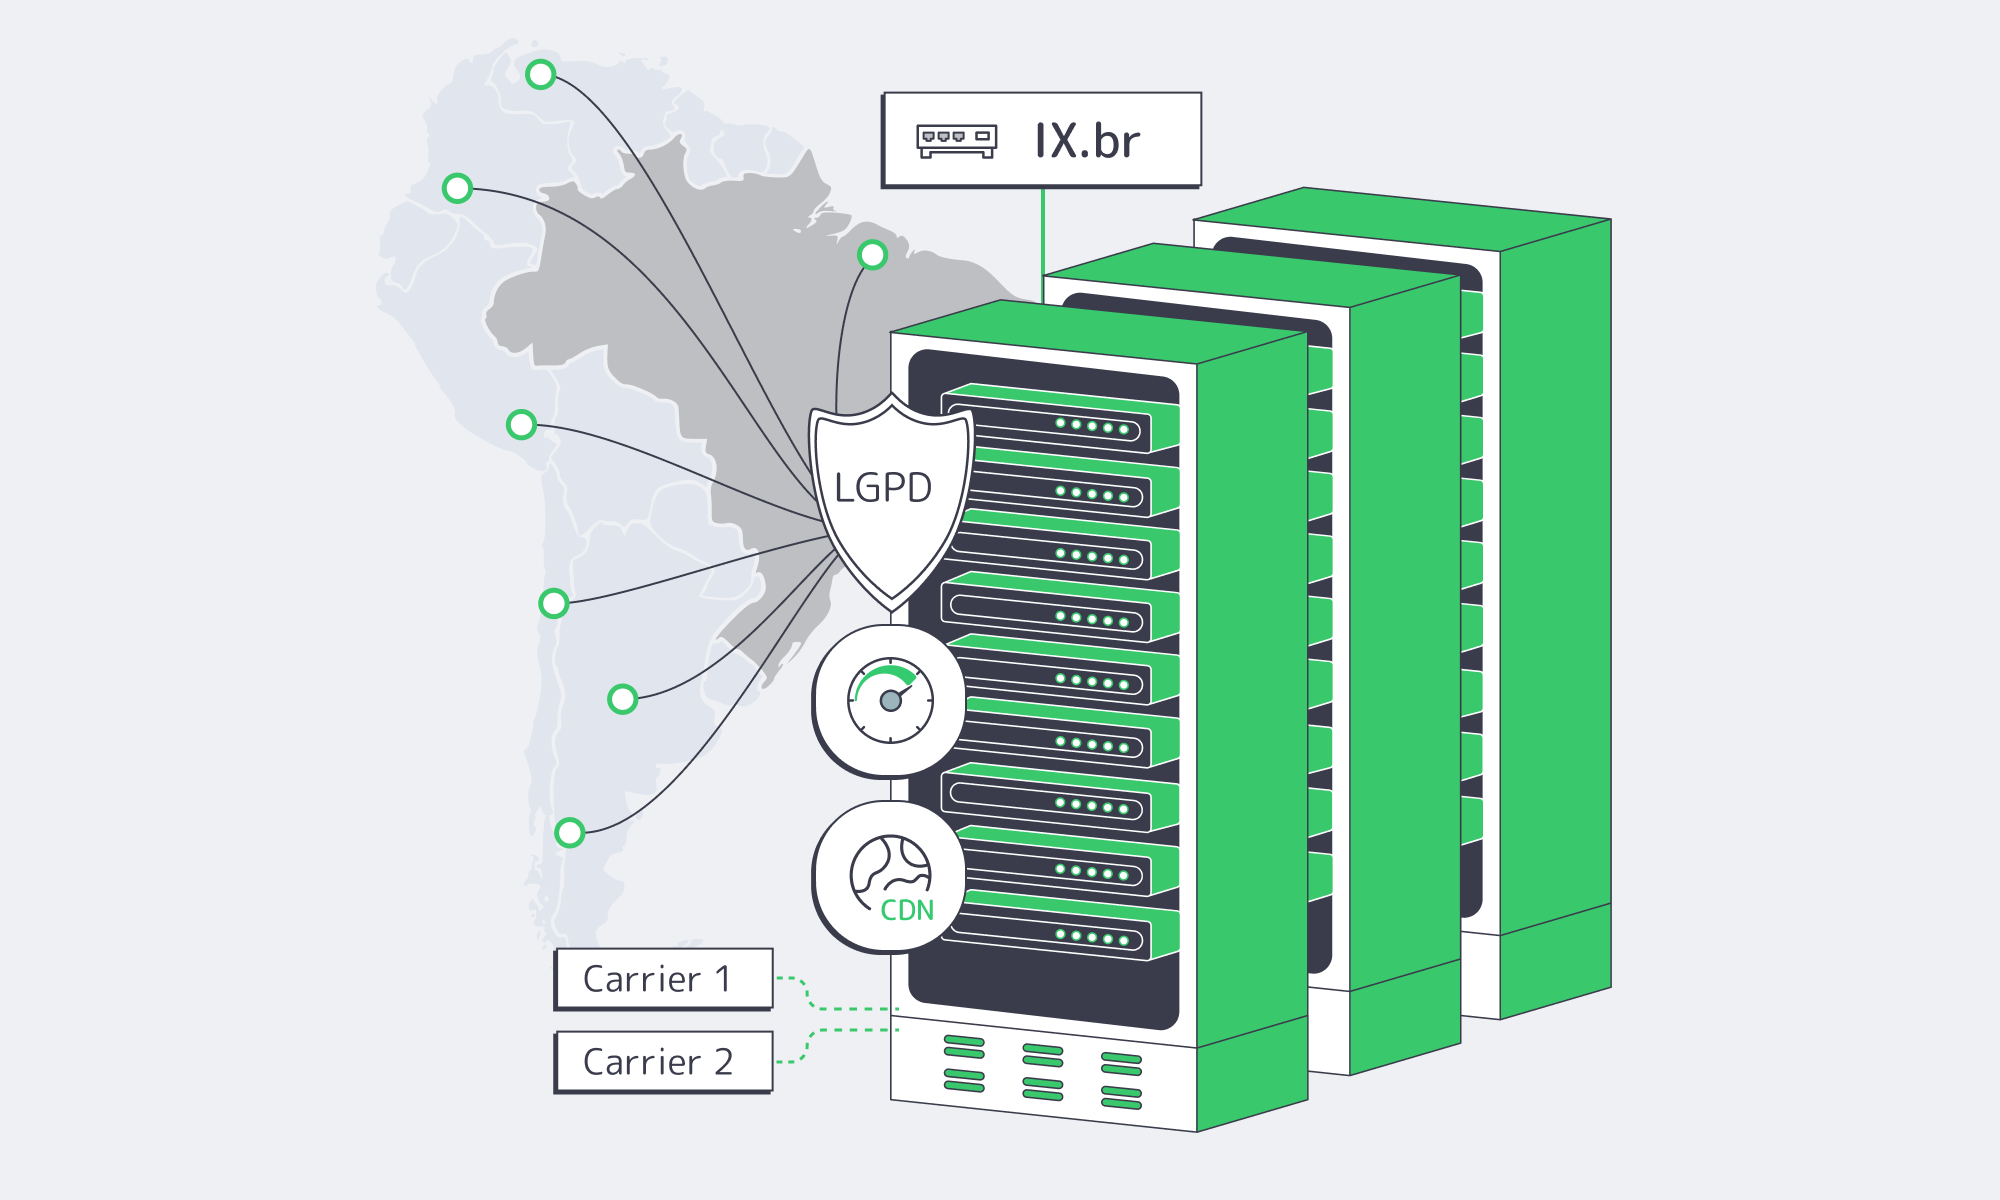
Melbicom is preparing data center presence in São Paulo and is collecting early‑access demand for dedicated servers. Until go‑live, we can plan your Brazil launch around IX.br peering, multi‑homed transit, and your data-handling requirements, while Melbicom CDN nodes in Fortaleza and Rio de Janeiro can serve cacheable content today. CDN caching does not relocate your origin or establish in-country handling for all personal data. Once São Paulo capacity is available and your configuration is confirmed, we can plan a controlled origin migration. Melbicom operates its own global network, offers high‑bandwidth options (up to 200 Gbps per server globally) and custom hardware, and runs a 24/7 NOC with IPMI/KVM and BGP/BYOIP readiness. Share your traffic volumes, compliance needs, and hardware/network specs now; we’ll return a Brazil-ready design and confirm capacity, port speeds, and launch timing in your quote.
Dedicated Hosting in Brazil, Made Flexible
- Deploy fast: We’re collecting detailed requirements now (traffic profiles, IX.br peering needs, carrier preferences, rack‑level constraints) to pre‑stage capacity and shorten activation windows at launch. Our 24/7 NOC will coordinate launch support; installation and activation dates will be confirmed in your quote.
- Customize freely: Specify CPU/RAM/NVMe/GPU mixes, NICs, and storage layouts; request BGP/BYOIP and routing policy; define private L2/L3 overlays. Melbicom’s global baseline includes up to 200 Gbps per server. São Paulo port speeds, carrier options, and hardware availability must be confirmed in your quote.
- Operate globally: Keep a consistent operating model across Melbicom’s 21 Tier III/IV data centers, including the coming-soon São Paulo and Marseille facilities, and a CDN with 40 PoPs across 35 countries. Build once (automation, monitoring, IaC), then roll out in Brazil without re‑tooling. Our own network gives us routing control and the ability to engineer paths—not just rent them.
- Control TCO: Fixed‑price dedicated servers with generous bandwidth allocations reduce egress shock and keep costs legible for steady workloads. Use CDN edges in LATAM today to reduce origin fetches for cacheable content; shift the origin to São Paulo after activation to reduce long‑haul dependencies.
- Engineer for resilience: Pre‑plan IX.br peering, map multi‑homed transit (at least two upstreams), define failure domains, and codify playbooks with the 24/7 NOC. Confirm remote-management access (IPMI/KVM), hardware replacement procedures, and on-site support responsibilities before launch.
- Experience freedom: Simple onboarding, clear MSAs, transparent control surfaces, and access to network engineers—not ticket ping‑pong. We’re structured for no vendor lock‑in and no shared tenancy on your compute.
Be the first to host in Brazil on special terms
Share your traffic and hardware needs to reserve São Paulo capacity. We’ll follow up with launch timelines and options for peering, transit, and compliance.
Get expert support with your services
Blog
BGP Multi-Homing: Reliability, Control, and Speed
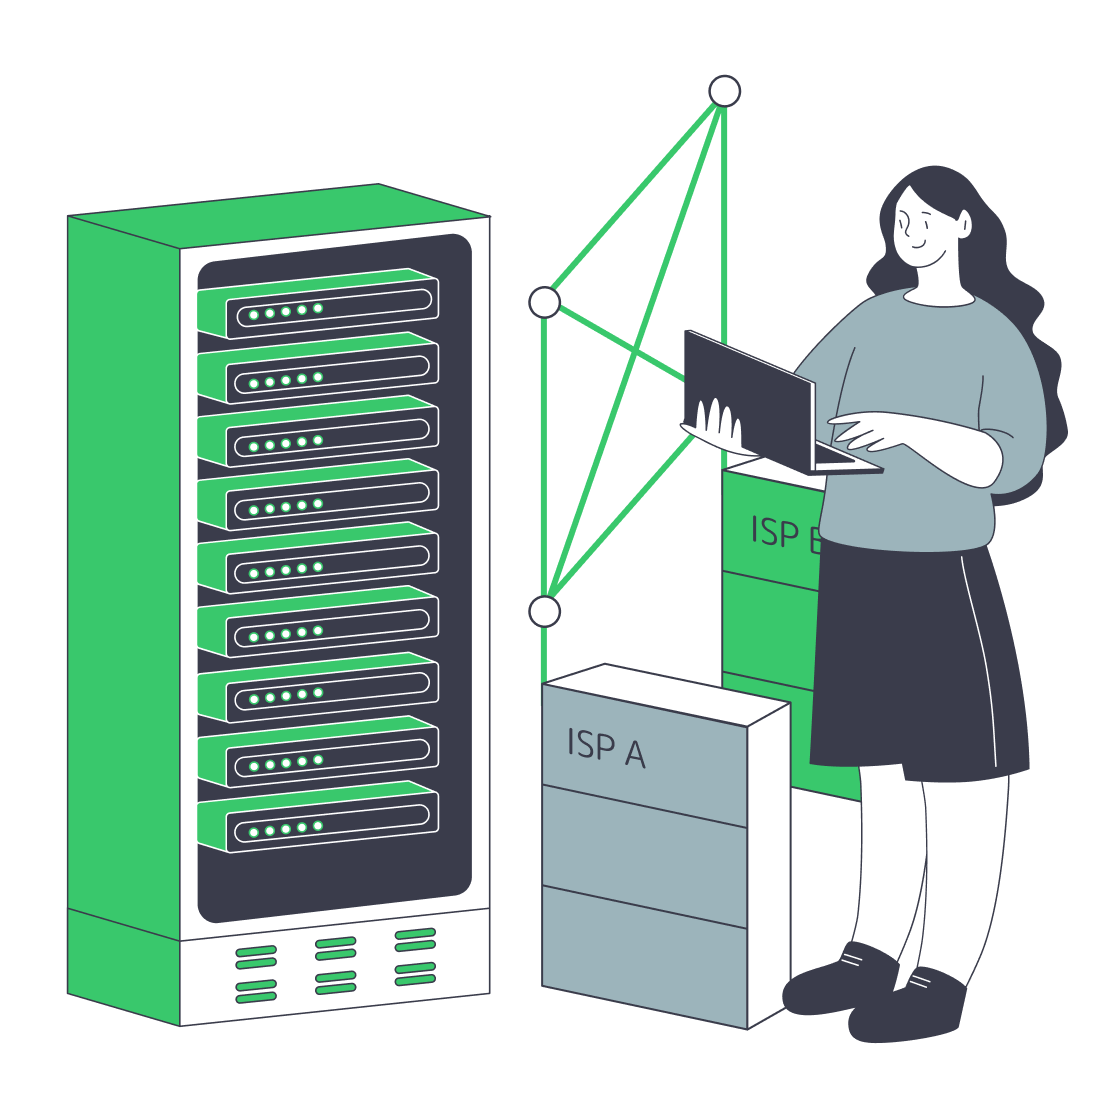
Uptime Institute’s 2026 outage analysis reports that 57% of respondents to its 2025 annual survey put the cost of their most recent major outage above $100,000. This is a per-incident finding, not a universal cost per minute. A single ISP outage can take entire application stacks dark, as seen during the August 30, 2020 CenturyLink/Level(3) incident, when Cloudflare observed a 3.5% drop in its global traffic during an outage lasting several hours. Multi‑homing with BGP reduces single-provider risk: connect to multiple ISPs, let the border gateway protocol select paths according to routing policy, and fail over automatically when a failed route is removed and another usable path remains.
Choose Melbicom— 1000+ ready-to-go servers — 21 global Tier IV & III data centers — BGP sessions with BYOIP |
|
What Is BGP Multi‑Homing and Why Does It Matter for Reliability?
BGP multi‑homing connects a network to two or more upstream ISPs and advertises its IP prefixes through each. When a route is withdrawn or a failed session is detected, BGP can select a surviving path without changing DNS. Reliability still depends on path diversity, available capacity, and convergence time.
In steady state, you can use both links actively for load sharing by destination. Local‑pref controls outbound choices; AS‑path prepends and communities influence inbound paths, while MED normally compares entry points into the same neighboring AS. The result is resilience + control that single‑homed links simply don’t provide.
A core advantage over “backup‑only” designs: multi‑homed BGP needn’t be idle capacity. With the border gateway routing protocol, you can keep links hot—for example, prefer ISP‑A to western Europe while favoring ISP‑B to East Asia, using measured path quality to set destination-based policies. BGP does not measure latency or jitter itself; sending different applications to the same destination over different links requires additional traffic classification and forwarding policy. Policy lives on the router, not in ticket queues.
How Does Border Gateway Protocol Routing Make Multi‑Homing Work in Practice?
At the edge, you run eBGP to each provider, announce your public prefixes, and ingest either full tables or defaults (depending on router scale). For outbound control, you set local preference to favor one ISP or split by destination. For inbound control, you influence the outside world’s choice of path using AS‑path prepending, selective advertisement of more‑specifics (where registries and filters allow), and BGP communities that request provider‑side action (e.g., de‑prefer with certain carriers). Remote networks’ policies can override these inbound preferences. This is why multi‑homing with BGP is as much policy engineering as plumbing.
Can BFD make failover essentially instant?
Not necessarily. Bidirectional Forwarding Detection (BFD) can detect a failed monitored path in less than a second when both peers support suitable timers. Detection is only the first step: BGP route selection, forwarding-table updates, remote convergence, and application recovery can take longer. BFD does not guarantee uninterrupted sessions or detect every remote outage.
Cisco’s IOS XE 17.x references document BGP’s use of BFD notifications to accelerate convergence. Coordinate BFD support and timers with each provider and test under load; overly aggressive settings can trigger false failures.
How Does Multi-Homing Improve Uptime?
A dual-provider BGP design can reduce exposure to an ISP outage, but it has no universal uptime figure. Actual availability depends on independent paths, resilient edge equipment, spare capacity, and tested recovery. The table is a mathematical illustration of provider availability, not a measured deployment result or service guarantee.
Assume each ISP is available 99.9% of the time and their failures are statistically independent. The probability that both are unavailable is 0.001 × 0.001 = 0.000001, giving 99.9999% availability for at least one provider. Annual equivalents below use 365 days and exclude shared failures and failover time.
| Network Setup | Modeled Provider Availability | Equivalent Downtime/Year |
|---|---|---|
| Single ISP (assumed availability) | 99.9% | ~8.76 hours |
| Dual ISP BGP (independent failures) | 99.9999% | ~31.5 seconds |
Two caveats prevent treating this model as application uptime:
- Independence matters. Avoid shared last‑mile ducts, common meet‑me rooms, or the same carrier resold by two brands. Shared routers and power paths can still fail together.
- Failover speed matters. BFD can accelerate detection, but route propagation and application recovery still matter. The surviving link must carry the required traffic.
What Do You Actually Need to Deploy?
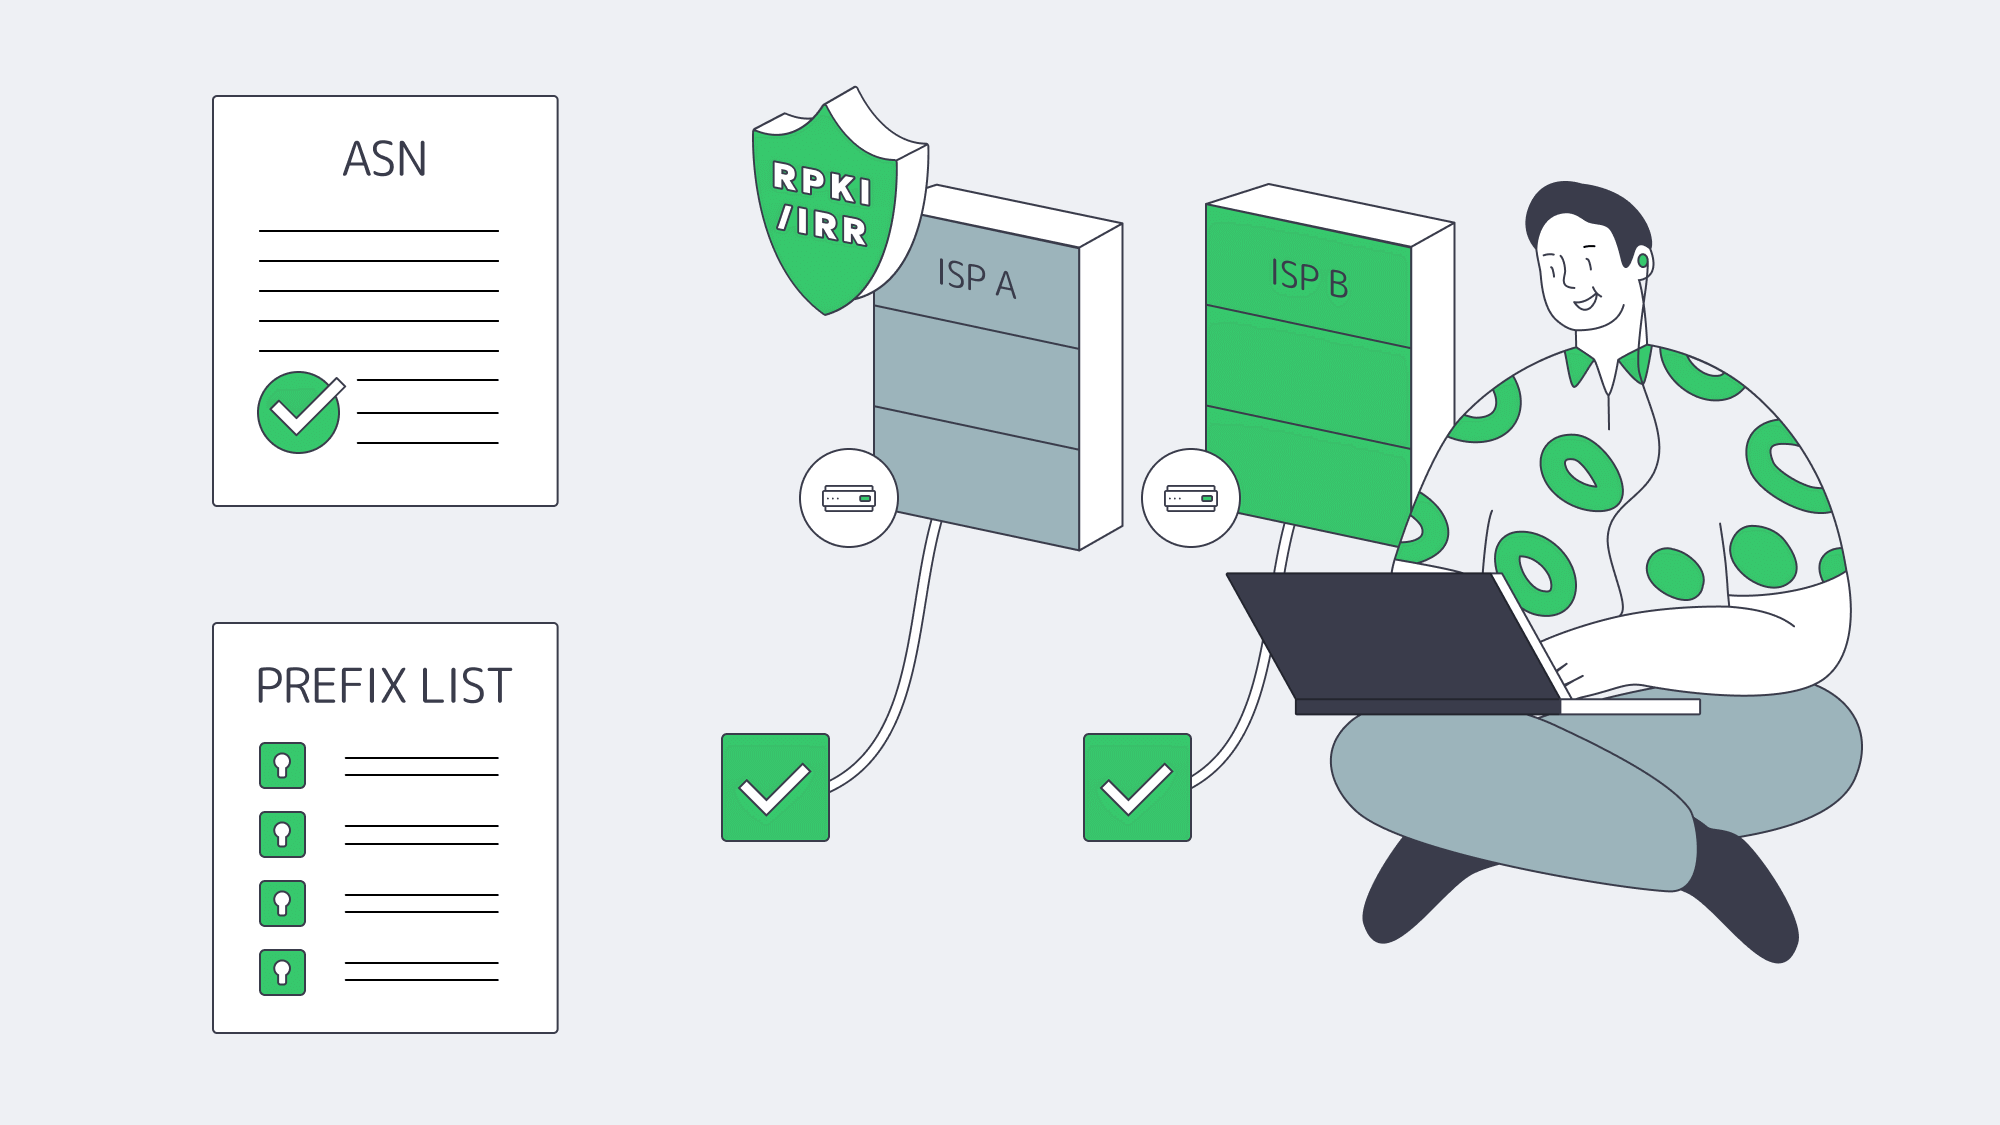
A basic border gateway protocol configuration for multi‑homing has a few prerequisites:
- Resources: Your ASN and routable prefixes accepted by both providers; examples include an IPv4 /24 or an IPv6 /48.
- Edge device: A router that can run eBGP (hardware or a hardened VM running BIRD/FRR) sized to the route load you’ll ingest. Add edge-device and power redundancy when a single router would otherwise remain a shared failure point.
- Two (or more) carriers: Contracts and cross‑connects to diverse ISPs, plus IRR/RPKI hygiene so they’ll accept and propagate your prefixes.
- Policy & safety rails: Local‑pref for outbound, a simple inbound plan (prepending/communities), strict prefix‑limits and import/export filters, and BFD where both peers support it.
Where Melbicom’s Multi‑Carrier Network Adds Practical Value
Melbicom operates a multi‑homed backbone with transit from multiple carriers and broad IXP reach across the US and EU. That upstream diversity provides alternative routes when a carrier fails. Our network combines 14+ Tbps aggregate capacity, 23 transit providers, and 29 IXPs, plus 40 CDN PoPs across 35 countries to cache static assets closer to users.
From a deployment standpoint, we at Melbicom make BGP multi‑homing straightforward:
- BGP sessions anywhere: Free BGP on dedicated servers and available for a nominal add‑on on VPS, with BYOIP, IPv4/IPv6, and full/default/partial route options.
- Inbound control that scales: Predefined BGP communities and passthrough communities toward upstream providers support routing-policy control. Request the current community list before designing specific announcements.
- Route integrity by default: RPKI‑validated routing rejects origin-invalid announcements, while strict IRR filtering requires valid route-registry entries.
- Capacity when you need it: Per‑server bandwidth up to 200 Gbps—useful when a failover concentrates traffic on the surviving path.
- Faster time to value: With 1000+ dedicated servers in stock and 24×7 support, Melbicom’s team can raise your session, validate IRR/RPKI entries, and help with policy tuning so BGP does what you intend—before you hit production.
If you prefer starting smaller, VPS with BGP delivers the same peering semantics—use a virtual router (BIRD/FRR), ingest defaults or partial routes, and announce your prefixes via a paid VPS BGP session; upgrade to dedicated later as traffic grows.
A session to Melbicom uses our multi‑carrier backbone; it does not by itself provide two independent customer uplinks.
Multi-Homed vs. Single-Homed Connectivity

Single‑homed Internet links are both simpler and brittle: one circuit, one provider, one control plane. Mean‑time‑to‑repair is outside your control, and even “five‑nines” promises don’t help if a control‑plane blunder propagates bad routes or a fiber cut isolates your facility far from your data center.
By contrast, multi‑homed border gateway protocol routing gives you two levers:
- Availability: If ISP‑A fails and a usable alternative remains, automatic failover can restore traffic through ISP‑B. Existing flows may suffer packet loss or interruption.
- Performance economics: Prefer lower‑latency or lower‑cost paths by policy; shape inbound traffic using communities and prepends.
Quick Answers to Common Questions
- Is BGP difficult? The concepts are simple; the risk is in sloppy filtering. That’s why RPKI + IRR and strict prefix‑limits matter.
- Do I need full tables? Not necessarily. Many edge routers run default‑only or partial routes from each ISP and achieve excellent results with far lower memory/CPU.
- Will I need vendor‑specific wizardry? No. While syntax differs, border gateway protocol configuration principles are consistent across stacks.
- What about brownouts (congestion/packet loss) rather than hard failures? BGP reacts to reachability. You can layer telemetry‑driven policies (or scheduled community changes) to steer around soft faults.
Key Takeaways Before You Architect
- Multi‑homing reduces single-provider risk. Two diverse ISPs improve path resilience but do not remove shared router, power, or access-path failures.
- BFD accelerates failure detection. Sub‑second detection is possible, but end-to-end recovery also depends on routing convergence and application behavior. Coordinate timers and test under load.
- Use policy, not hope, to shape flows. Local‑pref for outbound, communities/prepends for inbound; keep it simple and measurable.
- Design for diversity. Separate carriers, paths, and POPs. The 2020 incident shows why relying on a single upstream is risky.
- Leverage providers that “speak BGP.” Melbicom offers free BGP on dedicated servers + BYOIP, RPKI/IRR, and communities passthrough for simpler deployment.
Improve Uptime with BGP Multi-Homing
The Internet is resilient in aggregate but fragile in parts. A fiber cut or routing misconfiguration far from your data center can still remove your sole path to users. BGP multi‑homing replaces hope with engineering: multiple providers, policy‑driven border gateway protocol routing, and BFD‑assisted detection that can shorten recovery from monitored failures. Compare the cost of a second ISP with the outage losses your own services could incur.
If you’re modernizing connectivity for globally distributed apps in the US and EU, start with architecture, not vendors: diverse carriers, simple policies, tight filters, and failure-detection timers tested with your devices and providers. Then choose a platform that makes those choices easy to implement—and easy to run at scale.
Run BGP multi‑homing with Melbicom
Get carrier‑grade reliability with multi‑homing. Free BGP on dedicated servers, BYOIP support, RPKI/IRR filtering, and communities passthrough. Our team helps you configure sessions and tune policies fast.
Get expert support with your services
Blog
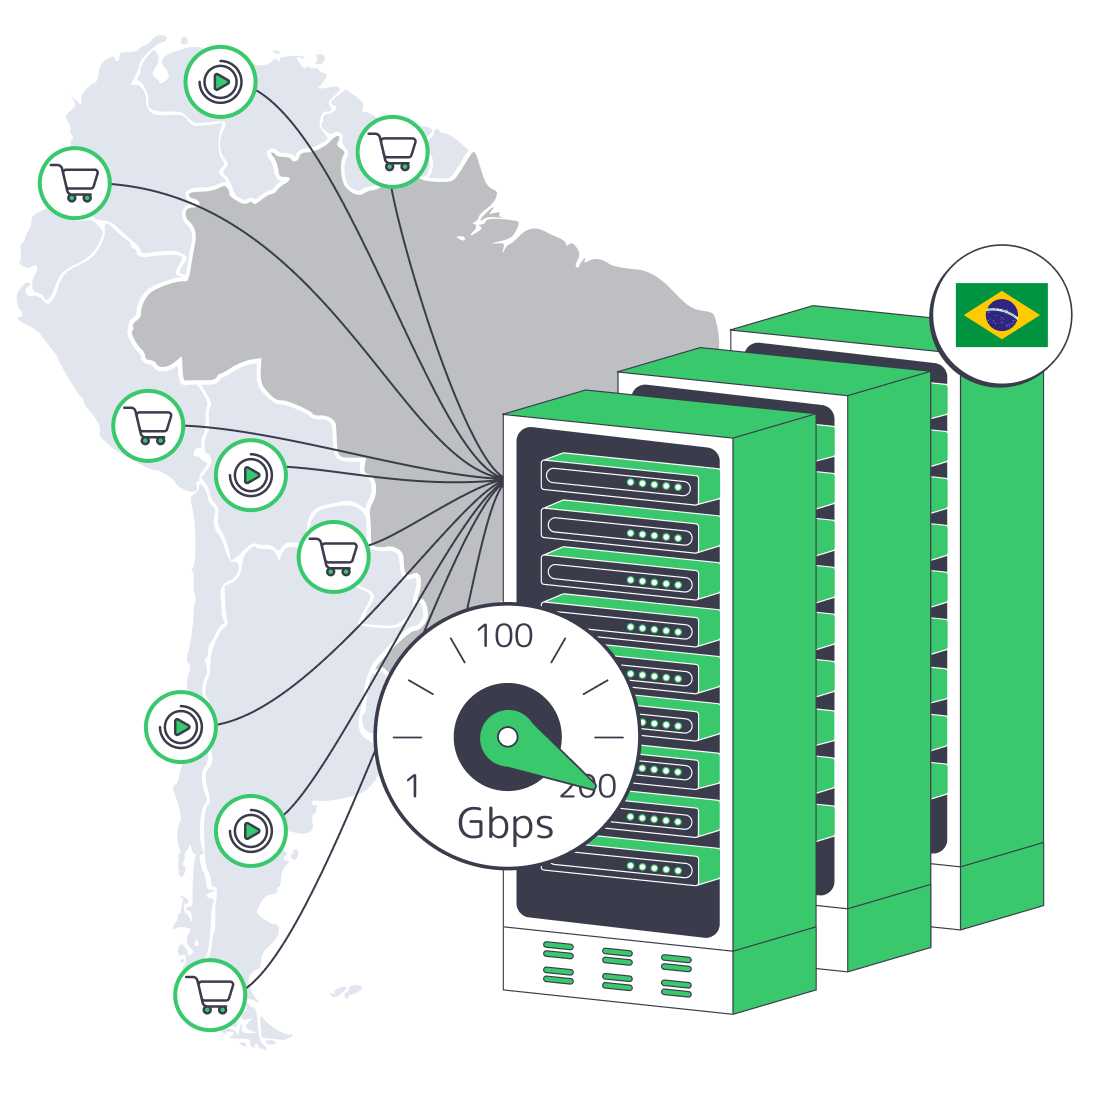
Brazil Server Ports and CDN for Peaks
Brazil’s online economy is substantial: FecomercioSP’s July 2026 Radiografia do Comércio Eletrônico reported R$295.6 billion in Brazilian e-commerce sales for 2025. The high-traffic stores and video platforms are bandwidth‑heavy and subject to spikes, especially in the cases of flash‑sale checkouts and live premiere streams. When your site traffic multiplies in minutes, the infrastructure needs to be able to cope. An infrastructure blueprint for those demands combines dedicated servers at local Brazilian origins, unmetered ports where available, pre-provisioned nodes for scale-out, and edge caching via a CDN with PoPs in South America. If well executed, that design can support faster checkouts and video starts, helping reduce abandonment during traffic spikes.
Host in LATAM— Reserve servers in Brazil — CDN PoPs across 5 LATAM countries — 21 Tier III & IV DCs, including Brazil |
|
Low Latency Dedicated Server Hosting in Brazil for Better Conversion Rates
Physical infrastructure distance adds delay. In conventional glass fiber, light travels at roughly 200,000 km/s—about 5 µs per kilometer one way. Round-trip propagation is approximately twice the one-way delay before routing and equipment overhead. Hosting your origins within Brazil can reduce round-trip times compared with serving São Paulo from North America or Europe; measure the actual improvement across your users’ ISPs and routes. Ray-Ban’s case study published in 2025 reported lower exit rates for prerendered product pages, while a large-scale on-demand video study published in 2012 found that viewer abandonment rises with longer startup delays. These findings support measuring page and playback speed, not a fixed revenue gain from Brazil hosting.
What Bandwidth Do Brazil Ports Offer?
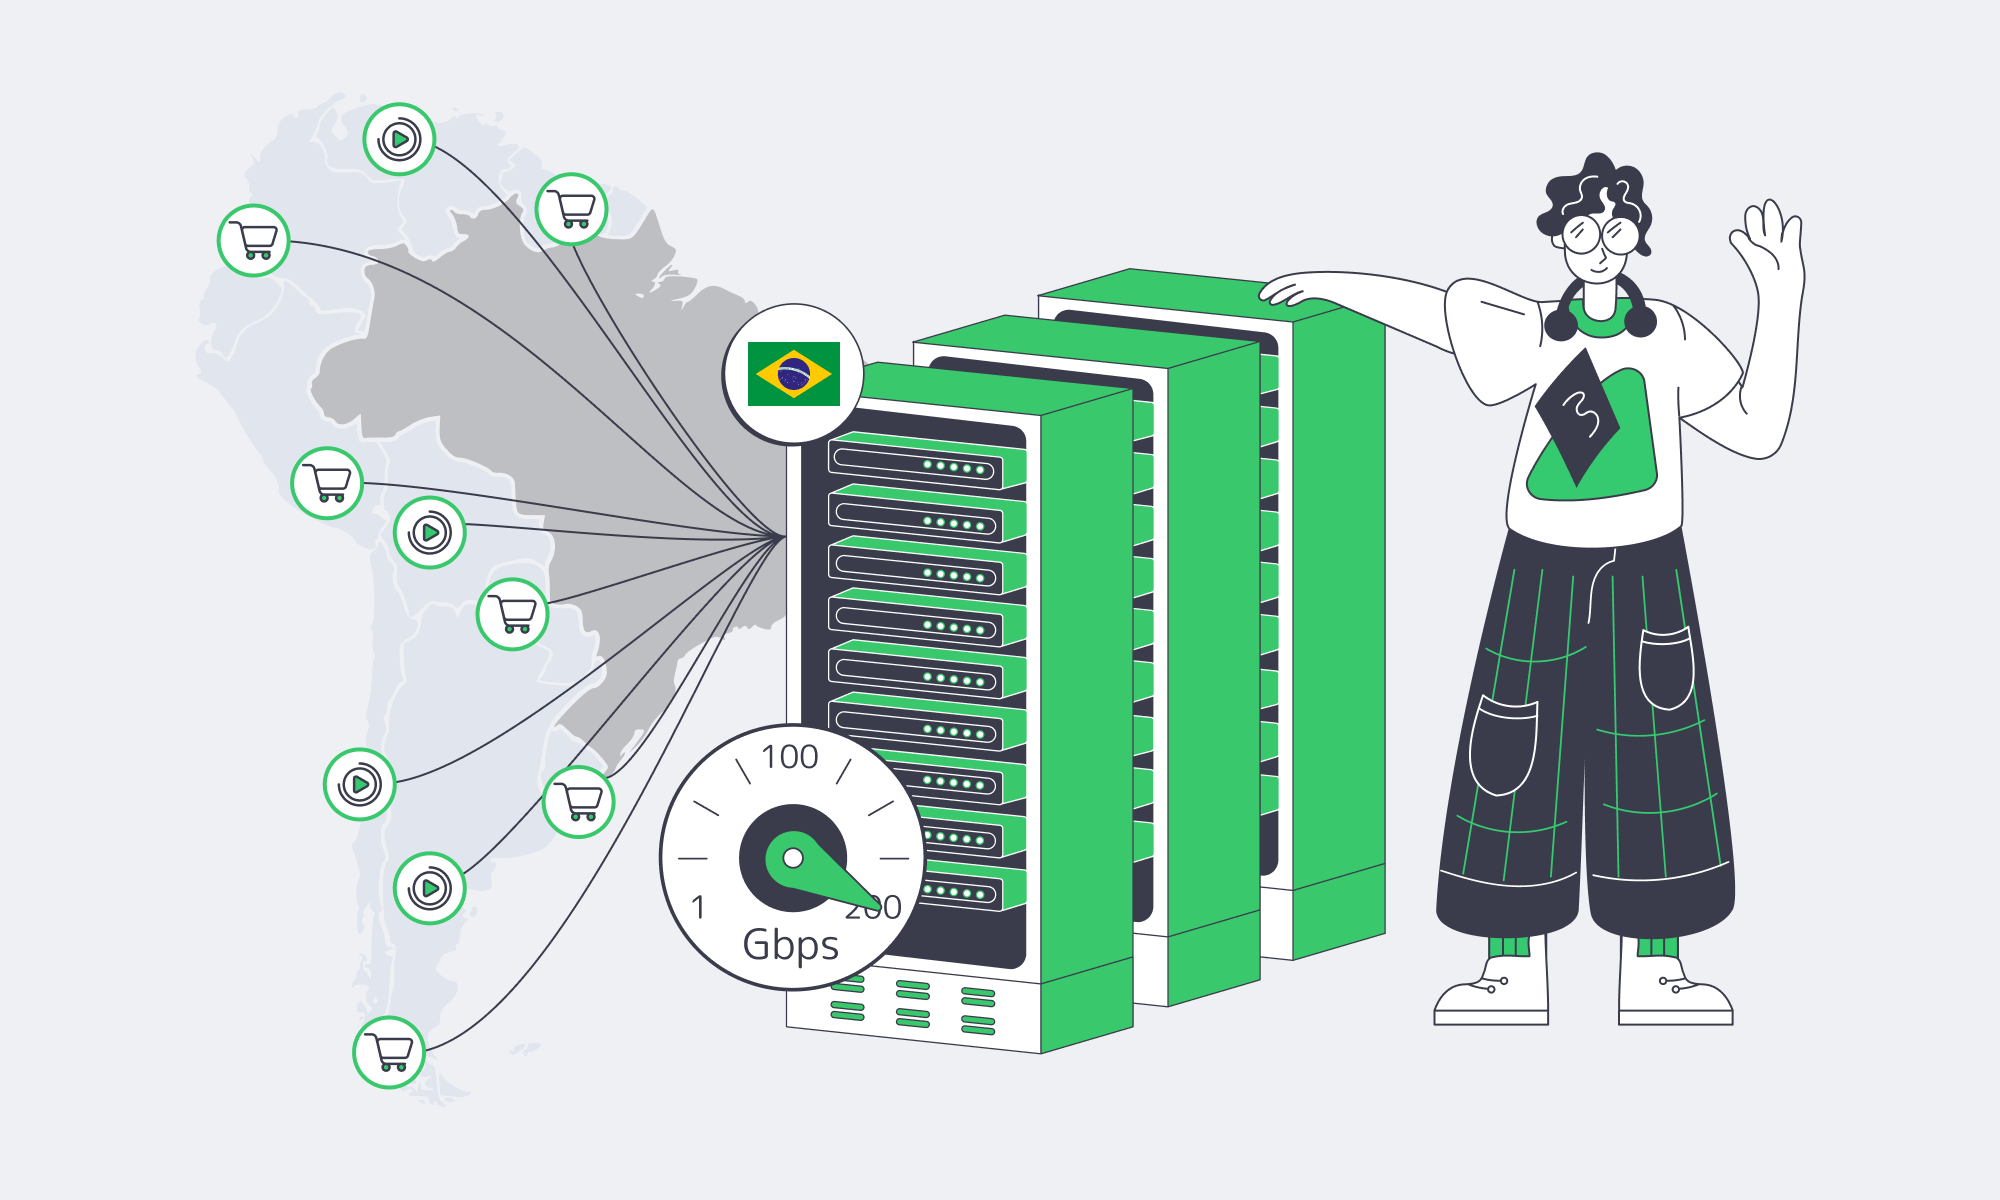
Unmetered bandwidth removes a monthly transfer quota, not the port-speed limit. A 1 Gbps port can theoretically transfer 324 TB in 30 days at continuous full utilization. Across Melbicom’s global dedicated-server range, illustrative ports span 1–200 Gbps; actual Brazil port availability, traffic billing, and sustained-use terms are confirmed in the quote.
The table below and the 1–200 Gbps labels in the article’s illustrations show Melbicom’s global dedicated-server bandwidth range for planning context; actual Brazil port availability is confirmed in the quote.
| Port speed | Theoretical transfer/30 days* | Theoretical concurrent 1080p streams* |
|---|---|---|
| 1 Gbps | ~324 TB | ~200 |
| 10 Gbps | ~3.24 PB | ~2,000 |
| 100 Gbps | ~32.4 PB | ~20,000 |
| 200 Gbps | ~64.8 PB | ~40,000 |
*Calculated using a 30-day month, 24×7 full utilization, decimal TB/PB, and an illustrative 5 Mbps per 1080p stream. These are line-rate ceilings before protocol overhead, other traffic, and operating headroom—not measured application throughput or guaranteed stream counts. Actual encoded bitrates vary.
An unmetered plan can make origin bandwidth costs more predictable, but the port can still saturate. Size capacity for measured peaks, leave operating headroom, and test the application and storage layers as well as the network. Confirm flat-rate bandwidth terms in the quote; CDN delivery and other separately billed services remain outside the origin’s unmetered allowance.
Planning Brazil Hosting for Revenue

When comparing cheap dedicated server offers in Brazil, you should look beyond the price alone and consider the total cost of performance:
- Place origins in‑region to minimize round‑trips for dynamic calls (cart, auth, APIs) and initial stream manifests.
- Provision ports sized to peak—size ports from measured peaks, confirm available Brazil port options and traffic-billing terms in the quote, and plan additional nodes when a single port is insufficient.
- Offload everything cacheable to a local CDN to free up the origin to focus on compute and cache misses.
- Autoscale horizontally with pre-provisioned spare capacity that can be added to the application pool as traffic climbs.
When Do Brazil Workloads Need Faster Ports?
Size bandwidth from concurrent sessions, actual bitrates, cache misses, and background transfers rather than a global traffic-share forecast:
- For OTT premieres and live events: Estimate concurrent FHD/UHD sessions from measured bitrates and CDN offload, leaving headroom below the port ceiling. Use AV1/HEVC where supported by target playback devices.
- High‑SKU storefronts with rich media: Consider higher-capacity ports when measured origin traffic from product images and video justifies that capacity during campaigns.
- Moving large data: Higher-capacity links can shorten nightly replication, object store rebalancing, and preload jobs when storage and the end-to-end path are not bottlenecks. For Melbicom S3 Storage, plan for a remote endpoint in Amsterdam.
Brazil Deploy Guide— Avoid costly mistakes — Real RTT & backbone insights — Architecture playbook for LATAM |
|
Proving Revenue Impact
Financially speaking, two performance levers carry boardroom weight:
- Conversion and page speed: Ray-Ban observed roughly twice the mobile conversion rate for prerendered product pages versus standard page loads among users with browsers supporting the Speculation Rules API, in a case study published in 2025. This was a comparison between user groups, not a universal sales-per-millisecond rule or a Brazil-hosting benchmark.
- A slow start loses the viewer: Historical results from a large-scale on-demand video study published in 2012 show greater abandonment with longer startup delays. Measure startup time and abandonment for your audience without assuming a universal cutoff.
Tie local-origin plans to measured RTT, startup time, conversion, and engagement changes; validate the business impact rather than assuming a fixed uplift.
Autoscaling without Cloud Lock‑In
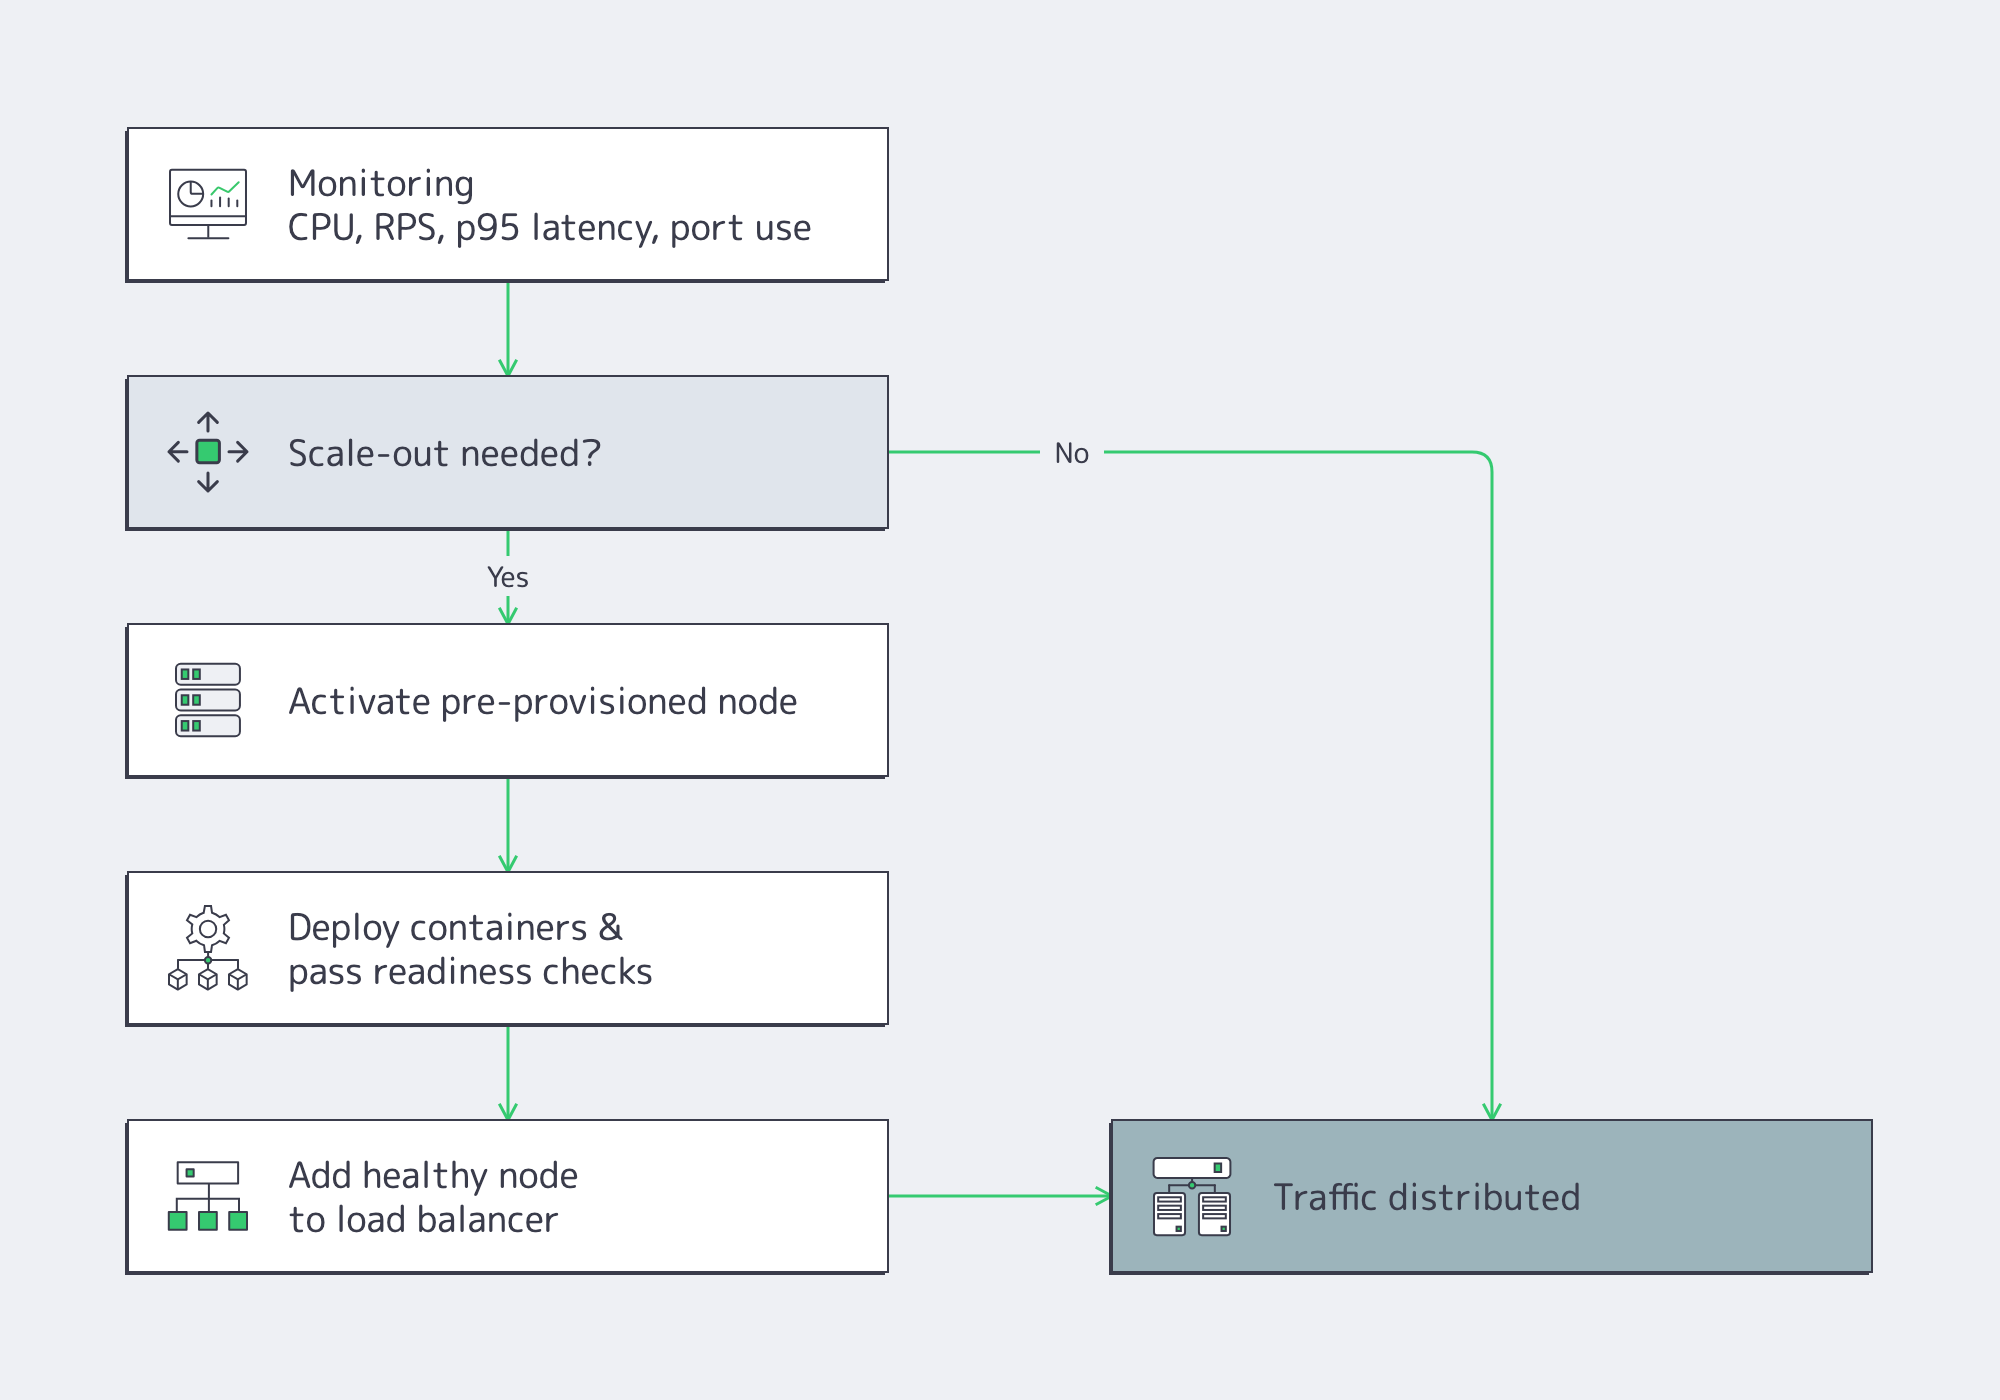
Autoscaling on dedicated servers requires both the right architecture and capacity that is already available:
- To scale horizontally: Keep app tiers stateless behind a load balancer and prepare spare nodes before predictable peaks. Automation can configure containers and add healthy nodes to the pool, but it does not remove hardware procurement, provisioning, or application warm-up time. A Brazil preorder is not ready spare capacity.
- For traffic distribution: Use a health-aware load balancer to distribute traffic among application nodes. Anycast or geo-DNS can steer regional traffic, but neither inherently selects the least-loaded server or guarantees the geographically nearest destination.
- Scaling stateful layers: Leverage read replicas, partitioning, or distributed SQL for databases and segment writes where necessary.
- Automation & SLO‑based triggers: Monitor CPU, RPS, p95 latency, and port utilization. Set workload-specific thresholds from load tests, prepare capacity ahead of known peaks, and let telemetry trigger the addition of ready nodes.
CDN in Brazil: Why Edge Caches Matter
While a local origin can shorten dynamic-request paths, edge caching also plays a crucial role. Melbicom has an extensive CDN spanning 40 PoPs across 35 countries, with South American edges in Fortaleza, Rio de Janeiro, Buenos Aires, Bogotá, and Lima. That allows you to serve cacheable assets such as product images, JS/CSS, thumbnails, and HLS/DASH segments from a nearby edge, letting your origin handle dynamic requests and cache misses. Effective caching can improve page and playback starts and reduce origin egress/CPU—especially during flash crowds.
Moving playlists and segments to the CDN helps with video workloads, but live playlists need short cache lifetimes matched to their update cadence rather than the long lifetimes suitable for immutable assets. Bypass shared caching for carts, checkout, and private authenticated responses. Use Brotli for compressible text assets alongside HTTP/2 and TLS 1.3, keeping your origin focused on transactional logic.
Rollout Checklist for Hosting in Brazil
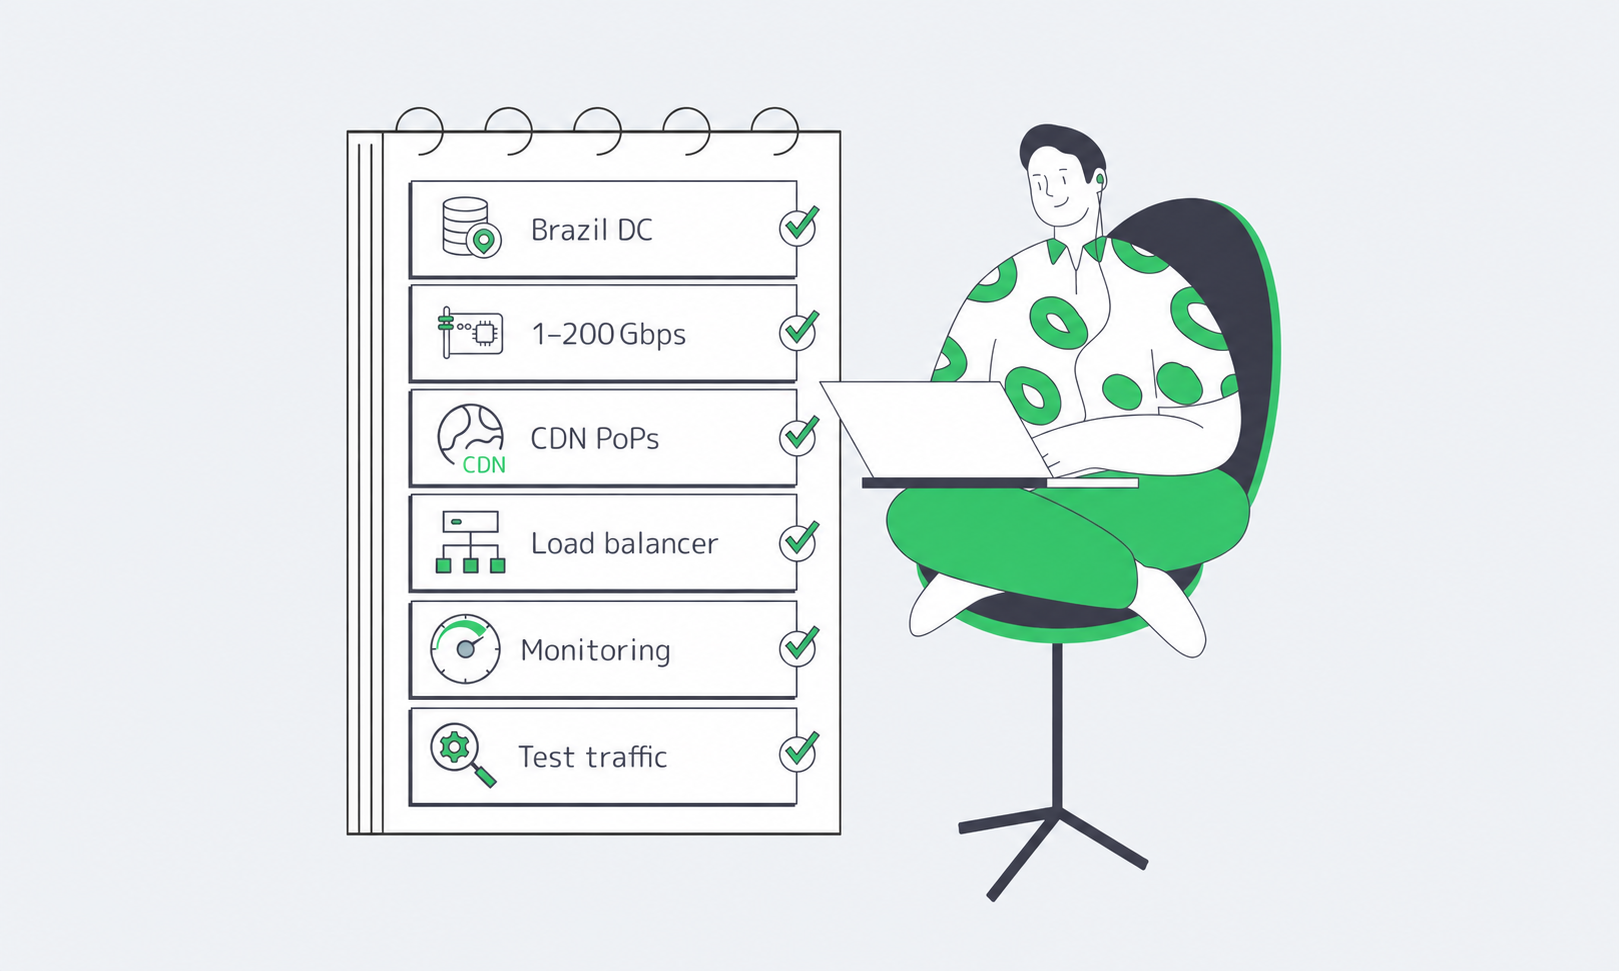
- Baseline measurement: Record current RTT from Brazilian metros to your existing origins and compute peak Mbps/Gbps needs for checkout and playback. Treat 1080p ~5 Mbps / 4K ~15 Mbps as illustrative sizing assumptions, then use actual encoding ladders, concurrency, and headroom for capacity planning.
- Choose the Brazil location: Confirm the São Paulo allocation and deployment date, with port availability, traffic billing, and any unmetered terms agreed in the quote.
- Deploy origins and harden: Tune latency, secure transport, and add observability.
- Wire up CDN PoPs in Brazil and across South America: Cache your static assets, thumbnails, and HLS/DASH segments. Confirm cache‑hit ratios before launching.
- Engineer to autoscale: Keep stateless app tiers behind load balancers and use a scripted add-node flow to activate pre-provisioned spare capacity, passing readiness checks before serving traffic.
- Optimize: Compress, minify, lazy‑load, and use adaptive bitrate ladders.
- Load‑test: Validate NIC utilization, CPU headroom, and CDN offload with Brazil-sourced traffic at peak, and pre-approve the required higher port tier or additional nodes if tests approach saturation.
- Instrument business KPIs: keep track of LCP/TTFB/startup time vs. conversion/engagement in Brazil and publish weekly infra‑to‑revenue dashboards.
Locality, Bandwidth, and Freedom
Brazil is best served by a plan that marries locality (origins in-country), capacity (ports sized to measured peaks, with unmetered terms agreed where available), and distribution (Brazil-centric CDN caches) with pragmatic autoscaling using pre-provisioned nodes. That combination can shorten round-trips and reduce saturation risk, supporting faster checkouts and video starts. While we finalize local dedicated-server capacity, stage the architecture in an active Melbicom location and front it with our South American CDN PoPs. Our footprint of 21 data centers includes the coming-soon São Paulo and Marseille locations. Globally, dedicated-server ports reach up to 200 Gbps. Actual Brazil port availability, traffic billing, hardware, and deployment timing are confirmed in the quote. Prepare and test the migration rather than assuming an instant switch to local origins.
Melbicom is built around Infrastructure Freedom. In practice, that means deployment freedom (choose your software stack and deployment design), configuration freedom (tune hardware and network to your spec), operational freedom (own the stack end‑to‑end), and experience freedom (straightforward onboarding and clear controls). Share your targets; we’ll shape a build around your requirements and plan the move to local Brazil capacity once your allocation and deployment date are confirmed.
Be the first to host in Brazil on special terms
Tell us your peak traffic volumes, target port speeds, bitrate, cache rules, regions, and exact hardware/network specs—and we’ll return a tailored rollout plan with early‑placement options and South America CDN acceleration from day one.
Get expert support with your services
Blog

Hybrid Hosting: Cost, Control, Performance in Atlanta
The cloud is easy to start with, but costs can rise quickly and performance can fluctuate. The modern question isn’t “cloud or not,” but “what runs best where.” Dedicated server hosting in high‑connectivity hubs such as Atlanta can offer predictable capacity for steady workloads when the hardware and network match the application.
Below, we focus on cost, control, and performance—and show when a hybrid strategy anchored in Atlanta dedicated server hosting can balance these priorities.
Choose Melbicom— 28 Atlanta server configurations — Tier III Atlanta data center — 40 CDN PoPs across 6 continents |
 |
Why Re‑Evaluate All‑Cloud Strategies?
Spend uncertainty and performance variability are reasons to reassess an all-cloud strategy. Flexera’s vendor-produced 2026 report, based on 753 cloud decision-makers and users worldwide, reports estimated waste of 29% of IaaS and PaaS spending. This is a self-reported estimate, not audited or guaranteed migration savings.
Dropbox’s 2018 S-1 attributed infrastructure-cost reductions of $39.5 million in 2016 versus 2015 and $35.1 million in 2017 versus 2016 to its optimization program, including moving storage to custom-built colocated infrastructure. These are year-over-year expense reductions, not a rented-server savings benchmark. In October 2024, 37signals projected more than $10 million in savings over five years from its cloud exit; that was a forecast for its own hardware and operating setup, not an achieved five-year total.
The practical alternative is to place elastic or experimental workloads in the cloud and evaluate dedicated servers for steady, bandwidth-intensive workloads. IDC’s Q3 2024 findings distinguish hybrid deployments from the use of multiple cloud providers; neither measure determines the best architecture for a workload.
Why Host Dedicated Servers in Atlanta?
Density and reach. Atlanta has a substantial data-center ecosystem, although directory listings include planned facilities as well as operating sites. Digital Realty’s 56 Marietta Street facility is part of the metro’s interconnection ecosystem. Carrier choice can support diverse routes, but latency to the East Coast, Midwest, or Latin America must be measured on the actual network path.
Economics. Georgia’s average commercial electricity price was 11.91 U.S. cents per kWh in June 2026, according to EIA. This statewide average is not an individual data center’s power tariff or a server-price quote. AWS also announced an investment of at least $11 billion in Georgia in January 2025 to expand cloud and AI infrastructure. That planned investment does not guarantee capacity or resilience for other providers’ customers.
Melbicom in Atlanta. Melbicom operates a Tier III Atlanta facility with up to 200 Gbps per‑server connectivity and a 14+ Tbps global backbone. Provisioning is fast—ready‑to‑go servers can be online within hours—and component replacement is completed within 4 hours, with free 24/7 technical support. Additional options include BGP sessions and private networks for advanced routing.
Costs Compared in Practice
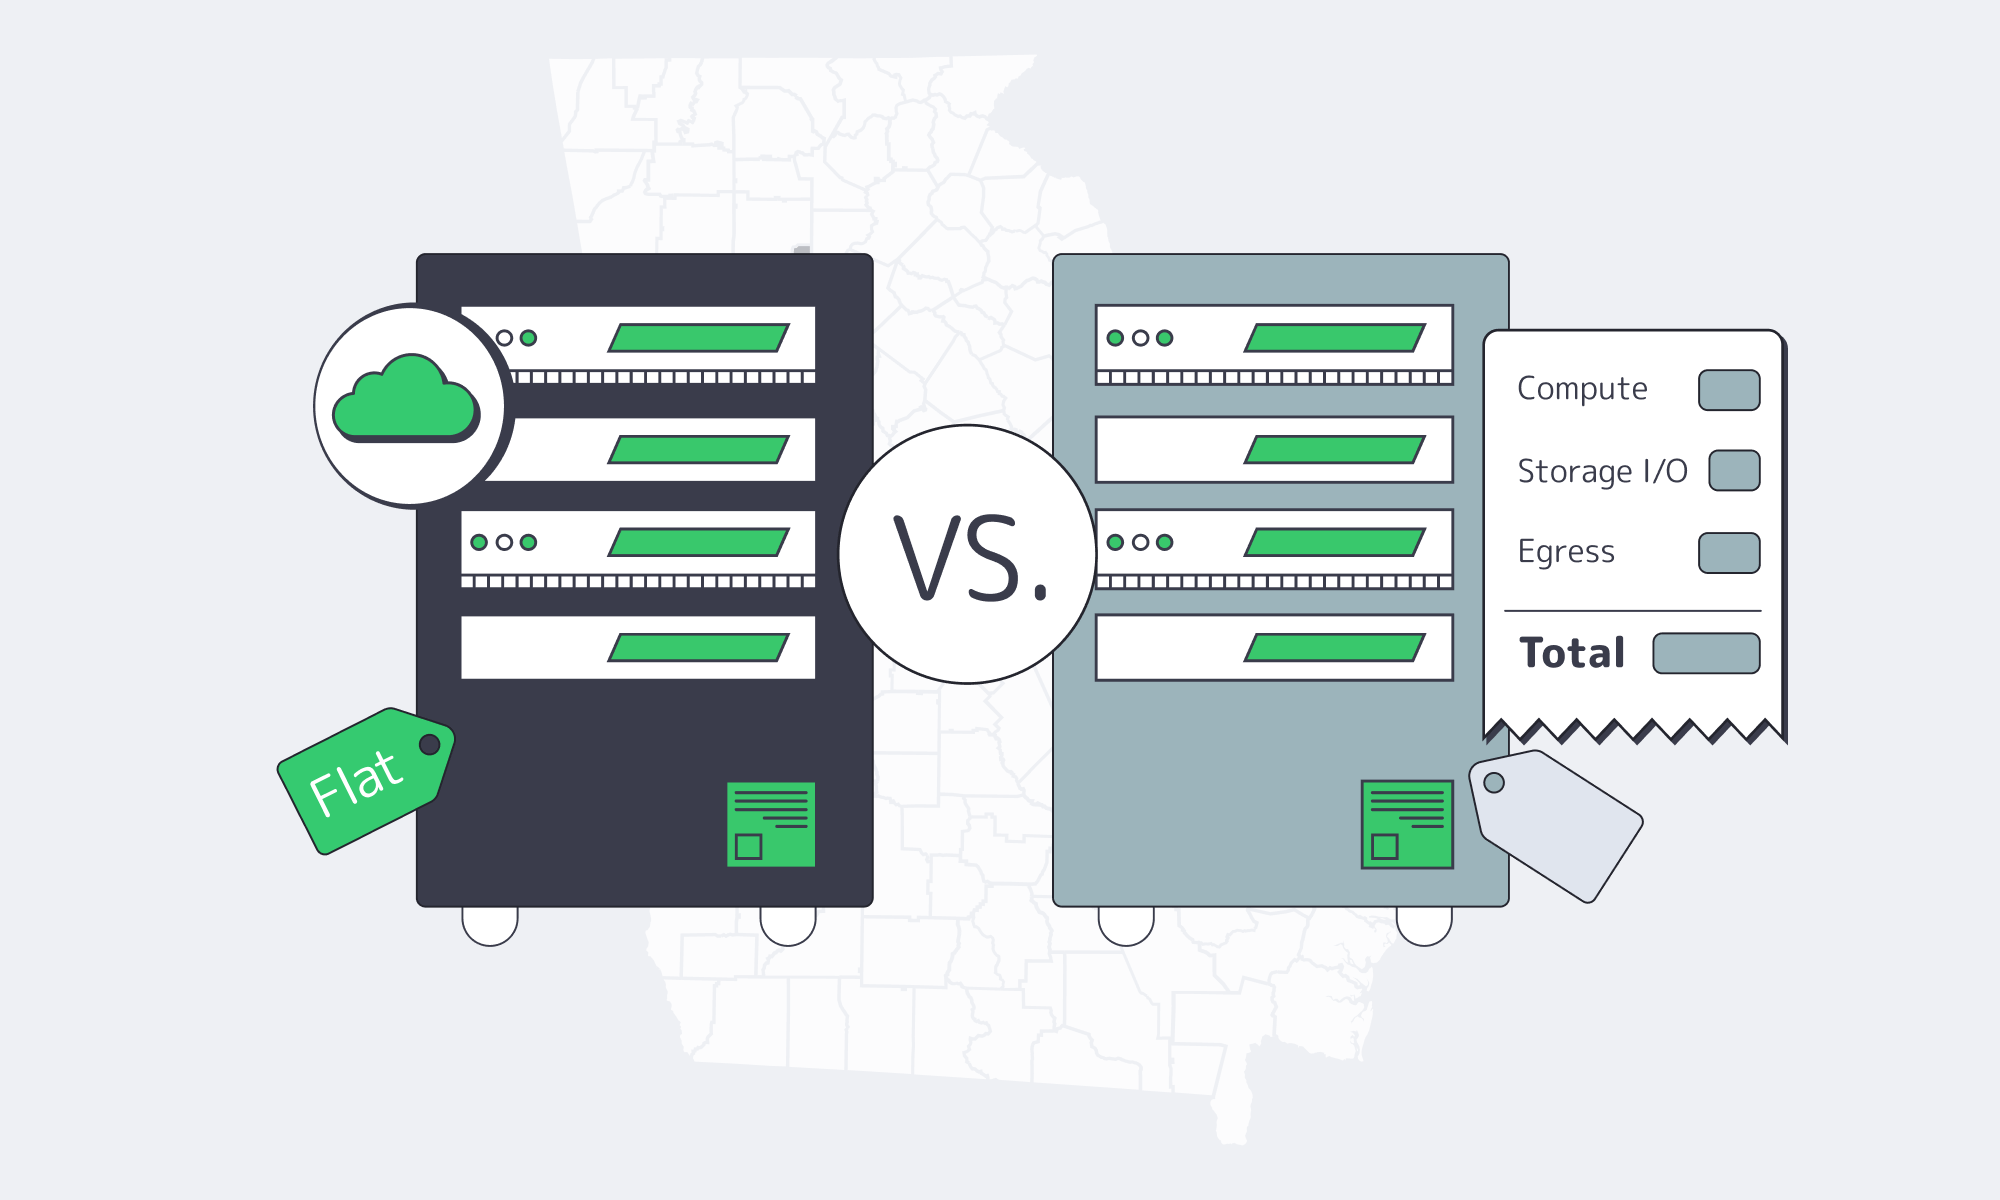
A spiky workload can suit elastic cloud capacity, whereas steady 24/7 loads warrant comparing compute, storage, and especially egress costs. Because dedicated servers reserve fixed capacity at a monthly price, budgeting can be more predictable. Transfer still follows the selected plan: compare its quota or unmetered terms with actual usage, not just the port speed.
Cost management remains the top cloud challenge in Flexera’s 2026 survey, but estimated wasted spend is not a projection of migration savings. Before moving, compare equivalent CPU, RAM, storage performance, and availability requirements; apply eligible cloud commitment discounts; and include administration, support, software, backups, and migration costs.
Case evidence must match the operating model: Dropbox’s filing describes custom-built colocated infrastructure with purchased or leased hardware, depreciation, facility costs, and temporary migration overlap, rather than rented dedicated hosting. 37signals’ January 2026 engineering account documents its storage migration, but does not establish that its five-year savings forecast has already been achieved. An Atlanta dedicated server can be a baseload cost anchor when a workload-specific total-cost comparison supports it.
Cost model at a glance
| Cost factor | Public cloud (on‑demand) | Dedicated server (Atlanta) |
|---|---|---|
| Pricing model | Compute time, storage, I/O, and transfer are billed according to the selected services and rates. | Fixed monthly CPU, RAM, and storage configuration; transfer allowance and optional services follow the plan. |
| Scalability vs. cost | Elastic capacity can follow demand, but autoscaling, quotas, and spending controls need configuration. | Capacity is reserved; growth can require an upgrade or another server, with additional cost and provisioning time. |
| Bandwidth charges | Outbound transfer is often metered per GB; allowances and rates vary by service and route. | 50 TB or unmetered Atlanta plans are available. Port speed and transfer allowance are separate limits. |
| Long‑term TCO | Can suit intermittent workloads; commitments and managed services may improve economics for steady workloads. | Can suit well-utilized baseloads; compare staffing, support, software, and resilience costs before assuming savings. |
Dedicated Servers: Consistent Performance
Multi-tenant cloud instances can share a physical host, so placement and resource contention may affect performance. Public clouds also offer dedicated hosts and fixed-performance instances; CPU-credit limits apply to burstable types.
With a dedicated server, no other tenant shares the server’s CPU, RAM, and local disks. This removes one source of contention, not every application, storage, or network bottleneck. In high-throughput pipelines or streaming workloads, consistency should be measured on comparable hardware rather than assumed from tenancy alone. In Atlanta specifically, Melbicom offers up to 200 Gbps per-server ports; end-to-end throughput still depends on the server configuration, application, and network path.
Dedicated Servers: More Control
Cloud abstraction limits some hardware-level choices, although available controls depend on the service. With dedicated servers, you control the OS, kernel parameters, storage layout, and network stack within the selected hardware and service scope. Need BGP to announce your own prefixes or a private network between nodes? Melbicom provides these options alongside hardware support; confirm firmware access, specific VLAN topologies, and any cross-provider connections before planning around them.
Specificity matters: placing servers in a Tier III facility in Atlanta, GA helps define data-location and physical-access requirements. Location and Tier level do not by themselves establish compliance; verify the applicable controls, contractual responsibilities, access logging, encryption, and recovery procedures for the workload.
How Can Cloud and Atlanta Dedicated Servers Work Together?
Hybrid hosting can place elastic, event-driven services in the cloud and steady databases, origin servers, or batch engines on Atlanta dedicated servers. The split is useful when measured workload demand supports reserved capacity and the savings or control benefits outweigh cross-environment data transfer, connectivity, and operational complexity.

For a hybrid deployment, confirm connectivity and charges between the chosen Atlanta facility and the cloud region; metro-wide interconnection does not make cross-connects automatic. Melbicom’s global CDN has 40 PoPs across 35 countries and can use an Atlanta dedicated server as an origin, serving cacheable content closer to users.
Dedicated Servers or Cloud: Which Fits?
Choose Atlanta dedicated servers when steady utilization, single-tenant hardware, and defined transfer allowances fit the workload. Choose cloud services when elasticity or managed features justify their total cost. Use a hybrid deployment when the benefits of splitting workloads exceed the added connectivity, data-transfer, and operational costs.
- Workload profile & predictability. Steady 24/7 demand → evaluate Atlanta dedicated server hosting using measured utilization and total cost; sudden or short-term demand → evaluate elastic cloud capacity.
- Budget control. Compare the full monthly server price and transfer terms with cloud rates, commitments, and spending controls. Flexera’s 2026 survey identifies spend management as the leading issue.
- Performance sensitivity. Benchmark throughput-bound or latency-critical systems (real-time analytics, trading, MMO backends, media origin) on comparable hardware. Single tenancy removes competing server tenants, not every source of variation.
- Geography. Test routes from Atlanta to the actual user networks and cloud regions. Southeastern U.S. placement may help, but proximity and carrier density do not establish a latency result.
- Control & compliance. Confirm required access, network isolation, and data-location controls. Melbicom supports BGP, private network options, and OS control in a Tier III Atlanta facility; verify workload compliance separately.
- Long‑term economics. Dropbox’s historical results and 37signals’ projection justify evaluating alternatives, not assuming savings. Include equivalent performance, cloud commitments, staffing, support, and migration in the comparison.
Balancing Cloud Elasticity with Atlanta’s Dedicated Server Predictability
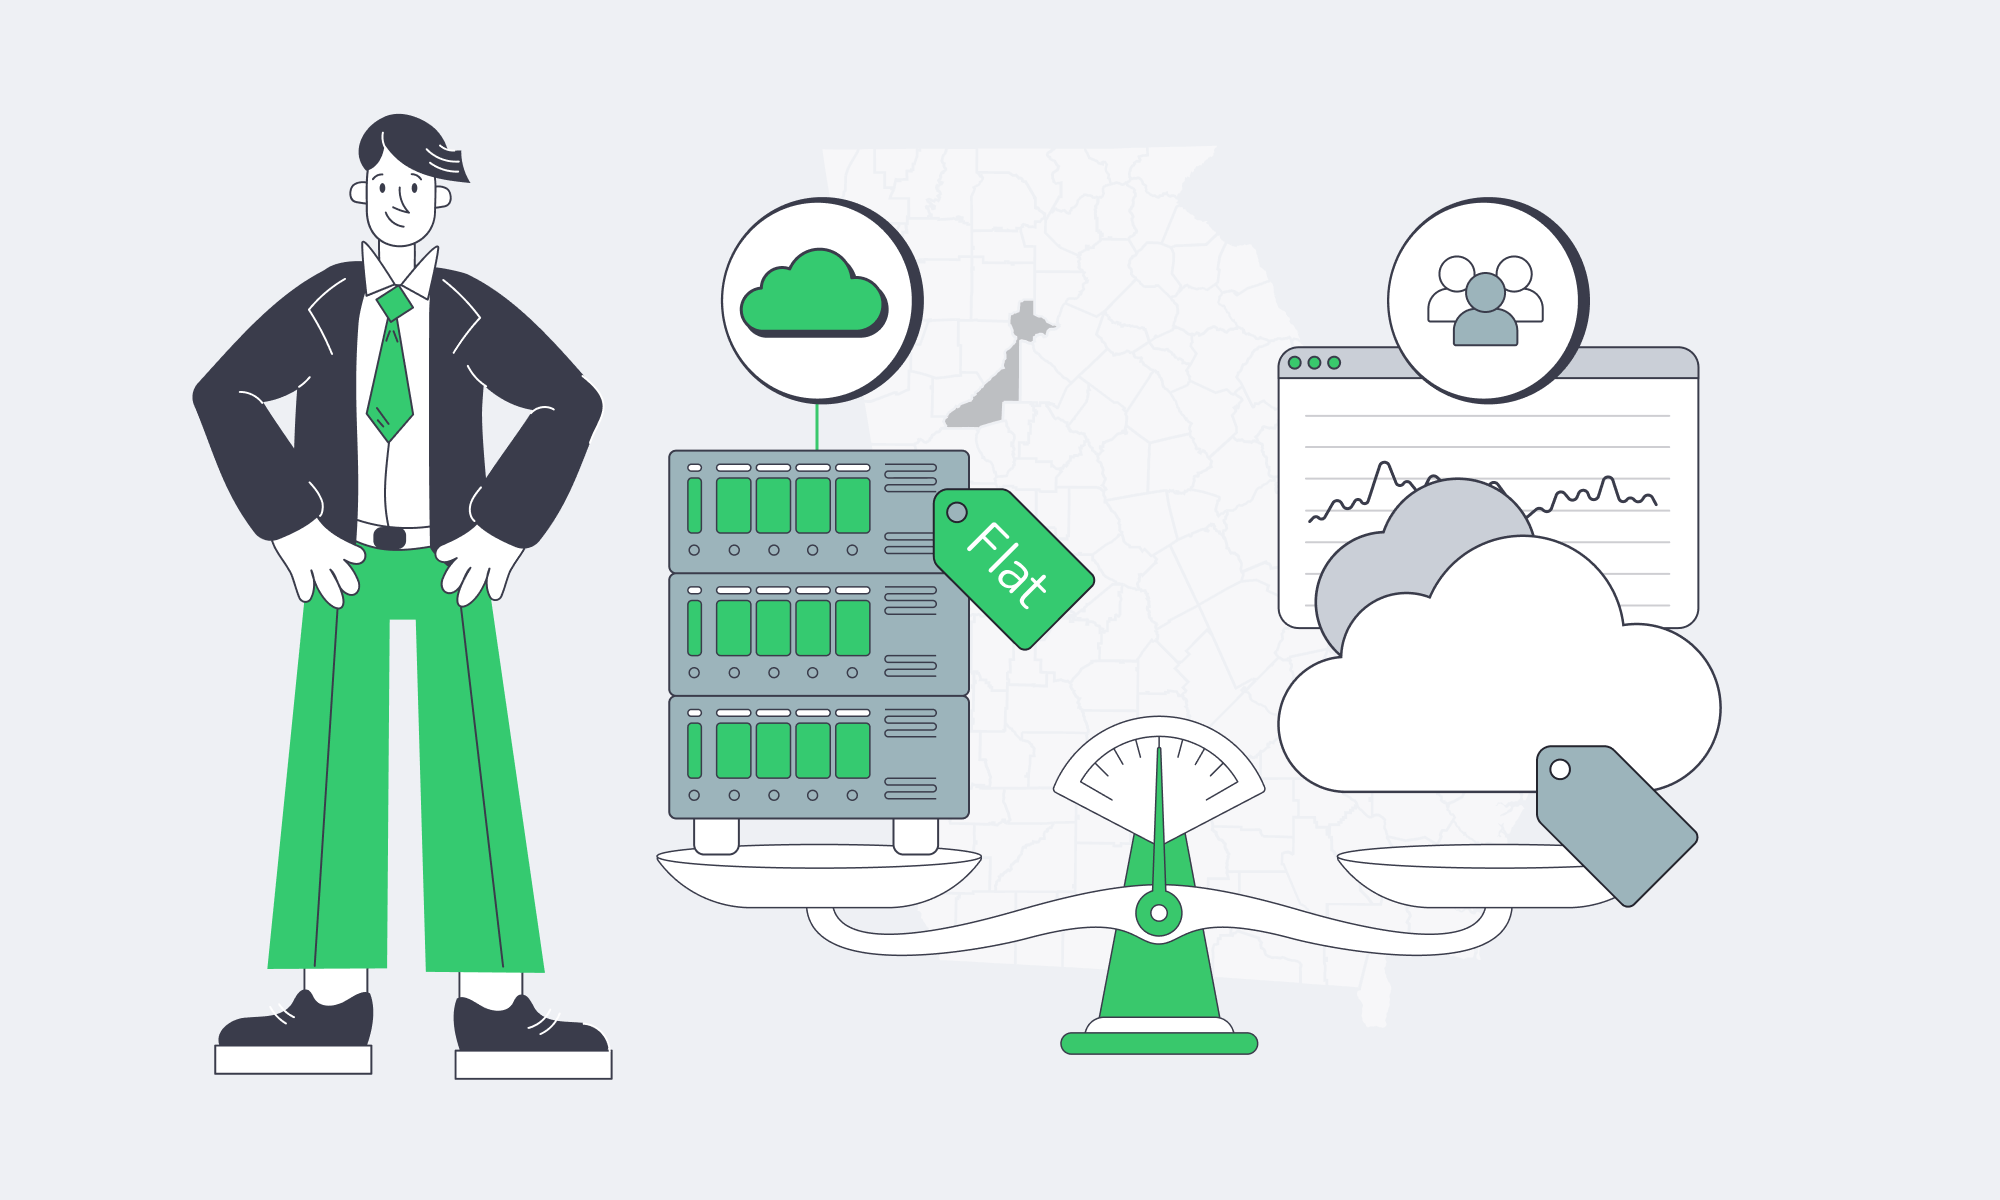
The cloud’s pay-as-you-go model is useful for experimentation, short-lived loads, and managed services. Stable, bandwidth-intensive workloads can benefit from dedicated hardware, but lower cost and better performance depend on utilization, configuration, and operations. A hybrid design can use Atlanta dedicated servers for baseload capacity and public cloud for on-demand elasticity when the combined cost and complexity are justified.
Atlanta adds interconnection choices and a substantial infrastructure ecosystem; the right placement still depends on measured paths to users and application dependencies. Melbicom combines a Tier III Atlanta facility, fast provisioning, and a high-throughput backbone, providing a dedicated option to evaluate alongside cloud services rather than an automatic replacement for them.
Deploy Atlanta Dedicated Servers
Order high‑bandwidth dedicated servers in Atlanta with fast setup, 24/7 support, and BGP options for predictable cost and consistent performance.
Get expert support with your services
Blog
Why UAE Hosting Delivers Speed, Compliance, and Scale
Enterprises serving customers across the Gulf now face a simple infrastructure question with complicated consequences: where should the origin servers live? For years, many hosted in Europe or North America and absorbed the cost of distance—triple‑digit‑millisecond round trips and cross‑border data exposure. Between London and Dubai alone, typical latency hovers around ~130 ms. Today, a dedicated server in the UAE places compute inside the region’s network core, aligning with data‑residency rules and delivering ultra‑low latency for fintech, e‑commerce, AI inference, streaming, and collaborative apps. This is no incremental tweak; it’s the difference between “fast enough” and instant—and between “legally acceptable” and locally compliant.
Choose Melbicom— {{servers_in_stock_fujairah}} ready-to-go servers — Tier III-certified DC in Fujairah — 40 PoP CDN across 6 continents |
|
Why Are Digital Demands in the Middle East Surging?
Two secular shifts define the region’s new reality. First, digital consumption and online commerce are exploding; Deloitte estimates Middle East e‑commerce will reach roughly US$50 billion in the near term, propelled by mobile adoption and pro‑digital policy. Second, data center capacity is ramping hard: PwC projects regional capacity to triple—from ~1 GW to ~3.3 GW—over five years, driven by cloud, AI, and sovereign data strategies. In other words, the demand side (users, transactions, streams) and the supply side (local compute, power, and interconnects) are meeting in the UAE and its neighbors, making a regional hosting footprint both practical and advantageous.
What Do Strict Data‑Residency Laws Mean for Your Hosting Strategy?
Compliance has moved infrastructure decisions from “best practice” to “must have.” In the UAE, sector rules make the stakes explicit:
- Payments: The Central Bank’s Retail Payment Services and Card Schemes Regulation requires payment service providers to store and maintain personal and payment data within the UAE, with secure backups retained locally.
- Healthcare: The Health Data Law (Federal Law No. 2 of 2019) limits the transfer or processing of UAE health data outside the country except under defined exceptions.
- IoT: The national IoT regulatory policy requires Secret/Sensitive/Confidential data—especially for government or critical infrastructure—to remain in the UAE.
Leading firms summarize the risk plainly: non‑compliance may trigger fines, service suspensions, or even criminal penalties—and cross‑border transfers face stricter scrutiny.
Creating Measurable Advantage via Ultra‑Low Latency

Latency is not an abstraction; users feel it. Human‑factors research shows three crucial thresholds: ~0.1 s feels instantaneous, ~1 s remains flow‑friendly, and >10 s breaks focus—guardrails that translate directly to web and app UX. For revenue‑producing funnels, the numbers are unforgiving: a 100‑ms delay can cut conversions by up to 7%, and 53% of mobile visitors abandon pages exceeding three seconds.
The geography of your origin matters more than any front‑end micro‑optimization. Hosting in Europe or the U.S. keeps round‑trips in the triple‑digit milliseconds for Gulf users (e.g., London–Dubai ~133 ms), whereas a UAE origin collapses that to tens of milliseconds. The regional UAE‑IX exchange (operated by DE‑CIX) keeps traffic local and has demonstrated latency reductions of up to 80% for gaming and interactive content—precisely the workloads most sensitive to jitter and lag.
For industries where milliseconds decide outcomes, the bar is even higher. As DataBank’s Gregory Ryman notes, “Whereas milliseconds were once acceptable, microsecond responses are now required” for trading, payments, and real‑time analytics. AI inference pipelines and personalization engines show similar sensitivity; moving model scoring closer to users reduces tail latency and bandwidth costs, enabling richer on‑page experiences without the penalty of long‑haul calls.
Local UAE Server vs. Overseas Hosting: What changes in practice?
| Factor | UAE Dedicated Server | Overseas Hosting (EU/US) |
|---|---|---|
| Data compliance | Meets UAE localization (payments, health, IoT), keeping sensitive records on UAE soil. | Cross‑border exposure; additional legal burden for transfers and higher penalty risk if localization applies. |
| Latency to Gulf users | Tens of milliseconds via in‑country peering and regional IXs (UAE‑IX). Up to 80% lower vs. out‑of‑region. | 100–200+ ms transcontinental RTT common; sluggish UX under load. |
| User experience | Faster pages and APIs → higher conversions and engagement. | Slower flows → bounce and cart abandonment. |
| Network resilience | Local exchanges + diverse subsea routes keep Gulf traffic in‑region. | Long‑haul dependency raises risk from cable events and congestion. |
| Operational control | Local time‑zone support and auditability under UAE standards. | Remote operations across time zones and jurisdictions. |
What Makes UAE Data Centers Genuinely World‑Class?
Three ingredients: tiered facilities, dense interconnects, and subsea diversity.
- Tiered reliability at scale. The UAE hosts multiple Tier III+ sites, including in Fujairah and Dubai, designed for concurrent maintainability and enterprise uptime.
- A heavyweight Internet core. UAE‑IX (DE‑CIX) now connects 110+ networks and pushes terabit‑scale peaks, keeping content, cloud, and eyeballs local—explicitly to reduce latency and improve experience.
- A cable‑landing powerhouse. Fujairah is the Middle East’s largest subsea landing hub, with systems like AAE‑1, EIG, GBI, SEA‑ME‑WE variants, and the 2Africa mega‑cable adding more diversity via the UAE’s east coast (Kalba). This translates to east‑west path optionality and fast failover when one route degrades.
On top of the physical network, capacity headroom is real. We at Melbicom operate dedicated servers in Fujairah with dedicated port options up to 20 Gbps locally, and per‑server bandwidth up to 200 Gbps in select global locations, with a CDN spanning 40 PoPs to accelerate static/video workloads outside the Gulf. Free 24/7 support remains standard for dedicated servers.
Why Choose a UAE Dedicated Server Strategy Over “Host Elsewhere and Hope”?
Because distance and jurisdiction now impose hard costs. The UAE offers a rare combination—lawful locality, tens‑of‑milliseconds proximity, and carrier‑dense interconnects—that few offshore options can match for Gulf user bases. The result is not just faster pages; it’s fewer abandoned checkouts, snappier banking flows, and smoother AI‑assisted experiences.
When is dedicated server hosting in UAE non‑negotiable:
- You process regulated data (payments, health, government/IoT), or must prove records stay in‑country.
- You sell or trade in real time (fintech, marketplaces, gaming) where milliseconds—or microseconds—matter.
- Your conversion engine depends on speed (retail, subscriptions, ads), and you can’t afford 100‑ms tax from offshore origins.
- You need scale and resilience with in‑region peering and subsea path diversity—not single‑continent bets.
Where Does the UAE Stand vs. Saudi Arabia and Qatar?
All three markets are modernizing fast and tightening oversight of personal data. Saudi Arabia’s PDPL and sector frameworks (e.g., SAMA) restrict cross‑border transfers and increasingly enforce localization—making in‑KSA hosting advisable for Saudi‑resident datasets. Qatar’s PDPPL also limits transfers and prescribes fines.
What makes the UAE uniquely useful is its function as the GCC interconnect fabric—home to UAE‑IX and Fujairah’s cable landings—so UAE servers serve the wider region with lower latency, even as organizations stand up country‑specific clusters where laws require. Many enterprises therefore adopt hybrid regional topologies: a UAE origin for GCC‑wide proximity and shared workloads, plus in‑country nodes where sectoral laws demand.
Local Infrastructure Has Become Table Stakes
Data sovereignty and user experience are now board‑level issues in the Gulf. The shortest, safest path to both is to run your origin in the UAE—within the jurisdiction that governs your customers and close enough to render the network invisible. With e‑commerce growth, AI‑heavy applications, and payments modernization all accelerating, the performance and compliance dividend from UAE hosting compounds year over year.
The strategic calculus is simple: if your revenue, risk, or reputation depends on speed and lawful processing in the GCC, a UAE dedicated server is no longer optional. It’s the foundation for the services your users already expect.
Deploy a UAE dedicated server
Place your workloads in Fujairah for low latency, local compliance, and carrier‑dense connectivity. Choose from ready configurations and ports up to 20 Gbps, backed by 24/7 support.
Get expert support with your services
Blog
Dedicated Servers Powering Real-Time Web3 Gaming Worlds
The vision for Web3 games is shifting from simple collectibles to persistent, living worlds where thousands of people can play together in real time. DappRadar’s Q3 2025 report recorded an average of 4.66 million daily unique active wallets in gaming, down 4.4% from the previous quarter; gaming represented 25% of tracked active wallets. These are on‑chain activity metrics, not counts of unique people, concurrent players, or proven demand for game-server capacity.
Live events provide a separate measure of concurrency. On March 25, 2023, Yuga Labs’ Otherside Second Trip demo hosted more than 7,200 concurrent users in a shared virtual world, powered by Improbable. Fortnite’s April 2020 Travis Scott event drew more than 12.3 million concurrent players across the platform—not in one shared simulation. Neither figure is a per-server capacity benchmark.
So, what does that imply for infrastructure? Future Web3 worlds must prioritize latency, concurrency, and data distribution, and on‑chain features must not slow the gameplay loop. This is where dedicated servers—single‑tenant machines deployed in the right regions—do the heavy lifting.
What Infrastructure Challenges Do Web3 Games Need to Solve?
Concurrency at event scale. Live metaverse events—concerts, tournaments, open‑world festivals—can bring thousands of participants into a shared space. The simulation and networking need to scale across cores and machines while preserving authoritative world state. Otherside’s March 2023 demo had more than 7,200 concurrent users; game capacity depends on its simulation, networking, and tested architecture.
Ultra‑low latency. In immersive play, milliseconds matter, but network round-trip time (RTT), input-to-result latency, and XR motion-to-photon latency are different measurements. A 2020 player survey described noticeable network latency around 50 ms, with substantial variation; this is not a universal performance threshold. A 2019 VR display paper discussed a ~20 ms motion-to-photon design target, not a server RTT target or a comfort guarantee. Placing servers close to players can reduce the network component, but input processing, simulation, rendering, and display timing must also be measured.
Global reach and edge distribution. A single metaverse event can attract players across Los Angeles, London, Lagos, and Singapore simultaneously. Regional ingress and edge caching can shorten delivery paths, while the application coordinates state between regions. Select regions using measured player latency and capacity; DNS or anycast alone does not guarantee the geographically closest or lowest-latency server.
Throughput & content gravity. These worlds move heavy data—3D assets, voice, and real‑time state updates—so origin bandwidth must absorb bursts identified through load testing while the CDN keeps assets near users.
Frictionless on‑chain integration. Users expect NFT mints, trades, and in‑game ownership updates to feel responsive, so the backend should decouple gameplay from on‑chain settlement. Reliable full‑node/RPC infrastructure can reduce request latency, but a successful RPC response does not establish transaction confirmation or finality. Show pending status until the application’s confirmation requirements are met.
Why Dedicated Servers for Web3 Gaming?
Dedicated servers for Web3 gaming give studios exclusive CPU, memory, and storage resources, plus control over networking. Regional deployment can reduce network RTT, while separating simulation from RPC and indexing workloads limits resource contention. Studios still need load testing, capacity planning, and application-level failover; dedicated hardware alone does not guarantee performance.
Exclusive resources, more predictable tick timing. Dedicated CPUs, RAM, and NVMe remove contention from other tenants on the same host. Separate or resource-limit simulation and blockchain indexing to limit contention between your own workloads.
High‑throughput networking and peering. Melbicom offers ports up to 200 Gbps per server and a backbone connected to 23 transit providers and 29 IXPs.
Global footprint to cut RTT. Melbicom lists 21 Tier III/IV data centers, including the coming-soon Marseille and São Paulo facilities, and a CDN with 40 PoPs across 35 countries. Use available server locations for simulation and CDN edges to serve assets.
Choose Melbicom— 1000+ ready-to-go configurations — 21 Tier III/IV data centers — 40 PoP CDN across 6 continents |
|
Provisioning scale and speed. Pre‑warm for mints, season resets, or in‑game concerts: Melbicom maintains 1000+ ready‑to‑go configurations with 2‑hour activation time.
Endpoint stability & network control. Teams can use BGP sessions and BYOIP to keep RPC, matchmaking, and ingress addresses consistent during maintenance and scaling. Anycast routing and application failover require deliberate design; route changes do not preserve game-session state by themselves.
24/7 support. Hardware replacement and infrastructure troubleshooting are available 24/7. Studios remain responsible for their game and blockchain software.
Bottom line: Dedicated servers give Web3 studios control over the resources and network design needed for low latency, high concurrency, and on‑chain integration.
Dedicated Servers for Real‑Time Web3
| Requirement | Why it matters now | Dedicated server solutions |
|---|---|---|
| Ultra‑low latency | Network RTT, input-to-result latency, and XR motion-to-photon latency are separate budgets; acceptable thresholds depend on the game and device pipeline. | Choose regional placement and peering using measured player paths; benchmark CPU tick time and NVMe I/O under representative load. |
| High concurrency | Virtual‑world events can involve thousands of users in a shared space; infrastructure must preserve authoritative state and acceptable tick timing as load grows. | Deploy server pools per location and partition authoritative state according to the game engine. Load balancers distribute connections; they do not create a shared simulation alone. |
| On‑chain integration | Gameplay must not wait for block confirmation or finality. | Run full nodes on dedicated machines and isolate private RPC pools from shared-endpoint traffic; queue on‑chain actions and reconcile confirmation state in the backend. |
| Throughput & asset delivery | 3D assets, voice, telemetry, and patches can create bursts across backend and origin links. | Absorb bursts with Melbicom ports up to 200 Gbps, and serve edge-cached content across 40 CDN PoP locations. |
| Reliability | Player economies depend on recoverable state and predictable service availability. | Tier III/IV facilities and single‑tenant isolation provide the infrastructure foundation; add backups, replication, and tested multi-region failover for application resilience. |
How to Architect a Real‑Time Metaverse?
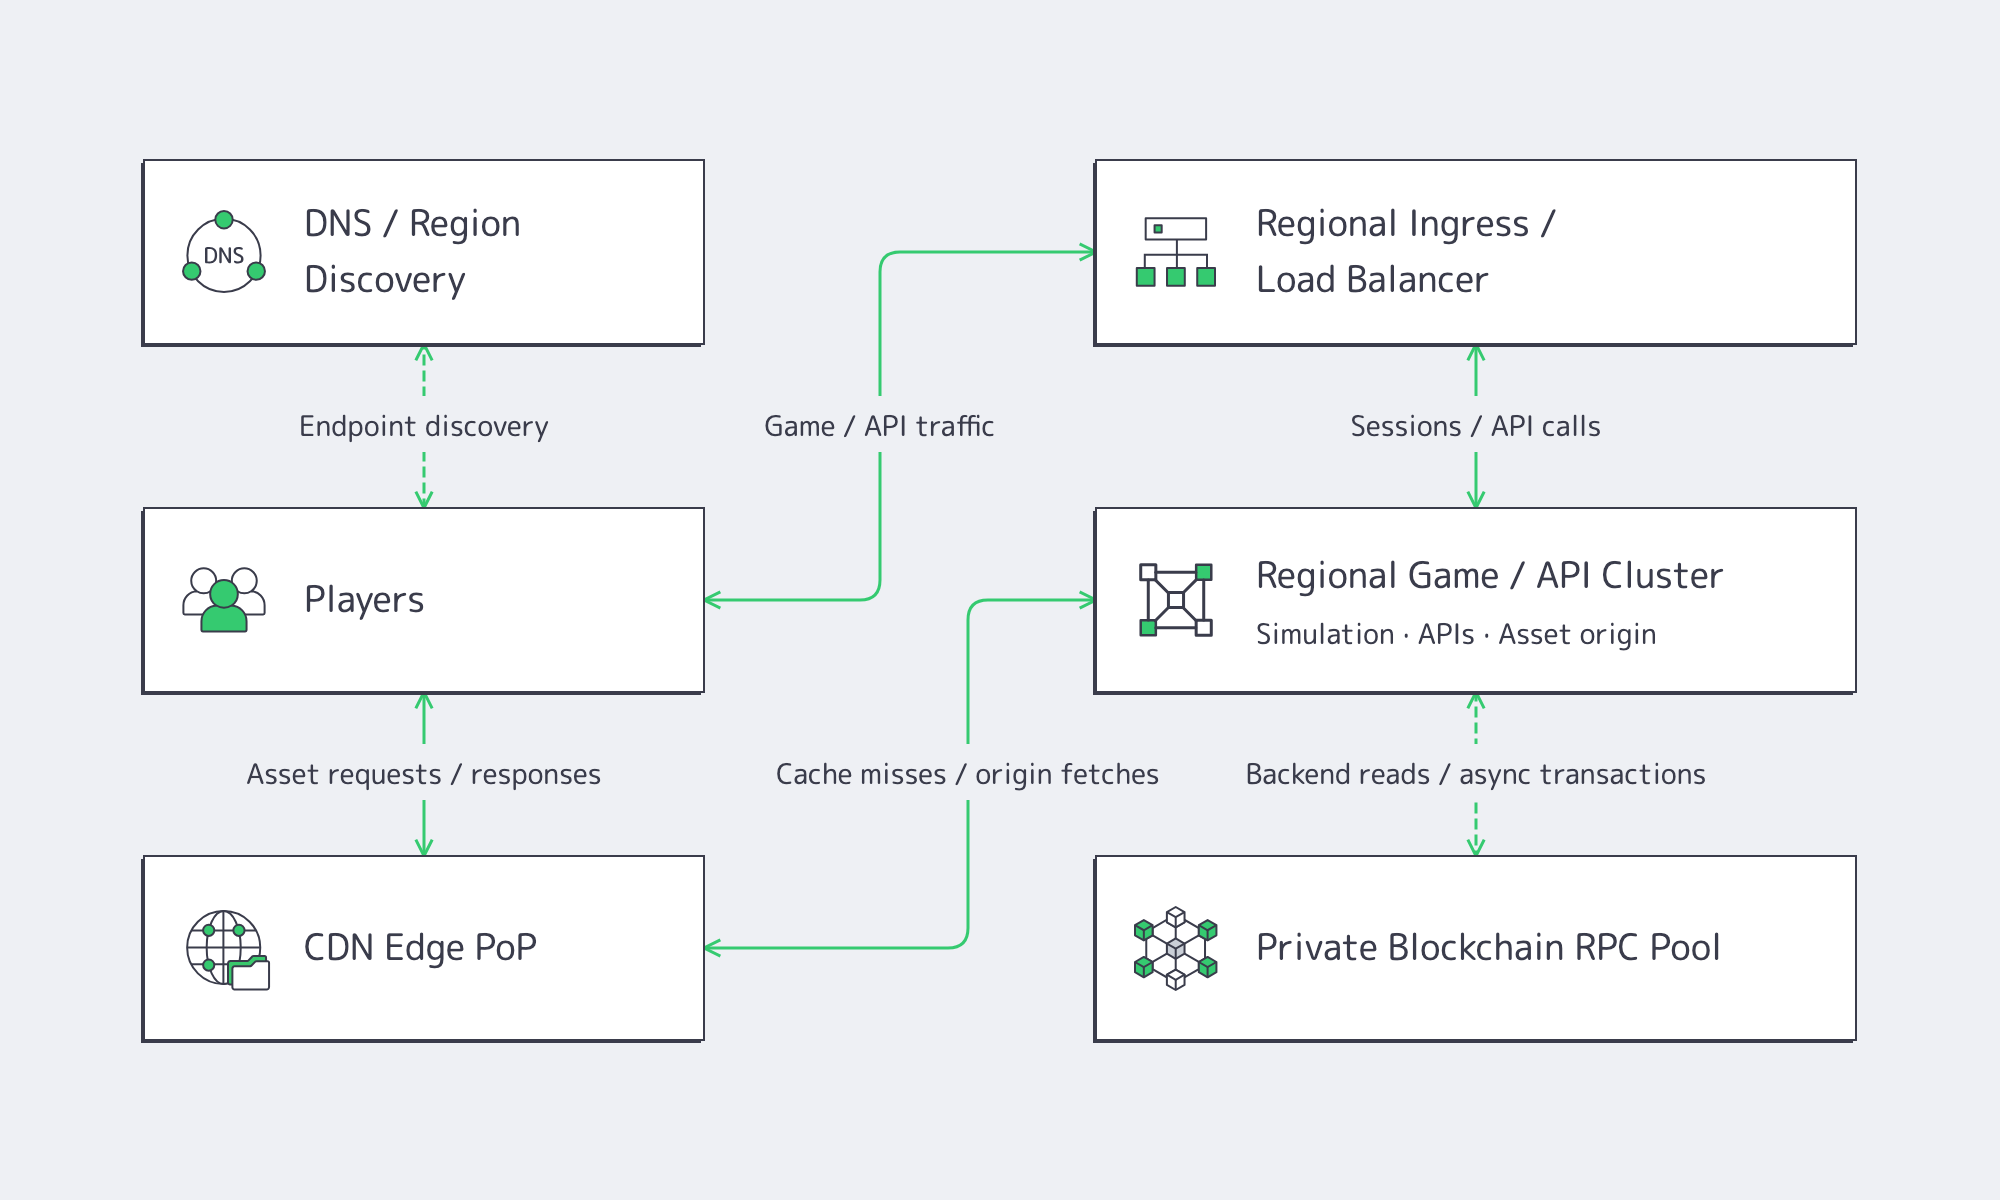
Place regions deliberately and push latency‑sensitive work to the edge. Use DNS-based region discovery and health-checked ingress to select a region using measured latency and capacity; anycast alone does not guarantee the lowest RTT. Synchronize required state over private inter-data-center links, while keeping latency-sensitive simulation regional. Melbicom’s regional servers and CDN provide separate compute and asset-delivery layers.
Decompose the backend. Separate authoritative simulation from matchmaking, profiles/inventory, and blockchain I/O so each service can scale independently. Stateless APIs can be replicated, while stateful simulation and databases need explicit partitioning, replication, and recovery plans.
Run your blockchain layer locally. Deploy full/archival nodes (and indexers) on dedicated servers with NVMe and high‑bandwidth ports; front them with load‑balanced private RPC and monitor query latency and node synchronization.
Turn the CDN into a force multiplier. Keep origins lean and let the CDN serve cacheable textures, snapshots, metadata, patches, and UGC while origins handle simulation and real‑time APIs. In this design, private blockchain RPC traffic runs between the backend and RPC pool, not through the asset CDN.
Instrument like an exchange. Capture server tick timing, queue depths, p95/p99 latencies, and mempool/RPC health in real time. This is where “real‑time metaverse infrastructure” intersects with ops: anomaly detection and predictive scaling (including AI‑assisted) can help you add capacity before users feel pain.
Blockchain game hosting: patterns that work now
- Maintain regional read replicas for inventory and ownership queries, with freshness checks before ownership-sensitive actions.
- Settle on‑chain asynchronously; show pending status until the required confirmations arrive, and reconcile rejected or reorganized transactions.
- Use multichain RPC pools and stable BGP prefixes to reduce endpoint allowlist churn.
Real‑time metaverse infrastructure: edge and AI
- Edge placement can reduce the network portion of streamed XR latency; the motion-to-photon budget also includes sensing, rendering, and display time.
- AI-assisted operations can analyze telemetry for rising p95 latency, flag regional bottlenecks, and trigger preconfigured scaling for chat, voice, or other supporting services before an event reaches a tested capacity threshold.
Key Takeaways for Technical Leaders
- Make latency the first metric. Measure network RTT and input-to-result latency separately; validate XR motion-to-photon latency on the target devices. Place servers locally and minimize cross‑ocean paths.
- Plan for event‑level concurrency. Size individual worlds and platform-wide events separately, using load tests, load‑shedding, and back‑pressure.
- Decouple gameplay from settlement. Run your own nodes to isolate RPC resources; monitor their latency and health, and queue/reconcile on‑chain actions.
- Exploit bandwidth + CDN. Use Melbicom’s origin ports up to 200 Gbps and let a 40 PoP CDN handle asset gravity.
- Control the network. Use BGP/BYOIP to keep endpoint addresses consistent through scaling and maintenance; test application-level recovery separately.
- Provision fast. 1000+ ready‑to‑go configurations with 2‑hour activation.
Where Should Teams Build Next?
Web3 games with larger shared spaces and on‑chain economies need regional compute, high‑throughput networking, and responsive RPC services. Dedicated servers provide a single‑tenant foundation and direct network control. Wallet-activity reports describe on‑chain engagement; live-event concurrency examples illustrate a different requirement. Size infrastructure from the game’s actual simulation, traffic, and settlement workloads.
Melbicom’s approach is to make that foundation turnkey: place authoritative servers close to your audience; front assets with a global CDN; keep RPC endpoints regional and stable; and scale horizontally with ready-to-go capacity.
Launch low‑latency Web3 infrastructure
Get dedicated servers, global CDN, and stable BGP endpoints with rapid provisioning to power real‑time Web3 games and metaverse events.
Get expert support with your services
Blog

Brazil CDN and Dedicated Origins: Faster South American Streaming
Update
September 2026: Melbicom’s current Brazil CDN PoPs are in Fortaleza and Rio de Janeiro. São Paulo is a coming-soon dedicated-server location, not a current CDN PoP. The São Paulo origin-shield design below is a deployment plan; confirm server availability, final ports, and the required cache hierarchy before ordering.
South American audiences are impatient with slow‑loading content, and distant origins can increase time‑to‑first‑byte (TTFB) and rebuffering risk, while routing, available throughput, and player behavior also affect results. Deploying CDN edge PoPs close to viewers and pairing them with a Brazil‑based origin or a configured caching layer on a local dedicated server can shorten delivery paths. Validate the improvement under real traffic rather than assuming a fixed latency reduction or the elimination of rebuffering.
Host in LATAM— Reserve servers in São Paulo — 6 CDN PoPs in 5 LATAM countries — 21 Tier III & IV DCs, including Brazil |
|
Why Distance Still Matters for Streaming Quality in South America
When an origin is on the U.S. East Coast, South American cache misses can incur a long network trip. As one route-specific example, CloudPing’s AWS inter-region matrix showed approximately 115 ms between São Paulo (sa-east-1) and Northern Virginia (us-east-1) on September 16, 2026. This is not a regional average, a viewer TTFB measurement, or a Melbicom benchmark. São Paulo↔Buenos Aires pings likewise concern particular measurement hosts; test the actual edge-to-origin route before using a city-pair result in a deployment plan.
Mobile access varies: a countrywide mobile-latency average is not a CDN-to-origin RTT or an application TTFB target. Compare startup time and rebuffering by operator and connection type rather than treating one country’s average as a universal benchmark.
Higher network latency can delay startup, and modern viewers expect seamless streams. A 2012 study of on-demand video, based predominantly on North American views, found that abandonment rose as startup waits increased beyond roughly two seconds. That historical result is not a current Brazil-specific or live-streaming forecast. Keeping content closer to viewers is one way to reduce startup delay, alongside player and delivery optimization.
How Can a Brazil CDN Help Streaming?
A CDN in Brazil can shorten delivery paths by serving cached video segments near viewers. Pairing those edges with a regional origin can also reduce cache-miss delays when routing is favorable. Choose locations using measured viewer-to-edge and edge-to-origin performance, then validate startup time, cache-hit ratio, and rebuffering under peak load.
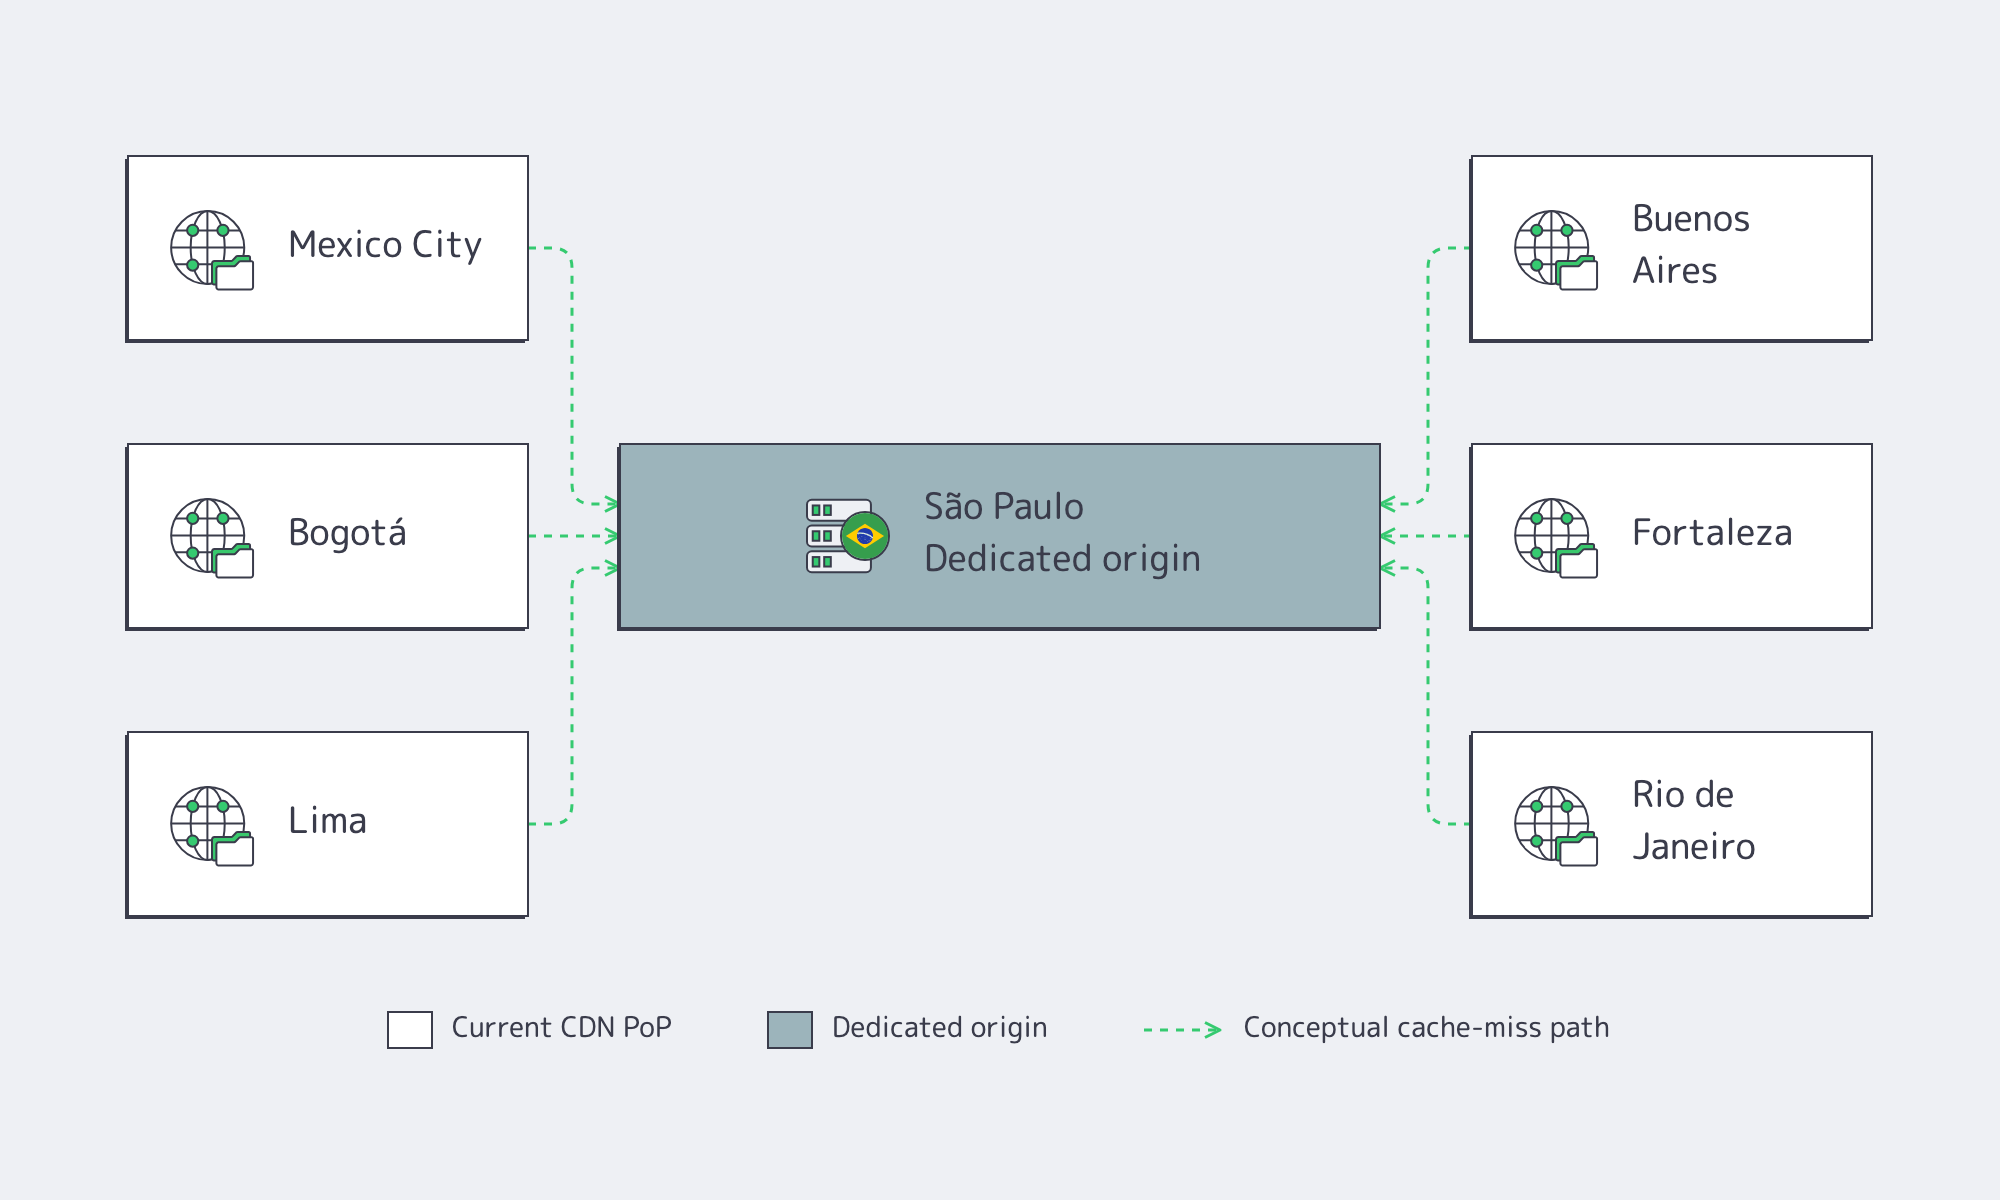
A Latin American edge paired with a distant origin can still serve cache hits locally, but misses and live segment fills depend on the origin path. Multi‑PoP coverage across population centers should therefore be evaluated alongside origin placement. Melbicom’s CDN spans 40 PoPs across 35 countries, including Buenos Aires, Fortaleza, Rio de Janeiro, Bogotá, Mexico City, and Lima. These six LATAM PoPs cover 5 countries; a listed PoP does not guarantee the geographically nearest route or a fixed TTFB.
Latency scenarios and what to measure
| Delivery scenario | Latency evidence or measurement | Performance impact |
|---|---|---|
| North America ↔ Brazil: AWS route example | ~115 ms for São Paulo ↔ Northern Virginia; September 16, 2026 snapshot. | Illustrates a long origin-fetch path, not a universal viewer-latency benchmark. |
| Regional origin in Brazil (e.g., São Paulo) | Measure the selected edge-to-origin route. | Can reduce miss and fill delays when the measured route is shorter. |
| Local in‑country edge cache (e.g., Buenos Aires PoP) | Measure viewer-to-edge RTT and cache-hit TTFB by ISP. | Cache hits avoid an origin fetch; access-network conditions still affect playback. |
Edge Caching Paired with a São Paulo Origin Shield on a Local Dedicated Server
While hits can be handled with edge caching, a fast origin is still needed for misses and cache fills. A self-managed caching proxy on a local dedicated server in São Paulo can act as a regional origin shield once that capacity is available. Configure the cache hierarchy and test routes; geography alone does not ensure that fill traffic stays in South America. This combination can provide the following benefits:
- Lower miss penalty. A regional origin can shorten an edge’s fetch path compared with a distant origin, but the gain depends on the actual route and whether the shield itself has the requested content.
- Thundering herd shielding. Configure request coalescing for cacheable objects so concurrent misses for the same cache key can share a fill rather than all reaching the content backend.
- Spike Headroom. Size storage, CPU, and network capacity for measured fill traffic and peak cache-miss load. Confirm final São Paulo hardware and ports in the quote rather than treating the global bandwidth range as a local delivery guarantee.
This architecture does not require a public cloud region, but a dedicated server does not automatically provide managed caching or failover. Melbicom’s optional Origin Shield setting is a separate CDN feature that routes misses through a shared edge node after it is enabled. Do not assume that this node is in São Paulo or that a particular parent hierarchy is selectable.
Which Protocol and Media Optimizations Actually Make a Difference?
TLS and HTTP versions
New encrypted connections incur handshake delay; an established connection can carry many segment requests. A normal TLS 1.3 handshake takes one RTT, with TCP setup additional when TLS runs over TCP. Optional 0‑RTT early data requires compatible resumption support and replay-safe application use; it is not a general promise for repeat connections. Terminating TLS closer to users can reduce setup time, but not to zero.
HTTP/2 remains a staple. HTTP/3/QUIC avoids transport-level head-of-line blocking between independent streams, not all packet-loss delays. For a CDN in Brazil, verify TLS 1.3, HTTP/2, and HTTP/3 support for the resource and client base, and retain HTTP/2 fallback where QUIC is unavailable. Do not assume every LATAM PoP supports all protocols.
Image and video: Optimizing at the edge
Images: To make the most of the latency wins that are associated with using a Brazilian CDN network, convert images to WebP/AVIF wherever supported, resize for specific devices, and apply Brotli for text and manifests. Perform image conversion and resizing in your media pipeline or a confirmed optimization service; CDN caching alone does not create those variants.
Video: keep popular renditions warm by caching HLS/DASH segments at edges and regionalize packaging/transcoding by creating and holding bitrate ladders near São Paulo if feasible. Melbicom’s CDN delivers pre-transcoded HLS/DASH streams; packaging and transcoding require a separate workflow. Placing that workflow near ingestion and the origin can reduce repeated long-haul transfers, but measure startup time and rebuffering.
Route packets regionally
Sparse regional peering can create unnecessary long-haul paths, so evaluate a CDN provider in Brazil against these requirements:
- Favor local interconnection. Review peering at IX.br (São Paulo) and relevant local IXPs in Buenos Aires, Santiago, Bogotá, Lima, and Mexico City. Verify the actual routes rather than inferring them from IXP membership.
- Evaluate regional parents for cache misses: a Bogotá edge → São Paulo caching-origin path is a design option to test, not a confirmed managed-shield configuration.
- Steer using telemetry: RTT, loss, and 95th‑percentile TTFB. Test failover to eligible healthy edges; a warm Buenos Aires cache alone does not establish an automatic failover policy.
The bottom line is to keep delivery short by using predictable paths that keep TTFB and loss‑triggered bitrate downshifts low.
Brazil Deploy Guide— Avoid costly mistakes — Real RTT & backbone insights — Architecture playbook for LATAM |
|
An Ideal Rollout Plan
- Map your audience density: Evaluate viewers and growth in hubs such as São Paulo, Mexico City, Buenos Aires, Bogotá, Santiago, and Lima.
- Start with a regional origin shield in Brazil: Plan a dedicated origin in/near São Paulo, with storage and ports confirmed in the quote. Configure caching and miss coalescing rather than assuming that server provisioning supplies them.
- Place edges local to users: Evaluate Melbicom’s current LATAM PoPs in Buenos Aires, Fortaleza, Rio de Janeiro, Bogotá, Mexico City, and Lima against actual viewer routes.
- Use TLS 1.3 + H2/H3 where supported: Verify the serving edge and client protocol support, test session resumption, and keep an HTTP/2 fallback.
- Optimize media for the edge: Format images by converting and resizing, cache eligible ABR segments with suitable TTLs, and keep hot titles pre‑warmed without serving stale live playlists.
- Validate regional routes: Test peering and backhaul before relying on a cache‑parent hierarchy with a São Paulo origin; a regional address alone does not guarantee a regional path.
- Instrument and iterate: Analyze country‑level TTFB and rebuffer ratio by ISP and cache status. Investigate deviations from your own performance baseline before changing capacity, routing, or edge coverage.
- Forecast capacity: To make sure live events don’t stress your shields, size them adequately. Load-test concurrent fills and peak miss traffic against confirmed origin and edge capacity.
CDN and Brazil Origin Shields
Combining a CDN and a properly configured dedicated server origin shield can address network-related contributors to end‑to‑end stalling in the following ways:
- First byte times: Terminating TLS at well-connected in‑country PoPs can shorten connection setup; it does not remove DNS, application, or player startup work.
- Segment fetches: Serving cache hits from nearby edges can shorten segment fetches, while sustained throughput and player buffering still affect playback.
- Miss penalty: A São Paulo cache can reduce remote-origin fills when it holds the requested content. Measure the full path for upstream cache misses.
These changes can improve delivery, but proximity alone does not determine rebuffering or retention. Validate startup time, sustainable bitrate, and rebuffer ratio under representative load rather than assuming longer sessions or higher customer lifetime value.
Where Should a CDN and São Paulo Origin Fit in LATAM Roadmaps?
Grand View Research forecasts a 21.7% compound annual growth rate for Latin America’s video streaming market revenue from 2025 to 2030. For capacity planning, combine that market outlook with your own audience and bitrate forecasts:
- Plan regional delivery first, pairing suitable edges with a configured São Paulo origin when available.
- Expand edge coverage to secondary metros as country‑level TTFB and rebuffer telemetry dictate.
- Use in‑region packagers/transcoders to reduce cold‑start penalties on hot titles.
Moving from a single edge to broader coverage can improve delivery, but it does not guarantee fewer cold starts. Measure cache warm-up, hit ratio, and performance under load rather than assuming that each additional PoP automatically produces steadier ABR.
Edge and Origin for South America
Edge nodes near viewers—and a regional origin with a correctly configured cache layer—can reduce first‑byte delay and cache-miss penalties when the measured paths are shorter. This can reduce long-haul fills, but reliability also depends on origin capacity, cacheability, and routing. Test health checks and traffic steering before expecting another LATAM PoP to take over, and use real-user telemetry to measure bitrate, rebuffering, and retention.
Melbicom’s CDN places PoPs in Buenos Aires, Fortaleza, Rio de Janeiro, Bogotá, Mexico City, and Lima. Dedicated servers in São Paulo are coming soon, so you can reserve planned origin capacity to pair with the existing CDN footprint.
We offer infrastructure freedom—a footprint of 21 Tier III/IV data centers, including São Paulo and Marseille coming soon, dedicated servers with high-bandwidth options up to 200 Gbps per server globally, and fully custom hardware configurations. You get deployment freedom (spin up what you want, where you need it), configuration freedom (tailor hardware and network scale), operational freedom (single-tenant, no lock-in), and experience freedom (direct control, simple onboarding, 24/7 support).
Be first to host in Brazil with Melbicom
Explore our dedicated-server plans for Brazil (servers) and global footprint (data centers and CDN), then share your traffic volumes and exact technical specs. We’ll shape a tailored origin-plus-edge offer as our Brazil capacity comes online—so you can be among the first to host in Brazil on special terms. Final server ports and availability will be confirmed in your quote.