
Month: November 2025
Blog
High-Performance Servers for Crypto Exchanges and Trading Platforms
Milliseconds and credibility determine the life or death of cryptocurrency exchanges. Matching engines need to respond to events almost in real time, APIs must broadcast massive quantities of market data, and the system must withstand demand peaks while staying online. It is not just a best‑effort web workload; it is an ever‑running financial system. High‑performance servers can support low‑latency execution, sustained high throughput, and resilience while giving teams operational control over security and compliance measures.
The size of the market is the reason why the bar continues to go up. CoinGecko’s 2025 annual report puts perpetual trading volume across the top 10 centralized perpetual exchanges at $86.2 trillion for the year. This measures trading value, not order-processing throughput; each exchange must benchmark its own order flow and latency.
Crypto Servers— 1000+ ready configurations — 21 Tier III & IV data centers incl. upcoming — 40 CDN PoPs · 6 continents |
 |
Low Latency in Crypto Trading
Low latency in crypto trading means controlling delay and variability across network round trips, gateway acknowledgments, order matching, and market-data delivery. Measure p50, p95, and p99 separately for each stage under peak load. An acknowledged order is not necessarily filled; fill timing also depends on order conditions and available liquidity.
Geographical distance and clean routing. Geography and routing affect network round-trip times. Placing exchange gateways near users can shorten the user-to-gateway path, while caching public assets at the edge shortens the asset-delivery path. Neither removes the propagation delay involved in reaching a fixed matching engine.
Compute and network stacks with low jitter. Garbage collection, CPU scheduling, interrupt handling, and network queues can add latency variation. Dedicated hardware removes contention from other tenants on the host, but application pauses and congestion still need measurement and tuning; hardware isolation alone does not guarantee deterministic execution.
Low‑latency trading servers. Fast CPU cores, local NVMe, and tunable NIC interrupts on dedicated servers give teams control over execution latency. Melbicom’s regional placement and BGP sessions support customer-managed ingress routing. Anycast selection follows routing policy rather than geographic distance alone; test failover timing.
Real‑time market data feeds. Low latency also requires efficient fan-out of order‑book deltas to subscribers. Melbicom offers per-server connectivity up to 200 Gbps and multi-provider transit; usable headroom still depends on message sizes, subscription counts, and processing limits. The CDN PoPs can carry cacheable public UI assets, snapshots, and historical files to offload origins, not accelerate authenticated order execution or live WebSocket feeds through caching.
How Do Servers Handle Trading Spikes?
Token listings, liquidations, or macro headlines can bring abrupt traffic bursts. On June 1, 2020, Coinbase recorded a fivefold traffic increase in four minutes that outpaced autoscaling and disrupted its website and mobile apps; API trading remained functional. The design response is multi-layered:
Provision for the peak, rather than the average. Size capacity against measured order submissions, cancellations, and market-data bursts. With dedicated servers, teams can tune cores, frequency, RAM, and NVMe layout for the hot path without contention from other tenants; achievable throughput depends on the engine and workload.
Scale horizontally under load. Stateless gateways and replicated market-data publishers distribute load across nodes. Partition matching workloads by market while preserving an authoritative order sequence for each book. Orchestration can use prepared spare nodes; physical server provisioning is not instantaneous.
Keep bandwidth slack. Both compute and egress can become bottlenecks. Melbicom provides up to 200 Gbps per server; load tests must confirm that applications, NICs, and downstream paths can handle message bursts without unacceptable queue buildup.
Exchange matching engine hosting. The engine benefits from high clocks and cache‑resident data structures, low‑latency NICs, and predictable storage‑flush paths. Specialized tuning—interrupt coalescing, user‑space networking stacks, and CPU pinning—is possible on dedicated servers; validate each change against the engine’s measured throughput and tail latency.
Designing for 24/7 Trading Uptime

Crypto doesn’t close. Outages interrupt trading, reduce fee revenue, and damage trust; their cost depends on the venue, duration, and market conditions. There are three pillars of uptime discipline:
- Facility resilience. Resilient power, cooling, and carrier diversity reduce infrastructure risks, but facility Tier status does not guarantee application uptime. Melbicom combines Tier III & IV DCs in Amsterdam and Tier III facilities in Los Angeles, Singapore, and Tokyo with on-site engineers for hardware maintenance.
- Redundant services and tested failover. Active‑active load balancers, clustered gateways, hot‑standby matching engines, and geo‑redundant databases reduce single points of failure. Test promotion, order-state consistency, and client reconnection rather than assuming a server failure will be invisible to users.
- Operational control. Dedicated servers and 24/7 support help teams coordinate maintenance. Rolling upgrades require healthy replicas, spare capacity, and tested failover; kernel patches and hardware work may still require individual servers to restart.
Security & Compliance: What Defines a Secure Crypto Exchange Infrastructure?
Compliance is inseparable from performance and security posture. Single-tenant servers provide hardware isolation, control over the OS/kernel, and controlled change, which can simplify auditing and hardening:
Secure crypto exchange infrastructure. Dedicated servers enable customer-managed host‑level controls: hardened baselines, a minimized attack surface, key storage, separately provisioned HSMs where required, and detailed logging. BGP sessions with BYOIP support stable service addressing and customer-defined routing policy; anycast and failover require appropriate configuration and testing.
Melbicom is certified to ISO/IEC 27001:2022, the information security management system (ISMS) standard. This supports the provider-control evidence available to an exchange, but does not establish the exchange’s regulatory compliance. Teams remain responsible for application controls, data residency decisions, and evidence of compliance.
Architecture Patterns That Matter the Most
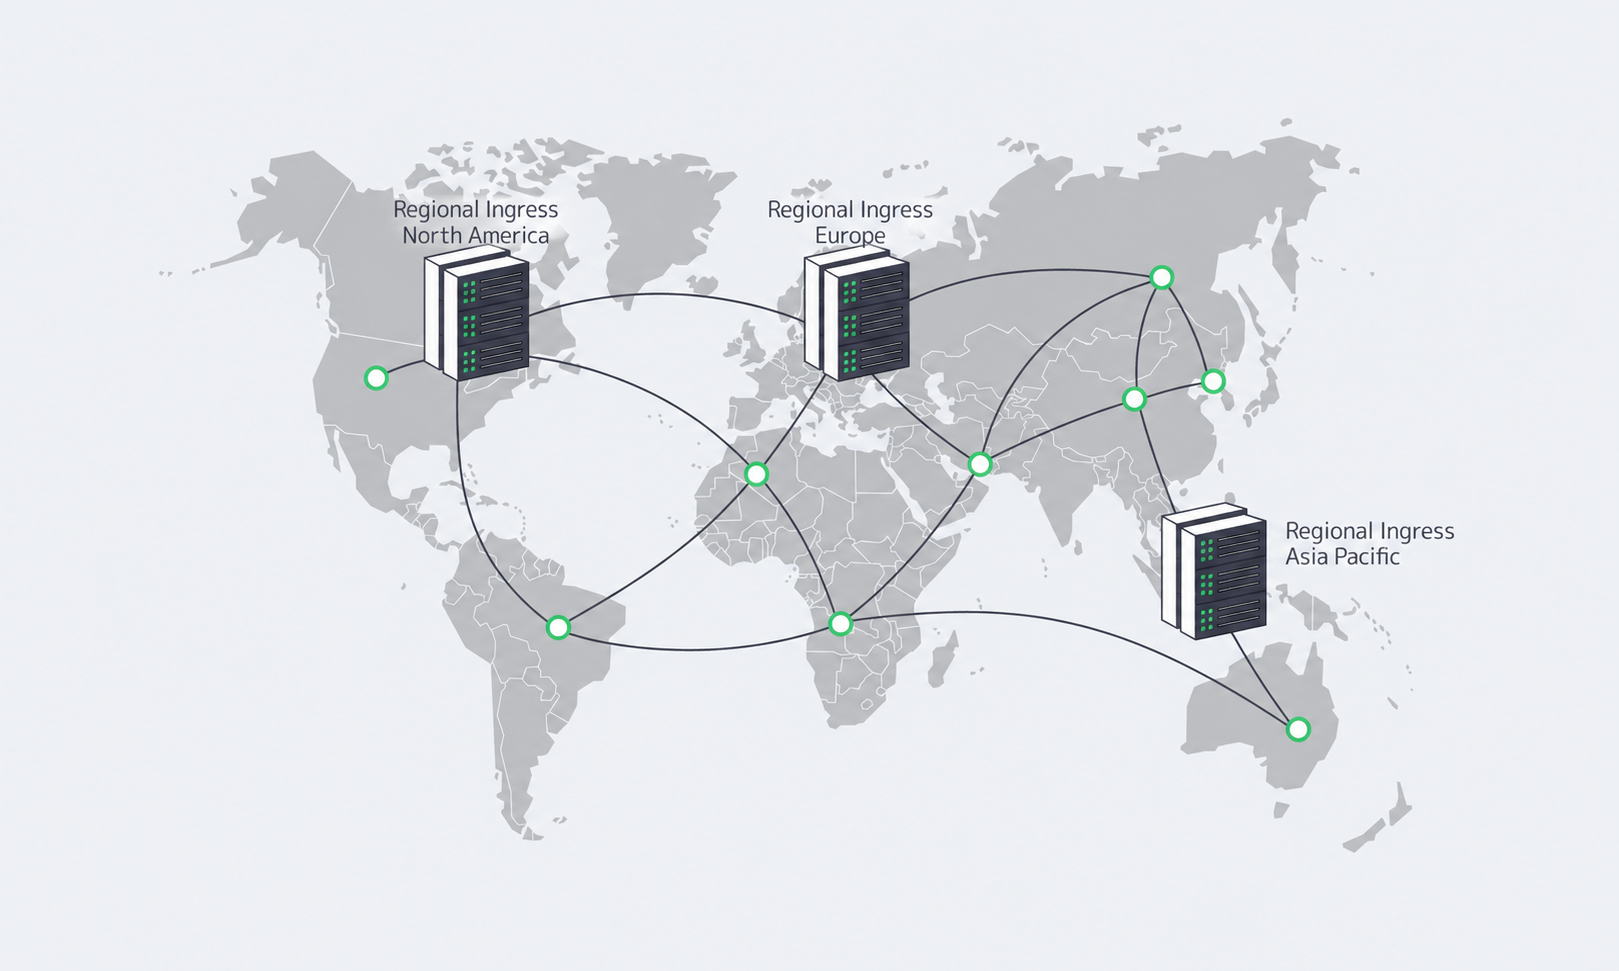
Modern architectures center on a plan that prioritizes predictable behavior and control.
Regional ingress + local bursts. Place gateways and read-heavy services near users while maintaining one authoritative order sequence per book, with coordinated replication and failover. Use active locations within Melbicom’s footprint of 21 data centers; São Paulo and Marseille are coming soon. Its 40 CDN PoPs across 35 countries deliver cacheable public content, while order handling and matching stay on tuned servers.
Data‑path separation. Isolate market‑data publishers and internal risk engines to reduce the chance that a burst in one plane starves another service of resources.
Network‑level control. Use BGP‑based anycast and regional failover to retain service addresses across sites. Test failure detection, route withdrawal and convergence, and client reconnection; a route change alone does not preserve application sessions or order state.
Challenges and how high‑performance dedicated servers answer them
| Exchange challenge | Impact if under‑engineered | Dedicated‑server answer |
|---|---|---|
| Uptime & maintenance | Lost fees and reputation; high-risk upgrade | Tier III/IV facilities, hot standby, and rolling upgrades support resilience; application failover must be tested. |
| Low‑latency execution | Unfair dispersion, slippage, dissatisfied market makers | Regional placement, fast CPUs, and single-tenant tuning; test tail latency under load. |
| Security & compliance | High breach/audit risk | Single-tenant isolation, OS control, and the provider’s ISO/IEC 27001:2022-certified ISMS support the exchange’s own controls. |
| Volume spikes & fan‑out | Queue surge, timeouts, interrupted data feeds | Clusters, up to 200 Gbps per server, tested headroom, and prepared spare nodes. |
What Capacity and Throughput Targets Should an Exchange Set?
Capacity targets for a crypto exchange should come from load tests of its own order flow, including submissions, cancellations, concurrent sessions, and market-data subscriptions. Set sustainable throughput at acceptable p95/p99 latency and verify recovery after bursts and node failure. Another venue’s engine capacity is not a dedicated-server benchmark.
In October 2025, Binance reported capacity of 1.4 million orders per second for its own matching engine. A pragmatic planning model:
- Size order intake for peak concurrent sessions and message rates, with headroom validated against bursts and node failure.
- Size matching so peak bursts clear without exceeding the defined tail-latency budget.
- Size market‑data egress for worst‑case deltas, not averages.
- Use local NVMe for write spikes and object storage for snapshots; test restores.
Melbicom offers 1000+ ready-to-go configurations with activation in around two hours. Provision spare capacity before expected peaks rather than relying on hardware activation during a sudden burst.
A Practical Deployment Checklist
- Pin your latency budget. Set separate p50/p95/p99 targets for network RTT, gateway acknowledgments, matching, and market-data delivery. Use regional ingress to shorten the gateway path; measure fills separately.
- Right‑size the engine. Benchmark high-clock CPUs, cache-resident order books, and local NVMe for logs and snapshots on single-tenant nodes.
- Design for the surge. Pre‑warm extra gateways and publishers for storm conditions, and size egress for those peaks. Target capacity above the mean.
- Separate planes. Isolate order entry, matching, market‑data, and administrative traffic so bulk delivery and maintenance do not contend with the hot path.
- Engineer for failure. Use active‑active load balancers, hot‑standby engines, rack‑ and region‑level replication, and tested cutovers.
- Control your routes. Configure the BGP session and BYOIP where appropriate for stable service addresses; test route selection, withdrawal, and client reconnection.
- Prove compliance. Map host, application, and operational controls to the exchange’s ISMS and applicable obligations. Keep evidence current; Melbicom’s ISO/IEC 27001:2022 certification covers the provider’s ISMS, not the exchange’s compliance.
Conclusion: Dedicated Servers Are the Backbone of Trustworthy Crypto Trading
Exchanges compete on speed, reliability, and stability. This demands infrastructure with low‑jitter latency, high sustained throughput, and measured resilience—not just in normal periods but in the exact minutes when markets are most volatile. Trading volumes provide market context; investment decisions should rest on the exchange’s own load tests, latency budgets, and recovery requirements.
Dedicated servers on a professionally operated global platform give teams architectural freedom: choose regions, match hardware to workloads, move cacheable content to the edge, and control routing policy. Combined with tested application design and operations, these capabilities help trading venues keep UIs responsive and services resilient.
Build a low‑latency crypto exchange
Provision tuned, single‑tenant hardware in key regions to cut jitter, handle volume spikes, and meet uptime targets for your trading platform.
Get expert support with your services
Blog

Brazil Dedicated Server Buying Guide: Performance & MSA
Brazil has a huge user base, and with today’s demands for latency‑sensitive apps, basing a dedicated server locally is no longer wishful thinking or a nice added bonus. In TIC Domicílios 2025, 85% of people aged 10 and older in Brazil were Internet users. In March 2026, IX.br reached 50 Tbps of aggregate traffic, including 32 Tbps in São Paulo (NIC.br). Hosting locally can avoid intercontinental backhaul, but the round-trip time depends on the actual user networks and routes.
Host in LATAM— Reserve servers in Brazil — 6 CDN PoPs in 5 countries — 21 Tier III & IV DCs, including Brazil |
 |
Brazil Dedicated Server Configuration
When purchasing a Brazil‑based dedicated server, there are four main considerations—CPU/GPU, storage, network, and terms/upgrade path—each of which needs to be validated against price‑to‑performance, redundancy, and DDoS exposure risks to make a wise infrastructure investment.
Matching CPU class to workloads
Forget the brand and pick the CPU required for the job. In other words, analyze your needs and the strengths:
| CPU Type | Key Strengths | Ideal For |
|---|---|---|
| AMD EPYC | Options with high core counts, substantial PCIe connectivity, and memory bandwidth. Compare the exact generation and model; throughput per watt and VM density depend on the complete platform and workload. | Virtualization (VM density), high‑concurrency SaaS, analytics, and mixed microservices. |
| Intel Xeon | A range of core counts and clock speeds, with acceleration features on supported processors and platforms. Check the exact model and software support rather than assuming every Xeon has the same capabilities or a performance advantage. | Latency‑sensitive or accelerator‑aware workloads such as real‑time APIs, certain inference, compression/crypto, etc. |
| AMD Ryzen | High-clock options for per-thread workloads. Core count, sustained performance, memory capacity, ECC support, and management features depend on the processor and motherboard. | Budget‑restricted game servers, small web/app nodes. Cases where single‑thread speed matters more than socket scale. |
CPU Guidance:
- If you have many containers/VMs to consolidate, compare core count, memory capacity and bandwidth, PCIe lanes, and licensing costs across EPYC and Xeon models.
- If your stack can use CPU acceleration, verify that the quoted processor, platform, and software support it. For lightly threaded work, benchmark sustained per-thread performance rather than choosing by brand or advertised turbo alone.
- If your work is lightly threaded and you need the cheapest dedicated server in Brazil, compare Ryzen options with other quoted configurations, including ECC support, remote management, and support terms—not just clock speed.
Do GPUs change unit economics?
GPUs can improve unit economics for supported training/inference, vision, transcoding, HPC, and rendering workloads. A GPU server is worthwhile when end-to-end benchmarks show a lower cost per completed task at the required latency. Include CPU preprocessing, GPU memory, data transfers, and software compatibility in the comparison. Without GPU-eligible work, the additional cost is unnecessary. For later upgrades, confirm compatible PCIe slots, chassis space, power/cooling, hardware availability, and any downtime or migration requirements.
Storage tiers: NVMe vs. SATA vs. HDD
Hot data can benefit from NVMe when storage I/O is the bottleneck. SATA SSDs typically top out near 550 MB/s (0.55 GB/s), while PCIe NVMe drives can be capable of delivering substantially higher sequential throughput. Actual throughput, IOPS, and latency depend on the drive, queue depth, and read/write mix; protocol latency is not end-to-end application latency. Check endurance and power-loss protection as well as speed. SATA SSDs or HDDs suit cold tiers and backups when access and restore needs allow.
Port Speed: 1/10/100/200 Gbps
Size a Brazil dedicated server port for measured peak traffic, response-time targets, and failover headroom—not monthly transfer alone. The 1–200 Gbps comparison below is theoretical and global, not a Brazil availability promise. Confirm the final São Paulo port, traffic allowance, and upgrade terms in your quote.
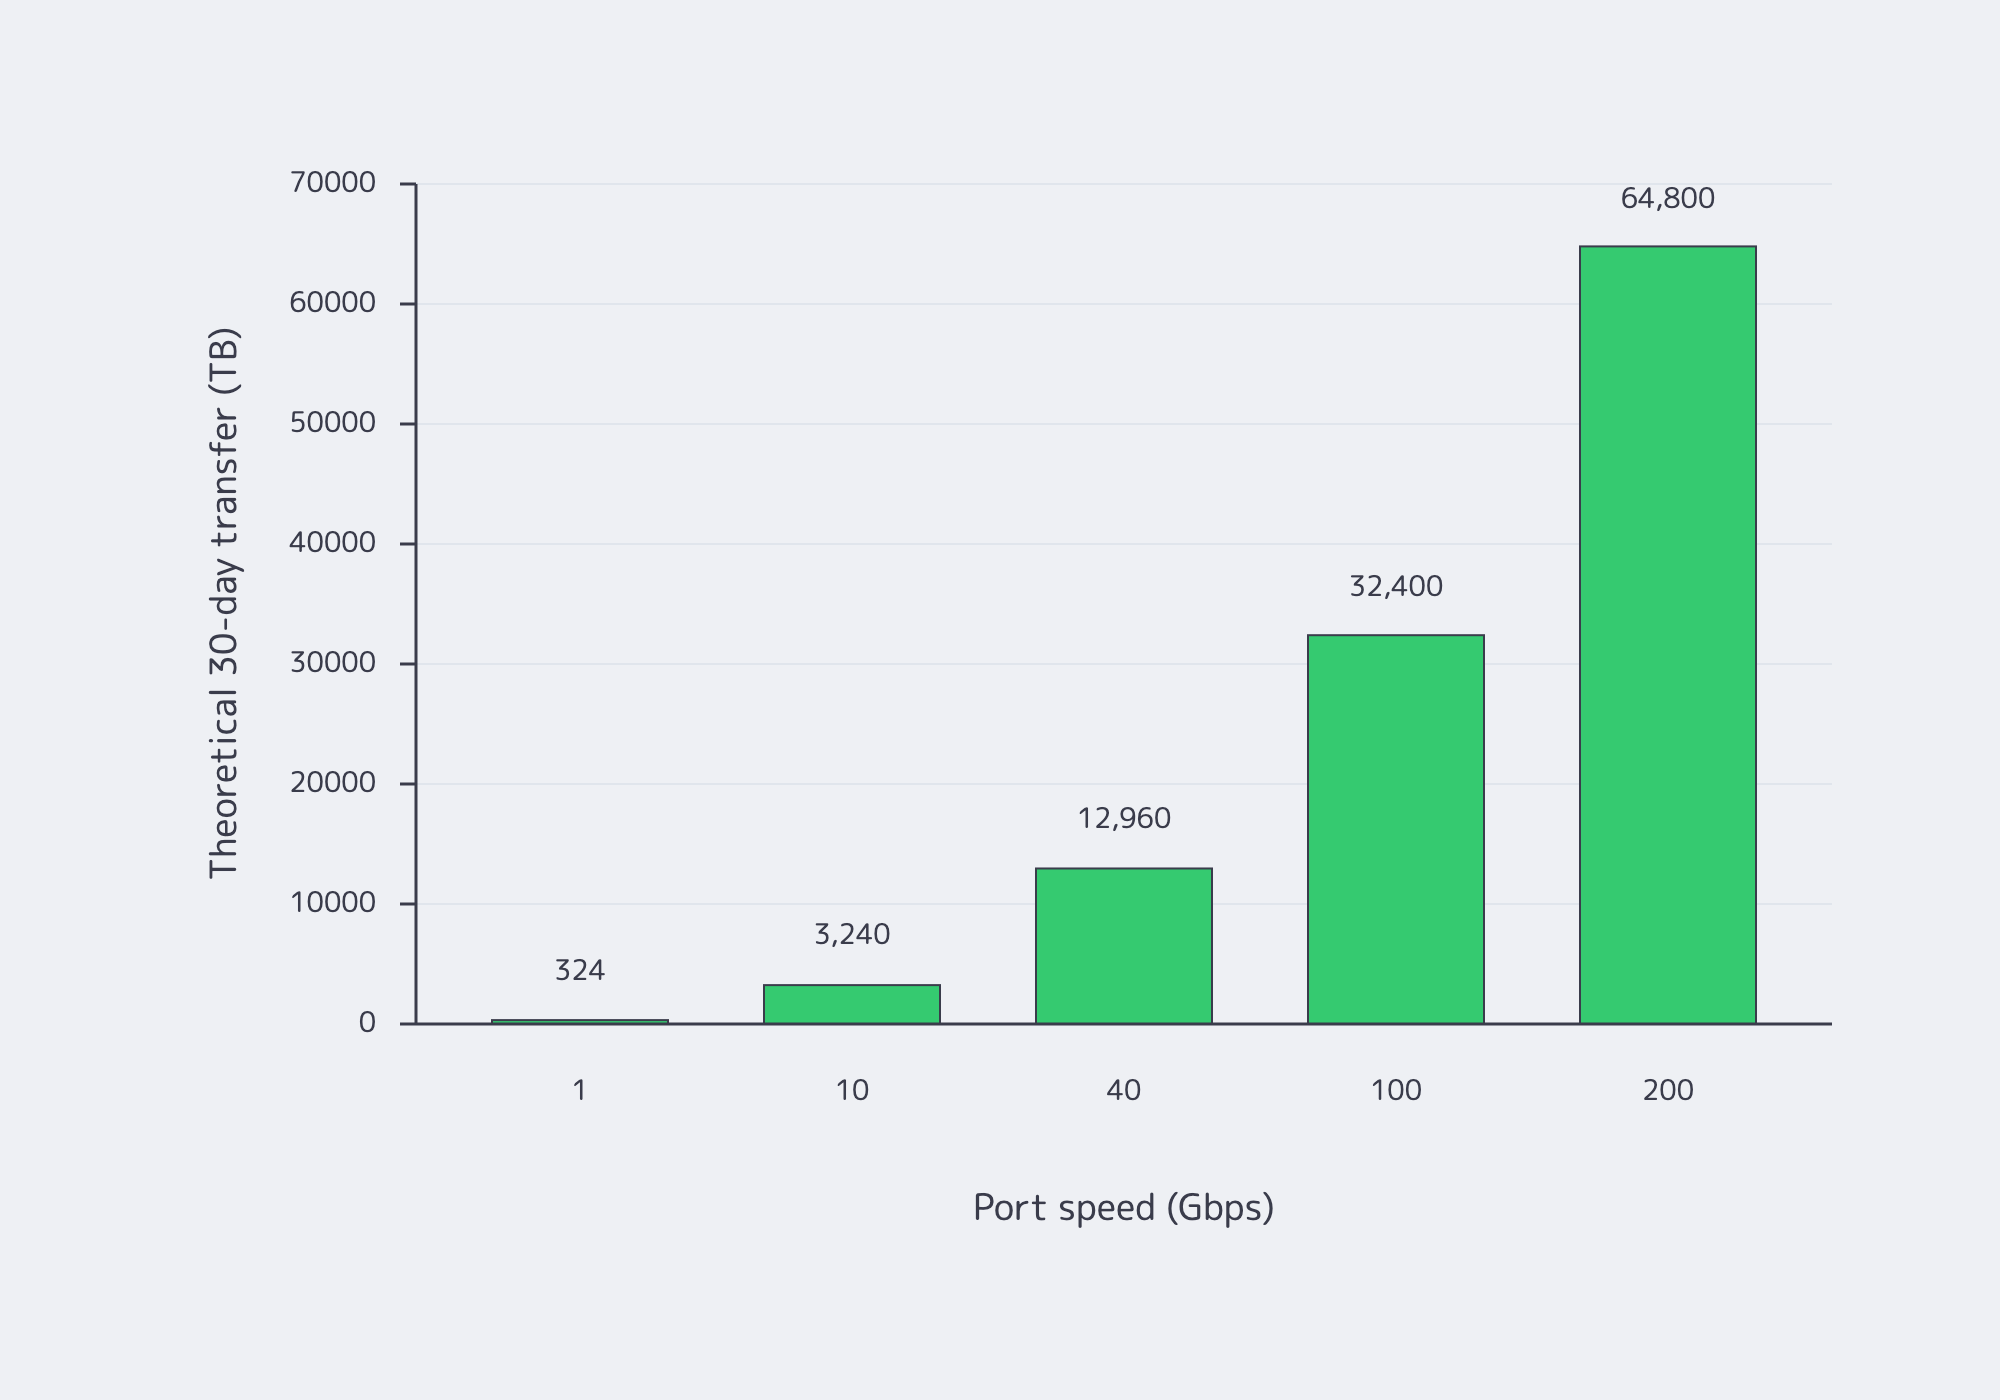
Monthly transfer matters for billing, but port sizing should also account for peaks. Use the following as starting points to test, not universal minimums:
- 1 Gbps can support moderate traffic and control-plane workloads when measured peaks and failover traffic fit within the available capacity.
- 10 Gbps is a candidate for busier origins, not a default minimum. Validate sustained throughput, burst duration, and headroom under representative load.
- 100–200 Gbps can suit high-volume streaming or file distribution when measurements justify it. Seeding a CDN does not by itself require this range; cache behavior and concurrent origin fetches determine demand.
Unmetered vs. metered: Compare the port rate, committed capacity, included transfer, overage prices, and any applicable usage restrictions. Unmetered service can improve cost predictability, but it does not automatically provide extra burst capacity. Metered service may cost less when transfer remains within its allowance. Use representative traffic and growth scenarios to compare total cost.
Quality routing: São Paulo’s IX.br scale can support efficient local delivery with suitable peering. Test provider IPs, traceroutes, round-trip times, and packet loss from the networks your users actually use, and confirm uplink diversity. NIC.br reported 39 metropolitan areas and a 50 Tbps aggregate peak in March 2026; exchange size alone does not guarantee a particular customer route.
Brazil Deploy Guide— Avoid costly mistakes — Real RTT & backbone insights — Architecture playbook for LATAM |
 |
Price‑to‑Performance and Resilience
For a dedicated server hosted in Brazil, you need a sensible evaluation worksheet:
- CPU class vs. utilization: Compare cost per completed task and p99 latency at representative load. The 2023 CHPC benchmarks compare specific Genoa and Sapphire Rapids configurations; use them as historical workload comparisons, not a ranking of current models or a utilization-based buying rule. If a few threads dominate latency, test sustained per-thread performance and scheduler settings.
- Storage that improves UX: Prioritize NVMe where storage latency or throughput limits databases, search indexes, or write-heavy services. Size memory and caches for the working set, and use SATA/HDD where measured access, endurance, and recovery requirements allow.
- Bandwidth that changes UX: Average utilization alone does not establish port saturation. Check short-lived peaks, queueing, packet loss, and failover headroom before increasing the port or commit. For regional delivery, place an origin in São Paulo when appropriate and use Melbicom’s CDN in Fortaleza, Rio de Janeiro, Buenos Aires, Bogotá, Lima, and Mexico City. São Paulo remains the upcoming server location, not a current Melbicom CDN PoP.
- DDoS risk and coverage: NETSCOUT’s ATLAS telemetry recorded 470,677 DDoS attacks in Brazil during July–December 2025 (report); this is an observed dataset, not a count of every attack nationwide. Evaluate exposed services, mitigation scope, activation procedures, incident contacts, and charges. Do not assume that protection is included in a Brazil server quote.
Which Contract Terms Matter the Most?
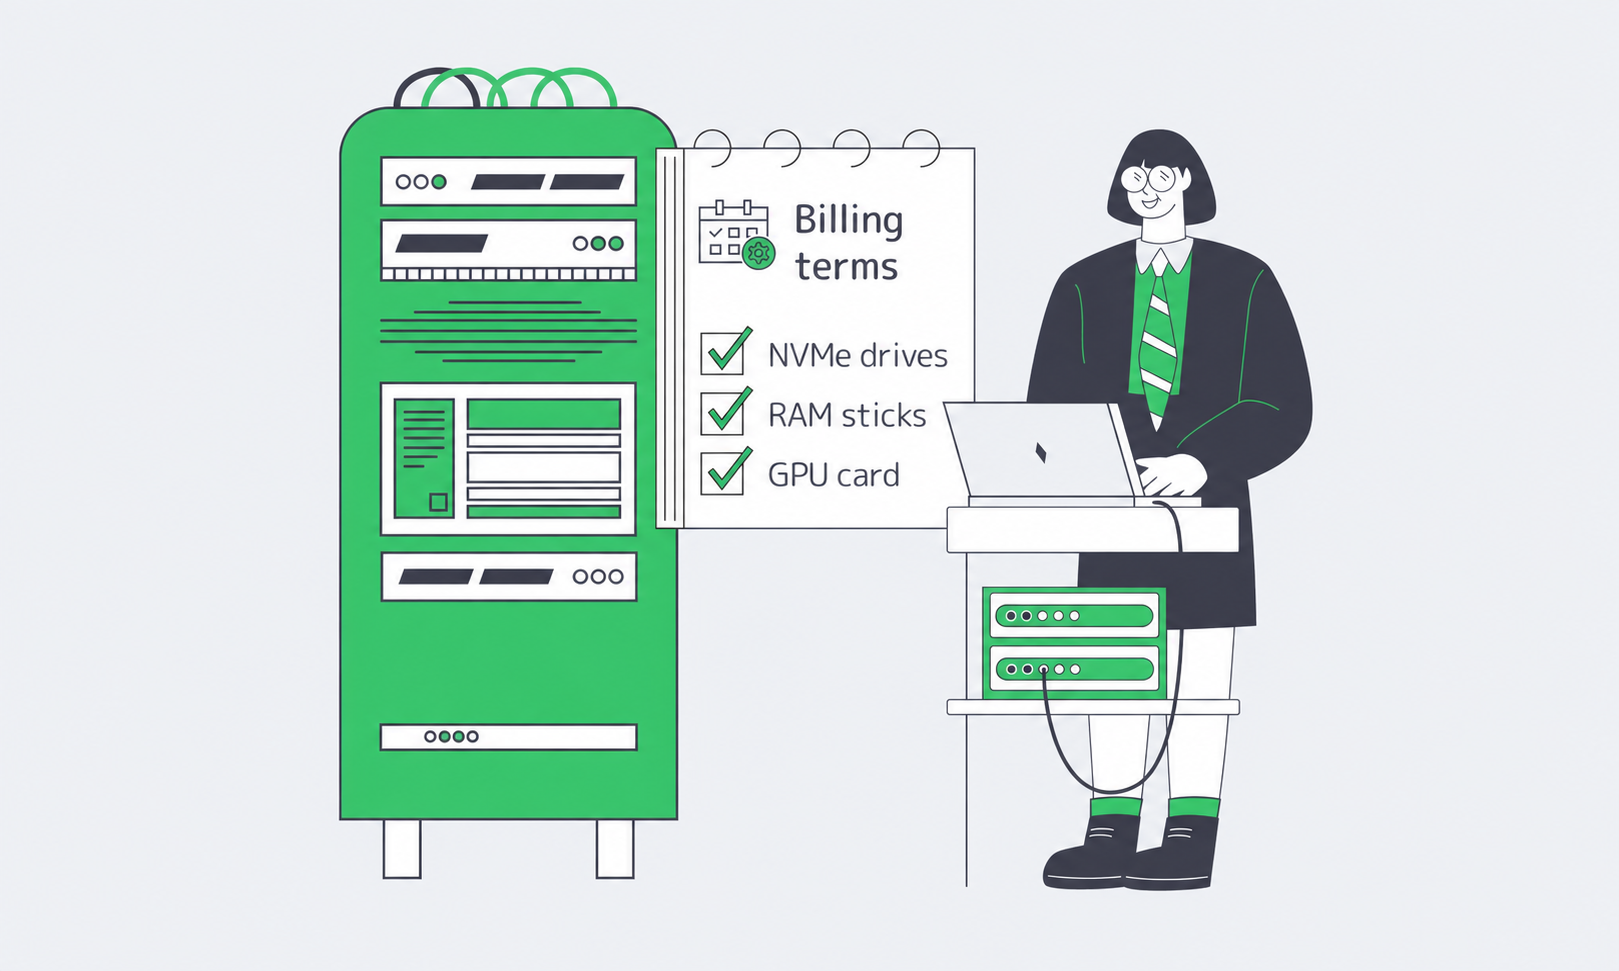
Flexible MSA, clear billing terms. When entering new territory, it’s worth comparing shorter commitments and straightforward change orders. Monthly billing does not by itself establish a monthly MSA: check the minimum term, renewal, cancellation notice, refund conditions, and separate terms for licenses or additional equipment.
Speed to capacity. Confirm stock, hardware allocation, and a deployment date in the quote. API and panel access can simplify server management, but they do not eliminate procurement or physical installation lead times. São Paulo remains a preorder location.
Scale‑up and scale‑out. Confirm the process for adding RAM/NVMe/GPU, increasing port capacity, and adding nodes. Upgrades may require downtime or migration; identical components across regions should not be assumed. Melbicom can discuss high‑bandwidth Brazil configurations and compatible regional deployments, with the hardware, port, timing, and upgrade path agreed in the quote.
How Brazil Hosting Affects Performance
The user base in Brazil is large and connections are in place, but intercontinental round trips add propagation delay. An origin in São Paulo can avoid that backhaul for Brazilian users; the improvement depends on both endpoints, routing, access networks, and application behavior. Measure representative round-trip and application response times under both normal and peak load.
The ideal playbook:
Use these as workload-dependent starting points, not fixed bills of materials. Confirm Brazil hardware and port availability in the quote; the higher port tiers also describe global architecture options.
- For transactional APIs and low‑latency trading: Benchmark per-thread and p99 performance on the available CPUs, use NVMe where storage is a bottleneck, and evaluate a 10–40 Gbps port only when traffic warrants it; a smaller port may suffice. Add a CDN for cacheable assets and a warm standby where recovery requirements justify it.
- SaaS with many concurrent sessions: Compare EPYC and Xeon builds for memory capacity, VM density, and cost at target load; use NVMe for I/O-sensitive data. Evaluate 10–40 Gbps at measured peaks; add CDN caching and standby capacity as needed.
- Streaming / file distribution: Benchmark the complete EPYC or Xeon configuration and storage/cache tier. Global 40–200 Gbps origin options may suit heavy transfer, but are not a Brazil delivery promise. Size origin capacity after evaluating CDN cache hits, misses, and concurrent fetches; isolate critical traffic.
- ML inference/vision: Compare supported CPU acceleration with discrete GPUs using the actual model, precision, batch size, and latency target. Size scratch storage and the port for measured data movement; confirm GPU availability and expansion requirements before purchase.
Tip: If you’re weighing a cheap dedicated server in Brazil, ensure it still checks the boxes that affect UX the most: modern disks, a realistic port, and access to a South American CDN.
Key Takeaways You Can Act On
- Put servers where users are: Brazil’s interconnection scale makes local origin hosting worth testing for responsiveness. Validate audience-specific routes and application response times before choosing a location.
- Match CPUs to code paths: Compare exact processor generations, memory platforms, software support, and total cost. No CPU family is the automatic winner for concurrency, clock speed, or acceleration.
- Choose storage for the workload: SATA SSD throughput typically caps near 550 MB/s; faster NVMe storage is most useful when I/O limits performance. Validate drive-specific latency, IOPS, endurance, and recovery needs.
- Buy the port you need for peaks: Compare 10 Gbps with both smaller and larger options. Global availability of ports up to 200 Gbps does not replace confirmation of the final Brazil port and transfer terms.
- Evaluate DDoS exposure: Match mitigation requirements to exposed services and confirm the provider’s scope, procedures, and terms; a national attack statistic is not a service guarantee.
- Keep terms agile: Compare billing, cancellation, deployment dates, and upgrade or migration requirements—not just the initial discount.
Thinking About Hosting in Brazil with Us?

Melbicom can help you finalize this blueprint as we are opening priority access for teams preparing Brazil rollouts: tell us your traffic profiles, exact technical specifications (CPU/GPU preferences, NVMe tiers, port targets, redundancy/DDoS posture), and timelines, and we’ll shape a tailored offer and deployment plan using our network and South American CDN. São Paulo dedicated servers remain available for preorder, with hardware, final ports, mitigation scope, and deployment timing confirmed in your quote. Contact us.
Why Melbicom
What sets Melbicom apart is infrastructure freedom. We operate our own network and deliver high‑bandwidth solutions globally, with up to 200 Gbps per server, custom hardware options, and an international, remote‑first team built for speed. In practice that means deployment freedom (choose a server location that fits your workload), configuration freedom (specify CPU/GPU, NVMe tiers, and ports for your quote), operational freedom (single-tenant dedicated servers with administrative control), and experience freedom (clean onboarding and transparent control). Share your expected volumes and failure domains now; we’ll review routes, right-size capacity, and agree on the available upgrade path before your Brazil deployment.
Plan your Brazil dedicated server rollout
Tell us your CPU/GPU, NVMe, and port needs. We’ll review routes and capacity for your São Paulo preorder, discuss CDN options, and confirm deployment timing, mitigation scope, and service terms in the quote.
Get expert support with your services
Blog

Secure & Low-Latency Infrastructure for DeFi Platforms
Stablecoin rails and decentralized exchanges have turned into always‑on, high‑throughput markets. In the past year alone, stablecoins processed more than $27.6 trillion of on‑chain transactions—a milestone that eclipsed card‑network volumes. In October, DEX volume set a record above $613B as market share shifted toward on‑chain execution. In this environment, infrastructure becomes strategy: milliseconds determine if liquidations trigger on time, arbitrage captures spread, and user trust holds through volatility.
This article focuses on the two levers that consistently move the needle for DeFi operators: ultra‑low latency and robust security. We’ll show how dedicated, high‑performance servers—deployed across geographically distributed locations and paired with hardware‑backed key protection—deliver that edge.
Choose Melbicom— 1000+ ready-to-go servers — 21 global Tier IV & III data centers — 40 PoP CDN across 6 continents |
|
Why Does Ultra‑Low Latency Matter in DeFi?
Speed is an economic value. When slots or blocks tick quickly—Solana slots are ~400–600 ms—even modest network delays can mean missing a block window and the price that came with it. The same principle applies across L2s and parallelized chains whose finality targets are measured in sub‑seconds.
Three latency domains usually dominate:
- Mempool & propagation. If your transactions or oracle updates hit builders/validators after competitors’, your fill quality degrades. Private order flow paths and fast peers materially reduce that race (more on this below).
- User‑facing APIs. A few dozen extra ms. between a trader and your RPC/API endpoint can push them past a price move. For latency‑sensitive flows, in‑region endpoints and short network paths are the difference between taking and missing liquidity.
- Off‑chain components. Indexers, sequencers, matching engines, risk services—anything off‑chain behaves like a low‑jitter trading system. Here, exclusive access to CPUs, memory, and NICs matters. Public, shared endpoints routinely show p99 latencies in the 50–500 ms range, while dedicated pipelines land in the 5–50 ms band; colocation and private links push lower still.
Bottom line: every hop and every shared layer adds variance. Dedicated servers placed close to users and chain nodes, on clean network paths, cut that variance to size.
Designing Low‑Latency DeFi Hosting

The architecture is surprisingly consistent across high‑performing teams:
Geographically distributed nodes/servers. Place RPC, validators, indexers, and app backends in multiple strategic regions so users and services reach a nearby endpoint. This minimizes round‑trips and smooths block/gossip propagation. With Melbicom’s 21 Tier III/IV data centers on a 14+ Tbps backbone and 40 CDN PoPs, teams place infrastructure precisely where latency is lowest and failover is clean. Melbicom offers ports up to 200 Gbps per server, which keeps spikes from queuing.
Direct, high‑quality connectivity. Keep routes short and stable. In practice that means peering and BGP sessions to hold constant IPs (useful for RPC/validator endpoints), and to steer traffic over better paths. Melbicom provides free BGP sessions on dedicated servers with BYOIP and community support so you can engineer for speed and consistency.
Edge acceleration where it helps. Wallet assets, ABIs, snapshots, and UI bundles shouldn’t traverse oceans on every request. Push reads to the edge via a 40 PoP CDN, keep writes local, and right‑size origins to back hot regions.
Run your own nodes for critical paths. Public RPCs are convenient but multi‑tenant queues add jitter. Dedicated single‑tenant nodes eliminate shared contention and rate limits, unlocking deterministic fetch/submit times. Melbicom’s Web3 page details dedicated RPC for dApps and NVMe tiers for archival/full nodes with unmetered bandwidth—practical choices that shorten sync windows and keep p95 latency flat.
Hardening a Secure DeFi Platform Infrastructure
Performance without protection is a liability. Modern stacks are converging on two complementary controls:
1) Hardware‑backed key custody. Hardware Security Modules (HSMs) generate and store keys in tamper‑resistant hardware; keys never appear in server memory. Secure enclaves (confidential computing) restrict access to decrypted key material to attested code only—so even a root‑level OS compromise can’t exfiltrate secrets. This is now standard practice at institutional custody and increasingly common for DeFi admin/oracle keys. The effect is simple: keys stay out of reach, signatures remain valid, and governance or bridge operations become dramatically safer.
2) Private transaction paths to limit MEV exposure. Public mempools leak intent; searchers reorder and sandwich transactions. Private RPCs and relays route transactions straight to builders/validators, bypassing the public mempool and reducing front‑running risk. Wallets and dApps widely support these routes today. For sensitive flows—liquidations, large swaps, sequencer inputs—this is now table stakes.
Resilience is security, too. Fault‑tolerant DeFi platforms spread critical services across regions and vendors so no single facility or network interruption halts the system. Melbicom operates Tier III/IV facilities with per‑server networking up to 200 Gbps across EU/US/Asia, plus 24/7 support and fast hardware replacement—practical ingredients for active‑active designs and rolling upgrades without downtime.
Dedicated Servers for DeFi Performance: Where Does the Edge Come From?

Exclusive resources, predictable timing. Dedicated servers remove noisy‑neighbor effects. CPU cycles, RAM bandwidth, NVMe IOPS, and NIC queues are yours alone—critical for consistent block ingestion, indexing, and order handling. Shared instances might average fine; tail latency is what breaks liquidations and market‑data pipelines.
Bandwidth and topology you can engineer. With ports up to 200 Gbps and guaranteed throughput, you scale horizontally without egress shocks or surprise throttles. Add BGP with BYOIP to keep endpoint IPs stable through maintenance and region changes.
Full‑stack control. You choose OS hardening, kernel parameters, I/O schedulers, and monitoring. You decide how your enclaves and HSMs integrate. You pin inter‑DC replication on private links. That control translates into faster incident response and easier audits.
Global footprint, local latency. Melbicom lists 21 data centers across key hubs with a 14+ Tbps backbone and 40 CDN PoPs, so you can put validators, RPC, and app backends near users and chain peers rather than pulling everything through a single region.
DeFi infrastructure challenges and solutions
| DeFi infrastructure challenge | Risk if unaddressed | Dedicated‑server solution |
|---|---|---|
| High network latency to users/validators | Slippage, missed blocks; competitors see/act first | Geo‑distributed nodes/servers with BGP‑steered routing and 1–200 Gbps ports reduce hops and queuing. |
| Shared/public RPC bottlenecks | Rate limits, multi‑tenant p99 spikes | Single‑tenant RPC and local full nodes on exclusive hardware; deterministic throughput. |
| Single‑region dependency | Regional failure = global outage | Active‑active regions in Tier III/IV DCs with fast failover and steady IPs via BGP/BYOIP. |
| Private key exposure | Irreversible loss of funds/governance | HSMs + secure enclaves isolate keys and signing; enclaves run attested code only. |
| MEV front‑running | Worse execution; failed transactions | Private RPC/relays send orderflow directly to builders, bypassing the public mempool. |
What Should Teams Actually Build?
- Prioritize “nearby” everything. Place RPC/validators/indexers in the same region as your users and counterparties; keep propagation paths short.
- Adopt private orderflow paths. Route sensitive transactions through private RPC/relays to curb MEV exposure and reduce revert waste.
- Use dedicated servers for deterministic performance. Aim for 5–50 ms end‑to‑end service targets on critical paths; eliminate multi‑tenant p99 tails.
- Make hardware do security work. Store keys in HSMs; run signers in secure enclaves; restrict management to isolated networks.
- Engineer for failure. Active‑active multi‑region, BGP for sticky IPs, private inter‑DC links for state replication, and 24/7 ops so failovers are boring.
Why This All Matters Right Now

Block production windows are short—hundreds of milliseconds on some chains—and on‑chain volume is rising. In practical terms, latency and security are revenue, not line items. Teams that deploy geographically distributed nodes/servers on dedicated hardware, and that seal keys in hardware, consistently ship faster execution and fewer surprises. The best DeFi platforms today feel instant and stay online through chaos because their infrastructure is designed to do exactly that.
For operators, the path is clear: own the critical path—where your latency and trust originate. That means single‑tenant servers close to users and chain peers, private orderflow routes, and hardware‑backed key protection.
Deploy low‑latency DeFi hosting
Launch dedicated servers with ports up to 200 Gbps, BGP sessions, and Tier III/IV data centers to cut latency and boost resilience for nodes, RPC, and backends.
Get expert support with your services
Blog

How Dedicated Servers Power Seamless Live Streaming
Live streaming at scale is ruthless on infrastructure. Millions of viewers can arrive within seconds; every additional millisecond of delay compounds into startup lag, buffer underruns, and churn. Decades of QoE research show the audience has little patience: abandonment begins when startup delay exceeds ~2 seconds, rising ~5.8% for each additional second—a brutal slope for real‑time broadcasts.
This piece examines how dedicated server infrastructure delivers seamless live streaming for events and real‑time broadcasts: why single‑tenant performance matters under concurrency stress, how edge computing and a CDN pull content closer to viewers to minimize lag, and which failover patterns keep streams online through faults.
Choose Melbicom— 1000+ ready-to-go servers — 21 global Tier IV & III data centers — 40 PoP CDN across 6 continents |
|
Why Is “Seamless” Live Streaming So Hard?
Concurrency and bandwidth. Peaks are spiky and simultaneous. If 10,000 viewers watch a 4K ladder at ~20 Mbps, origin egress must sustain ~200 Gbps instantly. At a million viewers, that arithmetic hits tens of Tbps—well beyond any single facility’s comfort zone. And the payloads are heavy: Netflix’s own guidance pegs 4K at ~7 GB per hour per viewer—petabytes evaporate quickly at audience scale.
Physics and protocol trade‑offs. The farther a viewer is from origin, the larger the buffer needed to ride out jitter. Traditional HLS/DASH favored stability over speed; newer modes (LL‑HLS/LL‑DASH) trade smaller chunks and partial segment delivery for 2–5 second end‑to‑end delays—only if the network and servers keep up.
Viewer intolerance for interruptions. The research is unambiguous: seconds of startup or rebuffering drive measurable abandonment and revenue loss. That’s why platforms that win on live events are the ones that engineer for steady latency under unpredictable demand, not just average throughput.
What Makes a Live Streaming Dedicated Server the Right Foundation?
Dedicated servers give streaming teams exclusive, predictable performance—no hypervisor jitter, no “noisy neighbors,” and full control of CPU, RAM, NIC queues, storage layout, and kernel networking. When tuned for live media (fast NVMe for segments and manifests; large socket buffers; modern congestion control), dedicated hosts push line‑rate 10/40/100+ Gbps consistently, which is the difference between a stable 2‑sec ladder and a stuttering one at peak.
Melbicom’s platform illustrates the point: 1000+ ready‑to‑go servers across 21 global data centers (Tier III/IV) enable precise right‑sizing and regional placement; per‑server bandwidth options reach up to 200 Gbps in select sites; and free 24/7 support plus component replacement within 4 hours keep incidents from turning into outages.
Cost and predictability also tilt in favor of dedicated as you scale: flat‑priced ports (rather than per‑GB egress) and the ability to drive them at capacity let teams provision for the peak rather than the median—critical when a broadcast goes viral.
Comparison at a glance
| Key factor | Dedicated server infrastructure for streaming | Cloud VM infrastructure for streaming |
|---|---|---|
| Performance under load | Exclusive hardware; stable CPU/I/O and line‑rate 10–200 Gbps per server when available. | Multi‑tenant variability; hypervisor overhead can add jitter under peak. |
| Latency & routing | Full control of stack, peering, and placement; regions chosen to minimize RTT to viewers. | Less control over routing; regions may not align with audience clusters. |
| Customization | Tune OS, NICs, storage, and encoders; add GPUs for real‑time transcode. | Constrained instance shapes; less low‑level tuning; GPU/storage premiums. |
Why it matters: LL‑HLS/LL‑DASH only hold low single‑digit‑second latency at scale when origin and mid‑tier nodes can serve small segments immediately and the upstream routes stay clean. That favors single‑tenant boxes on fast ports in the right metros.
How Does Edge Computing Cut Latency?
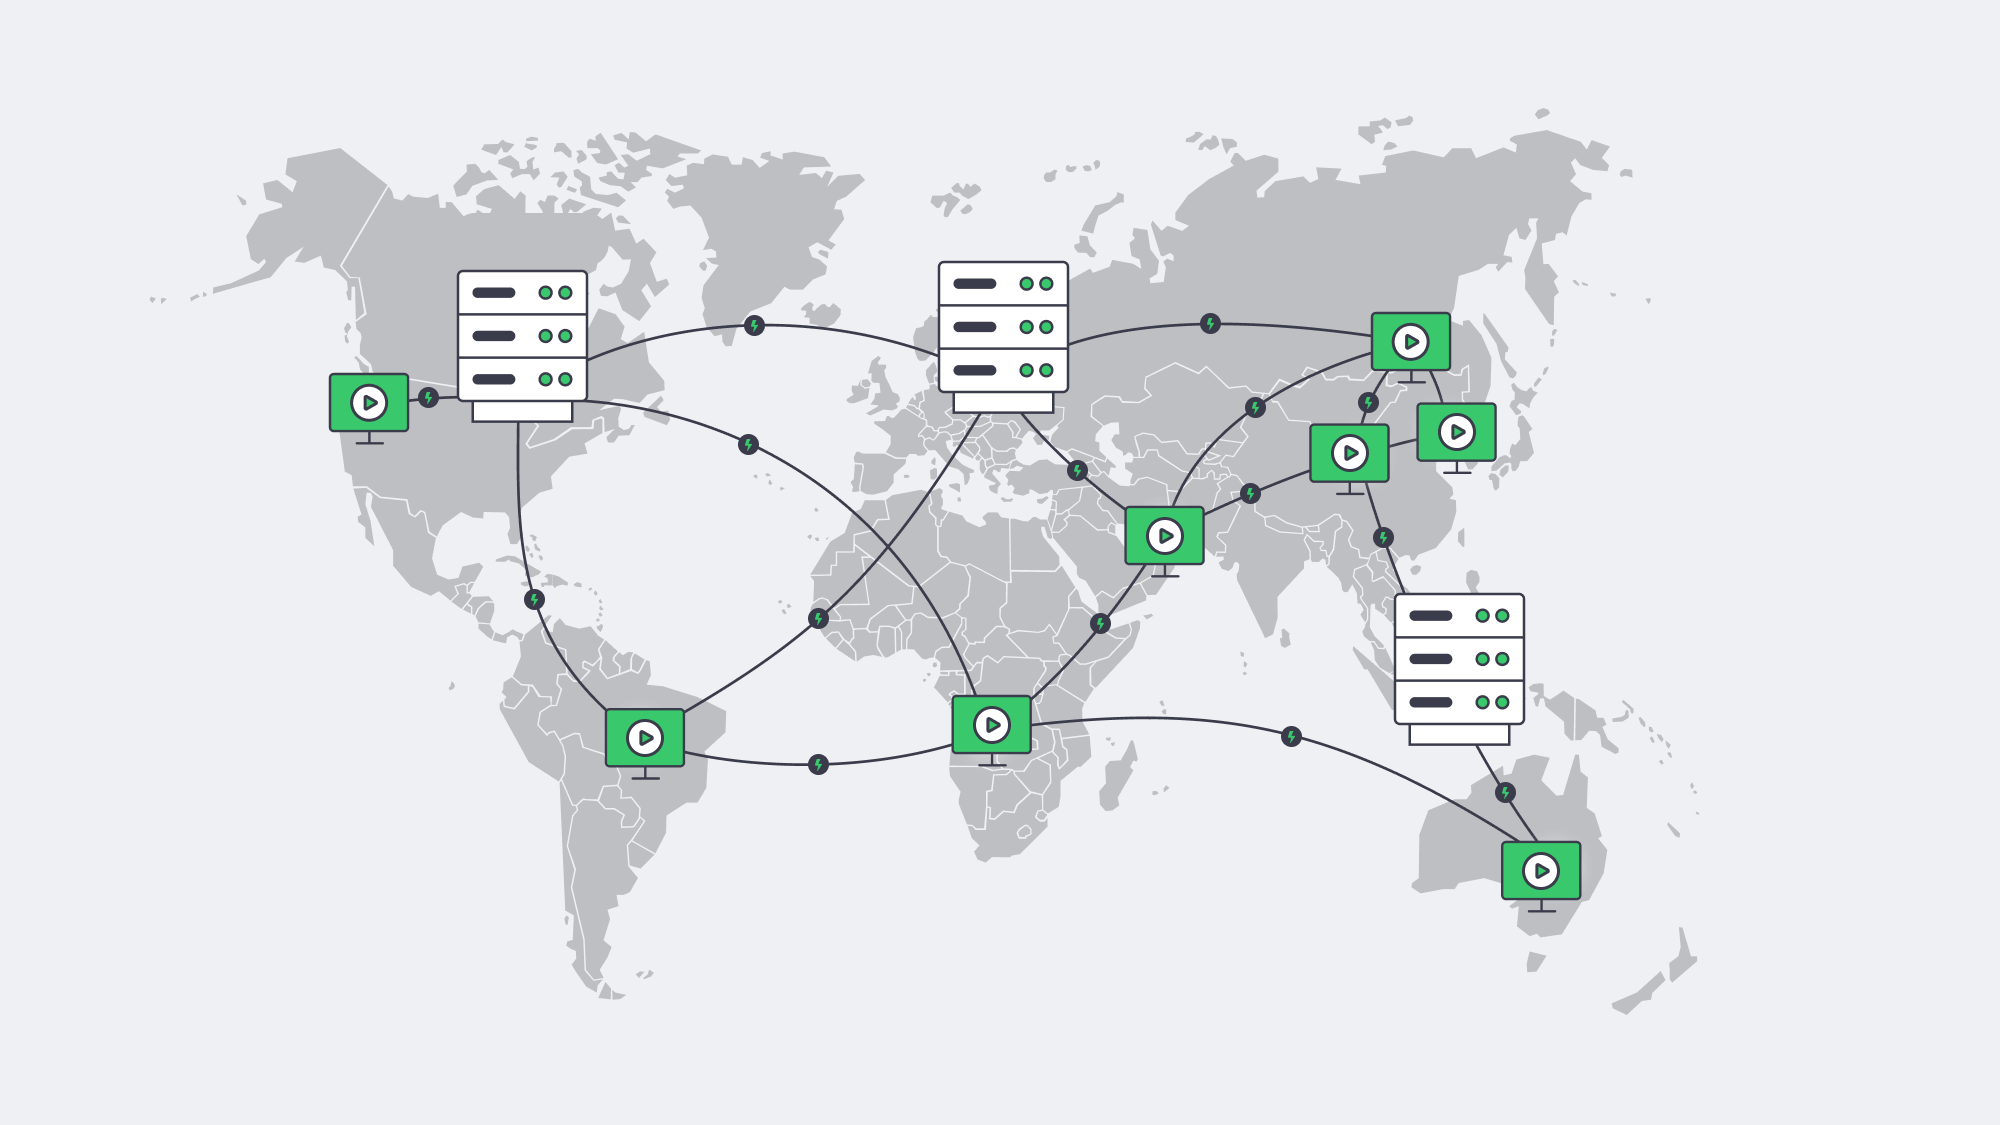
The single most reliable way to reduce live delay and buffering is to shorten the distance between content and viewer. A CDN/edge layer fetches each segment once from origin, then serves it from nearby points of presence—collapsing round‑trip time and stabilizing last‑mile variability. Industry analyses attribute step‑function latency gains to pushing compute and cache deeper into the network; the architectural goal is simple: keep media within a handful of hops of the player.
Melbicom’s CDN spans 40 PoPs across 35 countries and 6 continents, with HTTP/2, TLS 1.3, and video delivery features (HLS/DASH). In practice, that lets teams park origins on dedicated hosts in a few strategic metros and let the edge take the fan‑out load—especially during flash crowds.
Low‑latency protocols amplify the benefit. LL‑HLS relies on small parts and chunked transfer; when those parts originate from an edge 15–30 ms away instead of a core 150–300 ms away, live delay stays in budget and rebuffer risk collapses. Apple’s LL‑HLS design notes and independent guidance consistently place live latency targets around 2–5 seconds for scalable HTTP‑based delivery—achievable only with strong edge proximity.
Where should the best streaming server sit?
- Place dedicated origins in the same continent (often the same country) as your largest live cohorts; use secondary origins where you see sustained daily concurrency.
- Put a CDN/edge in front; prefer footprints with PoPs near your audience (and peering with their ISPs).
- Keep origins lean: hot segments on NVMe; manifest/segment I/O localized; avoid mixing heavy analytics or ad‑decision engines on the same hosts.
Melbicom’s model—21 data centers for origins and a 40 PoP CDN—is designed for that split‑brain: origins where compute belongs, distribution where distance matters.
Keeping Streams Online When Things Break
No single point of failure—that’s the operational mantra for live. The core patterns:
- Multi‑origin, multi‑region. Two or more independent origin clusters pull the same live feed and package segments concurrently. A CDN config lists both; on health‑check failure, fetches shift automatically.
- Smart routing. DNS steering or BGP anycast (where appropriate) places viewers at the nearest healthy entry point; a failed site simply stops announcing and traffic drains to the next‑closest.
- Encoder redundancy. Dual ingest pipelines (primary/backup) keep the feed flowing even if one encoder or network path fails.
- Rapid repair and human cover. When a host does fail, component replacement within 4 hours and 24/7 on‑call engineers mean the cluster’s redundancy window is short—and viewers never notice. Melbicom documents both practices for streaming workloads.
Testing matters: schedule controlled “chaos” during low‑stakes windows—kill an origin, yank a transit, drop an encoder—until failover is boring. That’s the only path to confidence on show day.
Low Latency and Stability During Live Events
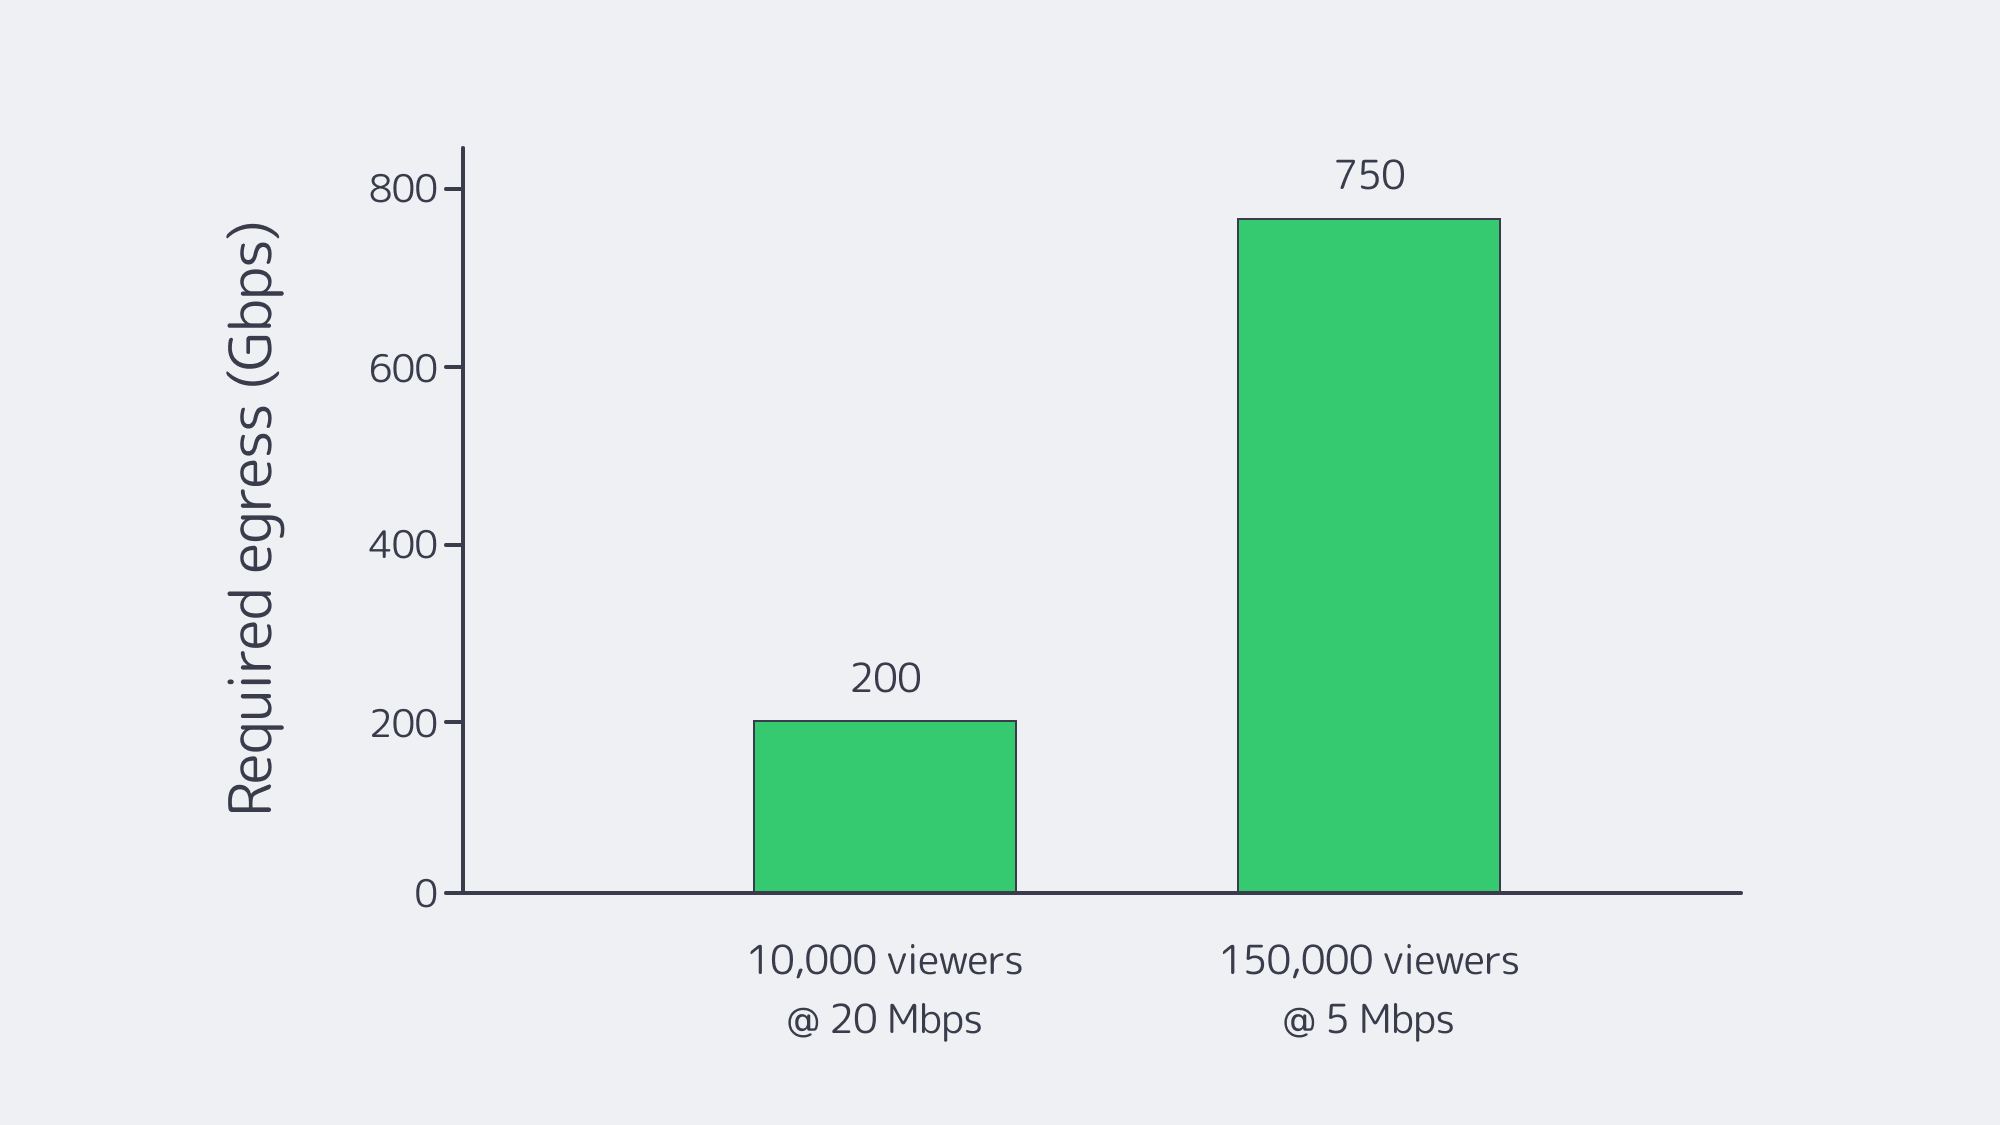
A pragmatic capacity rubric for live events:
- Work backward from concurrency × bitrate. Example: a marquee match with 150,000 viewers at 1080p (~5 Mbps) implies ~750 Gbps sustained across your edge, plus headroom for ABR steps and spikes.
- Provision origin ports for miss traffic and first‑segment storms. LL‑HLS/LL‑DASH means many tiny requests; NIC interrupt coalescing, TCP autotuning, and modern CC (BBR) help maintain microburst stability.
- Keep buffers honest. Target 2–5 second live latency end‑to‑end; avoid masking slow servers with oversized player buffers, which trades perceived “stability” for unacceptable delay.
- Monitor what viewers feel, not just what servers see. Track startup time, rebuffers per hour, edge cache‑hit ratio, and per‑region RTT to the player. Set alerts on deviation, not just thresholds.
A note on payload planning: at ~7 GB/hour per 4K viewer, turnover can be staggering on cross‑region peak nights. Build object storage and inter‑PoP replication policies that keep hot ladders close to viewers and cold renditions out of the way.
Choosing the Best Video Streaming Server Configuration
- CPU vs. GPU for encode/transcode. Software x264/x265 on high‑clock CPUs is flexible, but real‑time multi‑ladder pipelines often benefit from GPU offload (NVENC/AMF) to cap per‑channel latency.
- NICs and queues. Favor 10/25/40/100 GbE with sufficient RX/TX queues and RSS; pin interrupts and leave CPU headroom for packaging.
- NVMe everywhere. Manifests, parts, and recent segments should live on low‑latency NVMe to avoid I/O becoming your bottleneck.
- Network placement beats pure horsepower. A “big” server in a far‑away DC is worse for latency than a “right‑sized” box near the viewers behind a good CDN.
Melbicom supports these patterns with per‑server bandwidth up to 200 Gbps, 21 data centers for origins, and a CDN with 40 PoPs—so teams can pair the best server for streaming workloads with the right geography and delivery fabric.
Key Takeaways You Can Act On
- Place servers near demand. Stand up origins in the same continent as your biggest live cohorts; let the CDN handle the fan‑out.
- Engineer for the peak, not the average. Provision ports and hosts to absorb first‑minute storms; keep 20–30% headroom during events.
- Hit the latency budget. Design for 2–5 second live latency with LL‑HLS/LL‑DASH; verify via synthetic beacons from viewer ISPs.
- Remove single points of failure. Multi‑origin, multi‑region; automatic health‑checked failover; periodic game‑day drills.
- Watch what viewers feel. Startup delay and rebuffer minutes drive churn; know per‑region QoE every minute.
- Use infrastructure that scales with you. Melbicom offers 1000+ ready-to-go servers, 21 data centers, up to 200 Gbps per server, 40 CDN PoPs, and 24/7 support—the raw materials to keep latency tight and streams steady as you grow.
Powering a Seamless Live Experience?

Focus relentlessly on distance and determinism. Put deterministic performance (dedicated servers) where your encode, package, and origin cache must never stall; then erase distance with a CDN and edge placement aligned to your audience map. Use low‑latency ladders only when your end‑to‑end chain—from NVMe to NIC to route to edge—is tuned for microbursts. Finally, accept that failures will happen and practice the failovers until they are invisible to the viewer. Do that, and you’ll meet the modern bar for live streaming: ultra‑low latency, stable startup, and no buffering during the moments that matter.
Melbicom’s fit for live streaming
Build a low‑latency stack on dedicated origins and a global CDN. Our team can help size ports, place servers in the right metros, and get you online fast.