Your exact Qwen model version and concurrent requests should shape the build. Across dense and mixture-of-experts architectures, memory planning starts with resident model weights rather than active-parameter counts alone. Choose GPU count and VRAM for those weights, runtime overhead, and KV cache at your application’s useful context and peak request load.
Melbicom rents dedicated GPU servers and builds custom hardware around your preferred graphics cards, GPU count, and VRAM. Your build is ready in 3–5 business days, with host RAM, storage, and networking matched to the serving design. Choose the hardware combination that fits your model weights and sustained production request load.
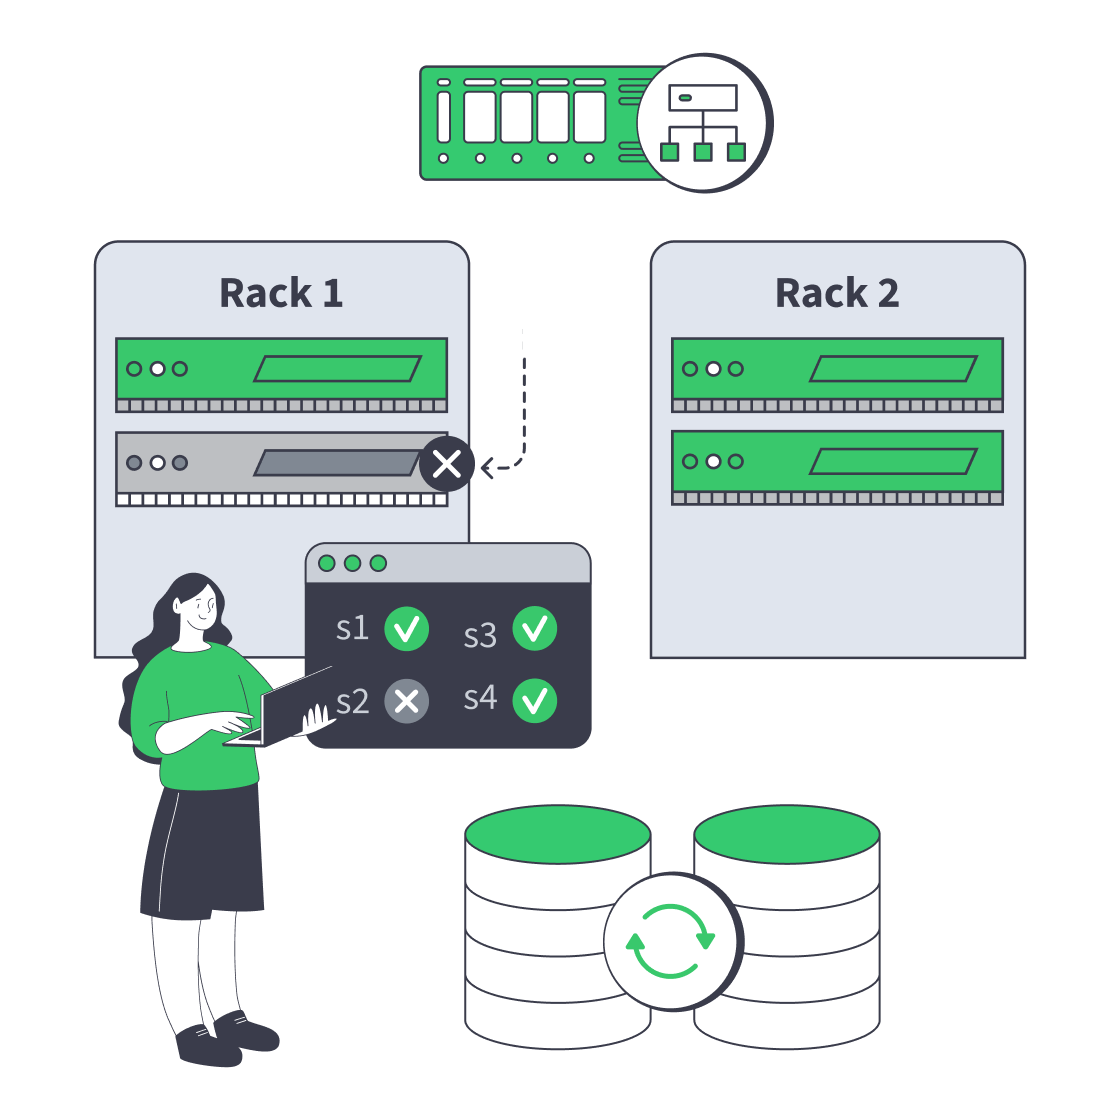
Reserved hardware gives your team control over the serving runtime, model changes, and application access. Allocate capacity to independent replicas or shard a model across devices with links sized for that design. Melbicom supports the infrastructure while you track response times and cost per useful response under sustained application traffic.