HPC hosting built around recurring compute runs
Rent dedicated servers for simulations, Monte Carlo runs, parameter sweeps, and job arrays, with CPU or GPU capacity, system memory, local NVMe, and data-transfer capacity aligned to each batch window.
Rent dedicated servers for simulations, Monte Carlo runs, parameter sweeps, and job arrays, with CPU or GPU capacity, system memory, local NVMe, and data-transfer capacity aligned to each batch window.
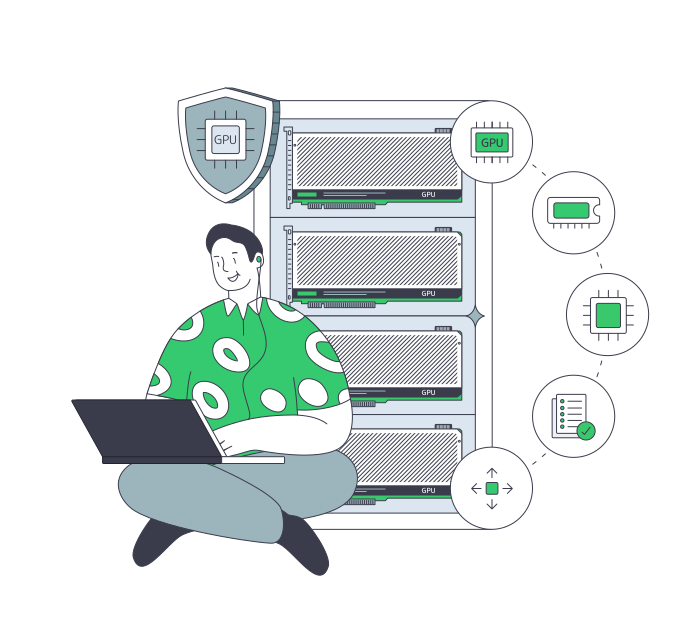

Set core count and per-core performance around task concurrency, solver behavior, and the required batch window.

Select supported accelerators and VRAM capacity for the solver path, target precision, and active working set.

Reserve host memory for active tasks, filesystem cache, scheduler overhead, and temporary allocations on the node.

Use local NVMe for concurrent scratch I/O across inputs, checkpoints, spill, and recurring batch outputs.
Recurring compute runs hit different limits. Monte Carlo arrays need task throughput; numerical models need system RAM and local scratch; accelerated solvers need a supported GPU path and enough VRAM. Representative job metrics show which ready node fits, how many tasks can run together, and where each batch window needs headroom.
Melbicom’s HPC server rental offers dedicated CPU and GPU nodes with whole-host compute, system memory, local NVMe, and transfer capacity matched to each job. Use a ready configuration for routine runs, or order preferred GPUs, VRAM, memory, and storage in 3–5 business days. A custom node keeps the hardware profile aligned with recurring batch demand over time.
Run independent arrays, memory-bound simulations, and GPU-accelerated solvers on distinct node profiles when their constraints differ. Your team controls the scheduler, runtime, libraries, and job policy while Melbicom supplies the physical capacity. Set node count and exchange patterns for communication-sensitive runs, keeping infrastructure spend tied to each workload.


Run independent scenarios in parallel with task slots, memory per process, and capacity sized for the batch window.

Run repeated parameter combinations on CPU or GPU nodes with per-task resources sized for the completion window.

Match cores, system memory, accelerators, and scratch to observed solver behavior across recurring engineering runs.
Run similar jobs with defined per-task resources, shared-node headroom, and local I/O capacity for each array.
Balance VRAM, host CPU, and system memory around the solver’s supported accelerator path and active working set.
Reserve node capacity for peak process memory, filesystem cache, temporary allocations, and concurrent tasks.

Use local NVMe for inputs, checkpoints, restart files, and outputs under concurrent I/O throughout recurring runs.

Run independent tasks across nodes with scheduler control over placement, priority, concurrency, and completion timing.