
Blog
Dedicated Servers for Decentralized Storage Networks
Decentralized storage puts familiar infrastructure demands on node operators. Whether you’re sealing data for a decentralized storage network or serving content over IPFS, your success depends on disk topology, memory headroom, and bandwidth that stays consistent under load. Dedicated servers give operators control over those resources and the software that uses them.
Choose Melbicom— 1100+ ready-to-go servers — 21 Tier III & IV data centers — Up to 200 Gbps per server |
 |
Decentralized Storage Nodes: Where the Real Bottlenecks Live
You can spin up a lightweight node on a spare machine, and for demos that’s fine. Professional decentralized storage providers have to sustain ingest and retrieval while keeping their storage healthy; Filecoin proving roles also have deadlines to meet. Shared-host resource contention can disrupt those tasks.
These constraints push operators toward dedicated servers: capacity must be dense and serviceable (drive swaps, predictable failure domains); I/O must be tiered (HDDs for bulk, SSD/NVMe for the hot path); memory must absorb caches and proof workloads without thrashing; and bandwidth must stay consistent when retrieval and gateway traffic spike.
Decentralized Blockchain Data Storage
Decentralized blockchain data storage combines storage providers with cryptographic verification and economic incentives. In Filecoin, storage proofs verify that providers retain data over time. Retrieval performance also depends on accessible data copies, disk I/O, and network capacity; storage proofs do not measure download speed.
When comparing centralized vs decentralized storage, look at who holds the data, how storage is verified, and who restores failed copies. Blockchain verification reduces reliance on provider reports; availability depends on storage and retrieval architecture.
How Does Decentralized Cloud Storage Work with Blockchain Technology?
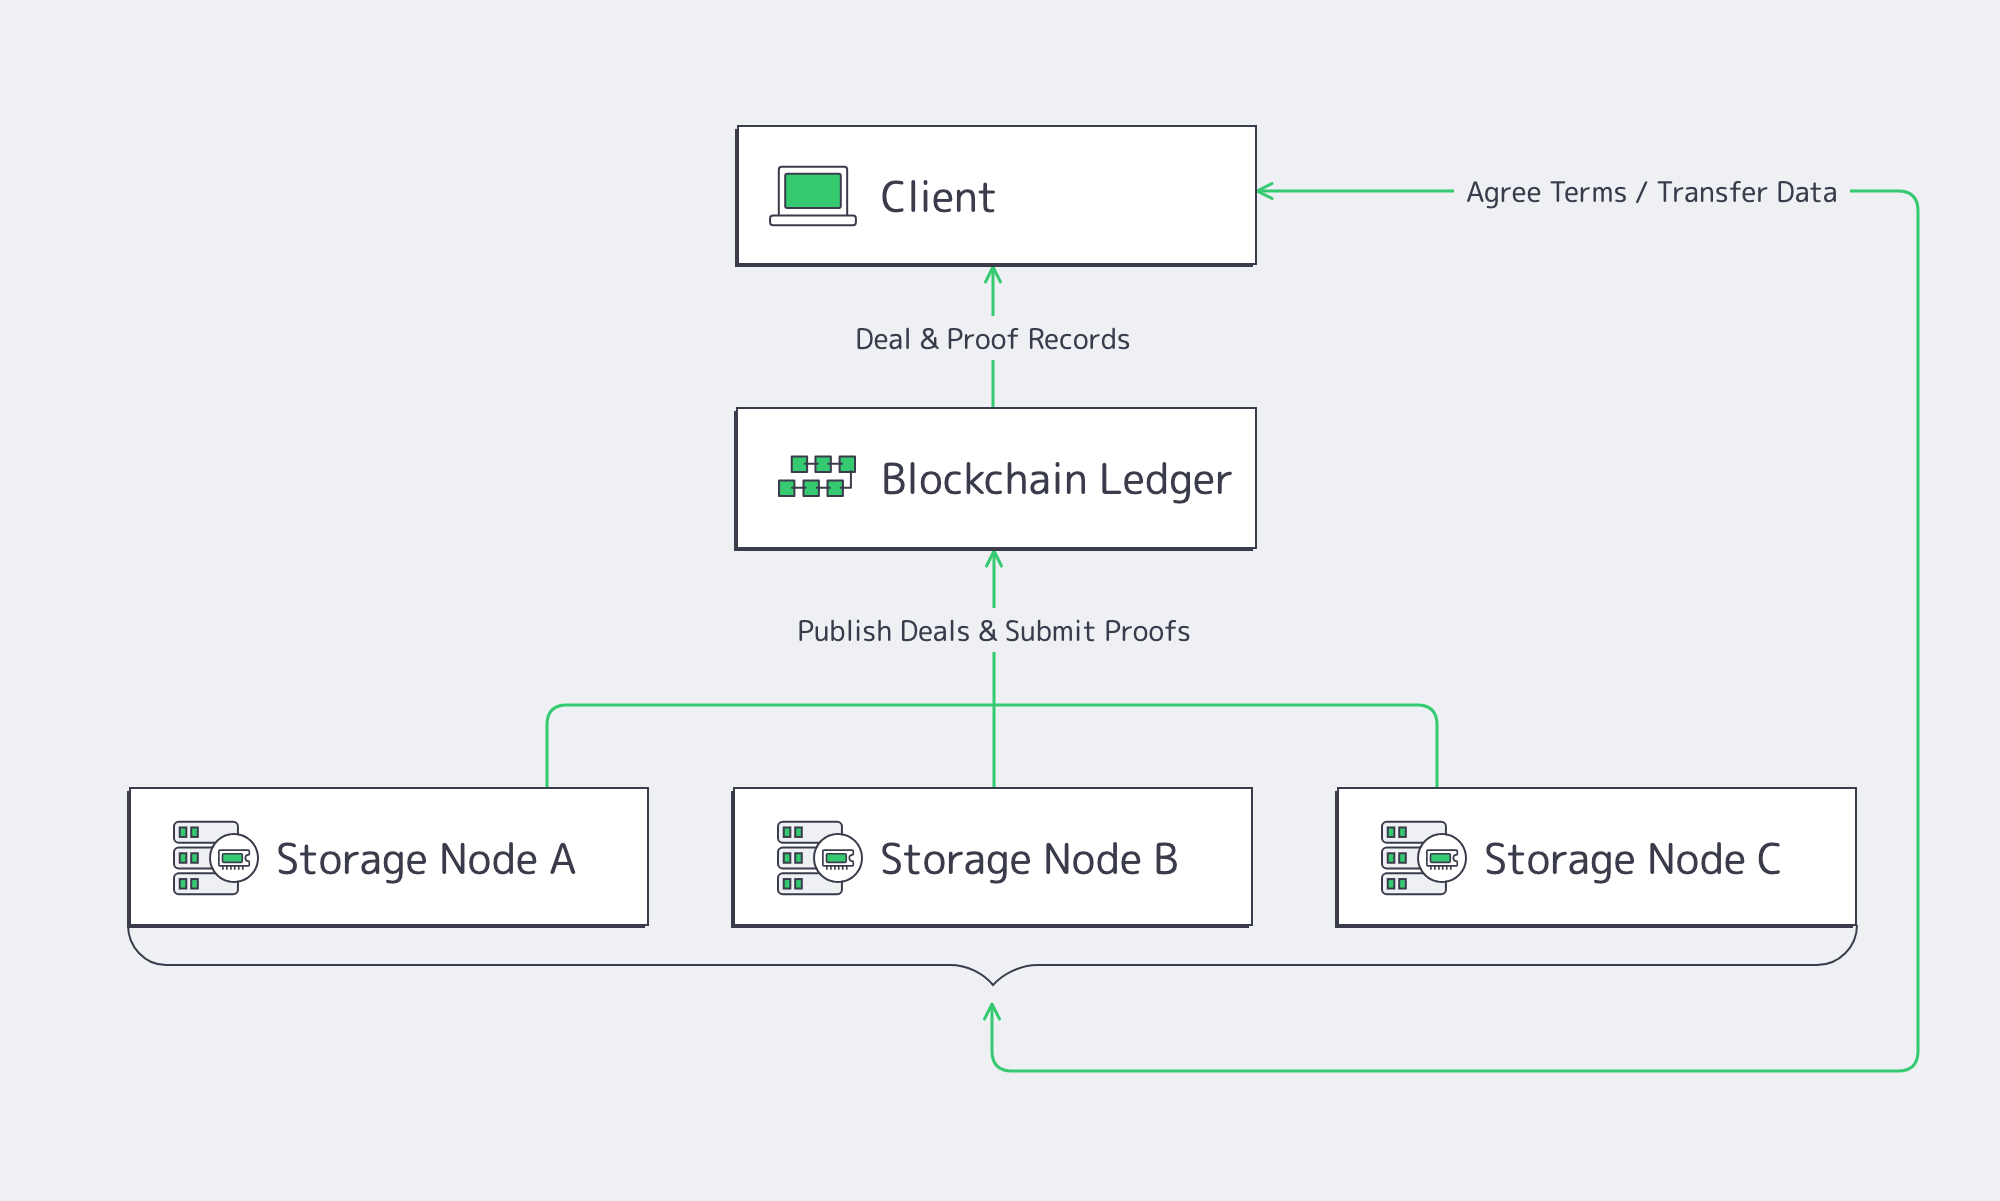
Decentralized cloud storage can use a blockchain to record agreements between clients and storage providers. Clients select providers and transfer files off-chain; providers submit proofs, and the blockchain applies the relevant payment and penalty rules. Filecoin uses this model, while IPFS content addressing and file transfer work without a blockchain.
Under the hood, the hardware workload depends on the storage role. Filecoin’s Proof of Replication (PoRep) path seals data and submits ongoing Proof of Spacetime (PoSt) proofs. Its Proof of Data Possession (PDP) path verifies storage without sealing, while IPFS nodes focus on retaining and serving content.
Building vs. Renting Storage Infrastructure
In a 2023 Filecoin ecosystem example, predefined hardware and hosted infrastructure were offered to shorten storage-provider deployment from 6–12 months to 6–8 weeks. Renting capacity can reduce the upfront hardware commitment and make expansion incremental.
A high‑performance dedicated server model fits that pattern. Instead of buying racks, switches, and PDUs, you rent single‑tenant machines in existing facilities, pay monthly, and scale out node fleets as protocol economics justify it.
| Factor | Build (CAPEX) | Rent (OPEX) |
|---|---|---|
| Upfront Cost | Large hardware purchase | Monthly or term spend |
| Deployment Time | Procurement + staging | Provisioning + node software setup |
| Hardware Refresh | You fund and execute upgrades | Upgrade the rental configuration; plan migrations |
| Scaling | Procure and deploy hardware | Add nodes as needed |
| Maintenance | Your ops burden | Provider: hardware. You: node software. |
| Best Fit | Stable, long‑run fleets | Fast expansion or protocol pilots |
IPFS Storage and Content Identification
IPFS flips the addressing model: clients request data by a content identifier (CID), not by its location. CIDs reflect encoded content blocks and enable integrity checks; changing the content changes the CID. Location-independent addressing does not conceal providers: IPFS publishes routing metadata linking content to the nodes that serve it.
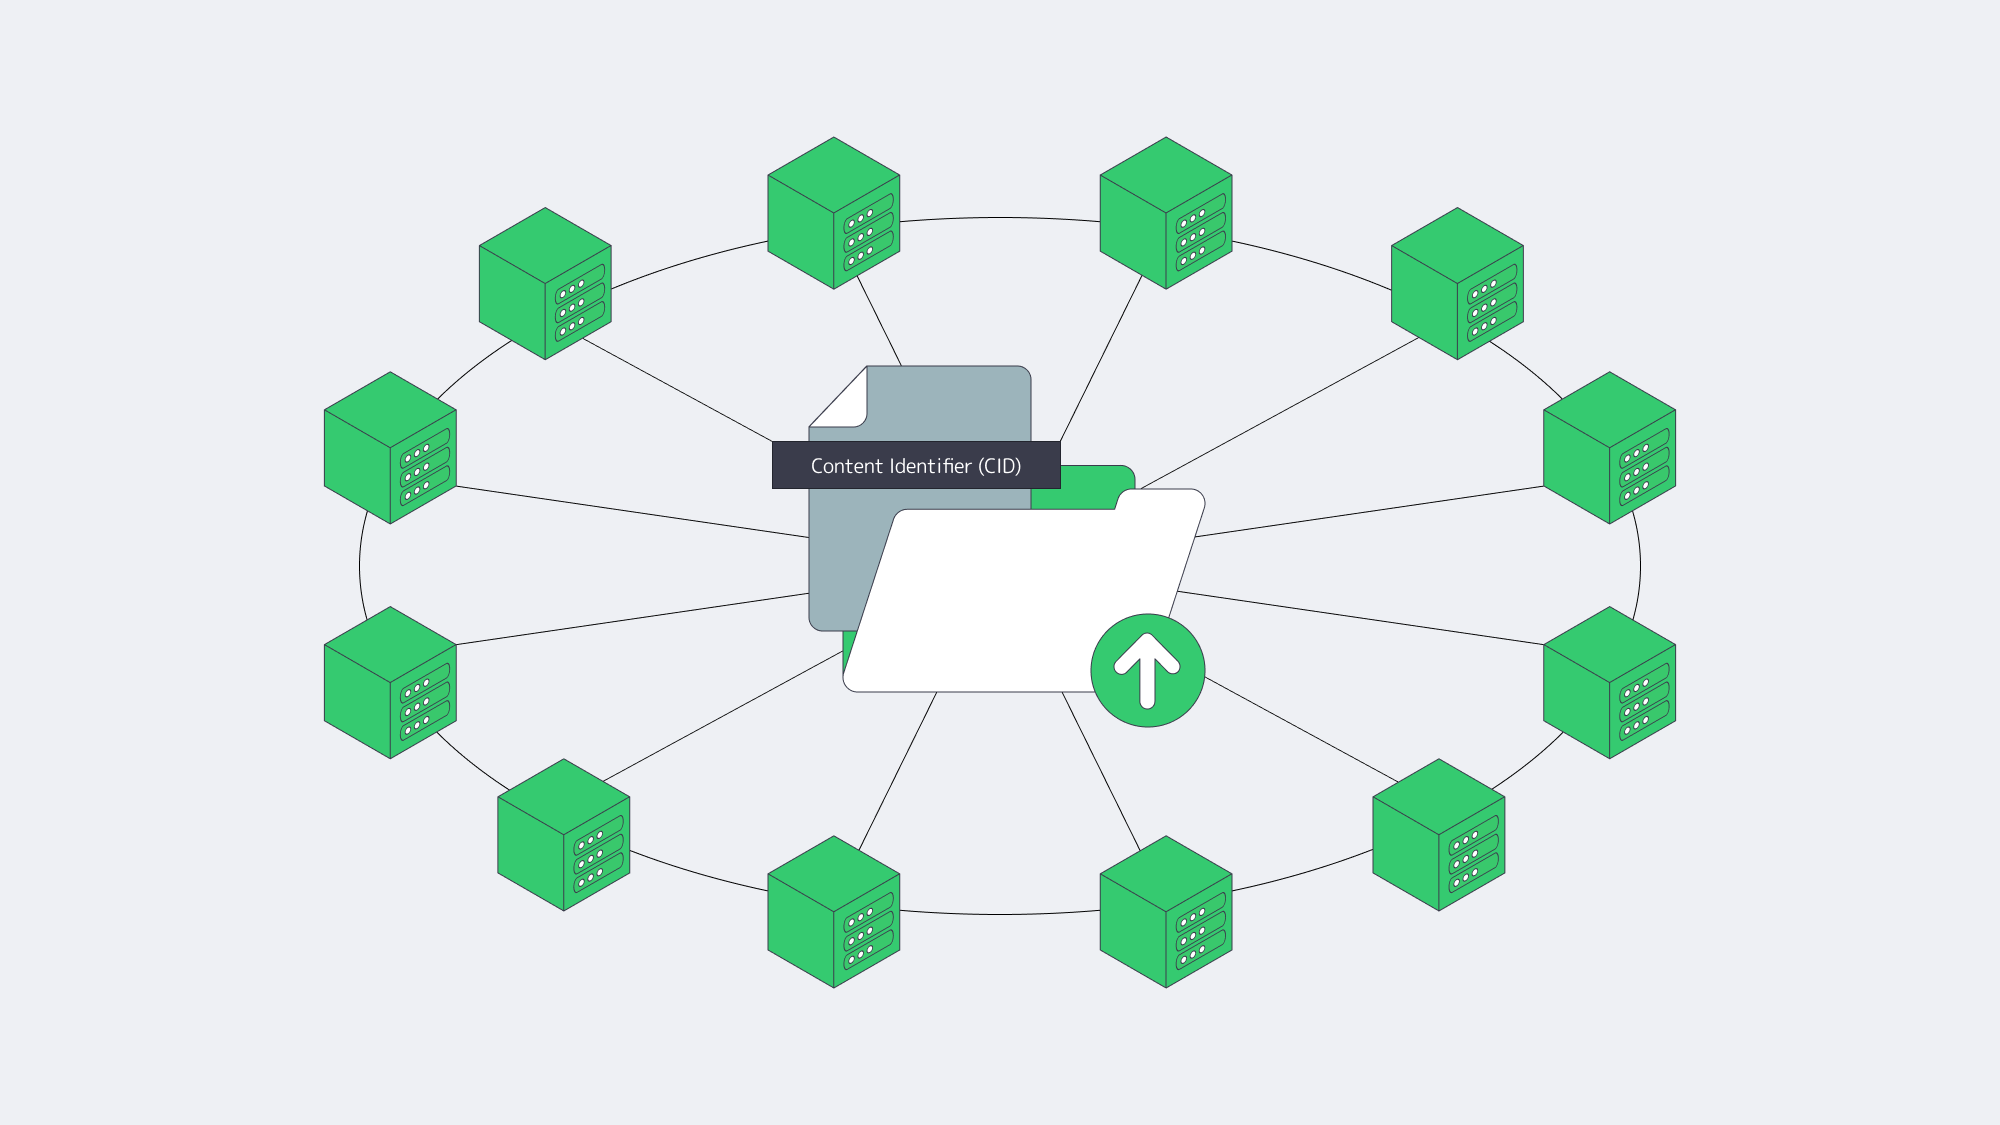
In practical terms, decentralized file storage performance often comes down to where and how you run your IPFS nodes and gateways. Popular content may be cached widely, but someone still has to pin it, serve it to gateways, and move blocks across the network. If those “someones” are running on underpowered hardware with weak connectivity, you’ll see it immediately as slow loads and timeouts.
Bringing IPFS into production follows the gateway guidance:
- Pinning content on dedicated nodes to retain stored copies through garbage collection.
- Running IPFS gateways that translate CID requests into HTTP responses.
- Placing CDNs in front of HTTP gateways to cache responses and absorb read bursts.
That’s exactly where dedicated servers shine: you can treat IPFS nodes as persistent origin servers with high‑bandwidth ports, local NVMe caches, and large HDD pools—then rely on a CDN to fan out global distribution.
Hardware Demands in Practice: Build a Node Like a Storage Appliance
The winning architecture is boring in the best way: isolate hot I/O from bulk capacity, avoid resource contention, and reserve headroom for concurrent work. For PoRep sealing, Lotus hardware requirements specify CPUs with SHA extensions and recommend GPU acceleration for demanding sealing and proving tasks.
Disk Design for Decentralized Storage
Bulk capacity still wants HDDs, but decentralized storage nodes are not just “a pile of disks.” Filecoin’s storage documentation separates sealed data used for proofs from unsealed copies used for fast retrieval, with distinct disk pools to prevent competing reads. The pattern is roughly:
- Fast NVMe for sealing scratch space, indices, and hot data.
- Dense HDD arrays for sealed sectors and archival payloads, plus separately sized retrieval copies.
- A topology that lets you replace failed drives without jeopardizing proof windows.
Memory for Proof Workloads and Metadata
Proof systems and high-throughput storage stacks punish tight memory budgets. Filecoin’s 1 PiB architecture for a PoRep/Lotus deployment allocates 256 GiB of RAM to a Lotus miner with local ZFS caching and 128 GiB to dedicated PoSt workers. With a separate storage server or NAS, the miner allocation drops to 128 GiB. Size sealing-worker memory separately for concurrent tasks.
Bandwidth for Decentralized Storage
Client onboarding consumes ingress bandwidth; retrieval and gateway responses consume egress. Replication and transfers between sealing and storage workers also load internal links. Size each path from its data volume, transfer window, and concurrent traffic.
For example, delivering 10 TB in four hours requires 10,000 GB × 8 bits/byte ÷ 14,400 s ≈ 5.56 Gbps of payload throughput, using decimal terabytes. A 10 Gbps port gives this transfer room for protocol overhead and concurrent traffic; the storage reads and end-to-end path must also sustain the required rate.
Melbicom’s Web3 hosting lets operators select dedicated-server CPU, memory, storage, and network resources for these roles. We provide the hardware and network; customers install and operate the storage clients, proof software, and gateways.
Web3 Storage Scales on the Same Basis as Every Other Storage System

Dedicated servers provide control over the resources that each storage role consumes. For Filecoin providers, IPFS gateways, and other decentralized storage roles, plan usable capacity, retrieval throughput, and failure recovery together.
Practical Recommendations for Storage Nodes
- Treat nodes as appliances, not pets. Standardize a small number of server “shapes” (e.g., sealing, storage, gateway) so you can scale and replace them predictably.
- Tier storage aggressively. Put sealing scratch space, indices, and hot data on NVMe; use HDD pools for bulk storage. Isolate sealed-sector proving reads from retrieval reads.
- Budget memory by role. Allow for concurrent proof tasks, the OS, observability, and caching—especially on sealing and proving nodes.
- Size bandwidth to your retrieval workload. Size egress for peak retrieval volumes and transfer windows; size client ingress and internal replication links separately.
- Plan for regional and provider diversity. Place retained copies across providers and regions to reduce shared failure risk; place gateways near users when latency matters.
Deploy Dedicated Nodes for Web3 Storage
Run decentralized storage on single-tenant servers with NVMe, high-capacity storage, and unmetered bandwidth options. Choose a configuration around your node role, usable capacity, and retrieval targets.